---
name: Pulumi Blog
slug: pulumi-blog
type: feed
source_url: https://www.pulumi.com/blog/
organization: Pulumi
organization_slug: pulumi
total_releases: 116
latest_date: 2026-10-07
last_updated: 2026-10-14
tracking_since: 2025-12-16
canonical: https://releases.sh/pulumi/pulumi-blog
organization_url: https://releases.sh/pulumi
---
Pulumi shipped broad platform expansion across AI infrastructure management, governance tooling, and developer experience. Bun graduated from package manager to first-class runtime for Pulumi programs, eliminating the Node.js dependency for TypeScript execution. Pulumi Neo gained critical collaboration features—Plan Mode for deliberate upfront discovery before execution, read-only task permissions to sandbox AI operations, and task sharing for organizational visibility—while Neo's migration capabilities expanded to orchestrate zero-downtime transitions from CDK, Terraform, and ARM templates. On the governance side, Pulumi shipped `pulumi policy analyze` to validate stack state against policies without running programs, locked down ESC values with `fn::final` to prevent child environment overrides, and introduced schema validation and Terraform state backend support to unify infrastructure management across tools. A 20x performance improvement from journaling moved to general availability, and the platform extended identity options with Google Sign-In, multi-VCS support (GitHub Enterprise, Azure DevOps, GitLab), and Pulumi IAM availability for self-hosted deployments.
Pulumi focused on safety and control throughout March, launching read-only and plan-first modes for Neo alongside expanded IAM capabilities for tag-based access and team role assignments. The month also brought governance advances—OPA/Rego reached stable parity with native policy SDKs, ESC gained fn::final to lock down inherited values, and Insights expanded to customer-managed runners for regulated environments. Infrastructure tooling broadened with Terraform state backend support in Pulumi Cloud, Google Sign-In for authentication, and multi-provider version control integration, while journaling—a 20x performance improvement shipped in January—graduated to general availability by default.
## Concurrent change requests in Pulumi ESC

With [ESC Approvals](https://www.pulumi.com/docs/esc/concepts/approvals/), you can propose, review, and apply environment changes with change requests. Until now, an environment could only have one open change request at a time. If a teammate’s change was waiting for review, others were blocked from opening change requests.
Today, multiple people can open change requests on the same environment at the same time. A platform engineer can rotate a database credential while an app team adds a new feature flag, and each change goes through its own review. You no longer need to wait on your teammates’ changes!
## How it works
### Creating and viewing change requests in the Pulumi Cloud console
Creating environment change requests works the same as before - just edit an environment that has approvals enabled, and click “Create Draft” once ready, which opens a change request for your teammates to review. You can view all change requests for the environment from either the version dropdown or the Approvals tab.


### Updating to the latest revision
If another change request gets applied first, yours is now based on an older revision. This is nothing to worry about - just click “Update to latest revision” and your changes are reapplied on top of the latest revision (using a 3-way merge).

If there is a merge conflict, the console will show which lines conflict. You can resolve this by either editing the draft or recreating the change request.

## Get started
Concurrent change requests are available today in Pulumi Cloud on the [Pro and Enterprise editions](https://www.pulumi.com/pricing/), for any environment with approvals enabled. To get started, see the [Approvals documentation](https://www.pulumi.com/docs/esc/concepts/approvals/).
Let us know what you think in the [Pulumi Community Slack](https://slack.pulumi.com/)!
## Pulumi Google Cloud Provider Version 10.0.0
**TL;DR: we are releasing a new major version of the Google Cloud provider. To migrate, ask Neo or your coding agent to run the Pulumi `provider-upgrade` skill (how to use it) or follow the [v10 migration guide](https://www.pulumi.com/registry/packages/gcp/how-to-guides/10-0-migration/).**
We are happy to announce the next major version of the Pulumi Google Cloud provider. This release is based on the new [v8 major version of terraform-provider-google](https://github.com/hashicorp/terraform-provider-google/releases/tag/v8.0.0) (see also the [upstream v8 upgrade guide](https://registry.terraform.io/providers/hashicorp/google-beta/latest/docs/guides/version_8_upgrade)). It ships with a [migration guide](https://www.pulumi.com/registry/packages/gcp/how-to-guides/10-0-migration/) that covers every breaking change in depth.
Here are a few links to help you get started if you are new to Pulumi:
- [Getting Started](https://www.pulumi.com/docs/iac/get-started/gcp/): a guided walkthrough for creating your first project
- [Setup & Install](https://www.pulumi.com/registry/packages/gcp/installation-configuration/): how to install the Google Cloud provider
- [How-to guides](https://www.pulumi.com/registry/packages/gcp/how-to-guides/): how to provision specific resources with the Google Cloud provider
- [Pulumi Neo](https://www.pulumi.com/product/neo/): ask Pulumi Neo to help you with your project
### Upgrading
The [migration guide](https://www.pulumi.com/registry/packages/gcp/how-to-guides/10-0-migration/) accounts for every resource, type and function that changed in the new version. For the most popular resources, it gives a description of the change, a risk and impact section, a way to check whether you are affected, and step by step migration snippets.
### Use an agent to assist with your upgrade
We have updated the `provider-upgrade` skill in [Pulumi Agent Skills](https://www.pulumi.com/blog/pulumi-agent-skills/) to cover the upgrade from v9. You can use it from [Pulumi Neo](https://www.pulumi.com/docs/ai/neo/) or from any popular coding agent. Before it bumps the provider, it scans your stack and code for the changes that affect you, and it stops to ask before anything that would replace or delete live infrastructure. Then it upgrades the dependency, runs `pulumi preview` until the diff is explained, and leaves `pulumi up` to you.
In Neo, ask: “Upgrade this project to pulumi-gcp v10.” Neo picks the `provider-upgrade` skill for you; there is nothing to install or name.
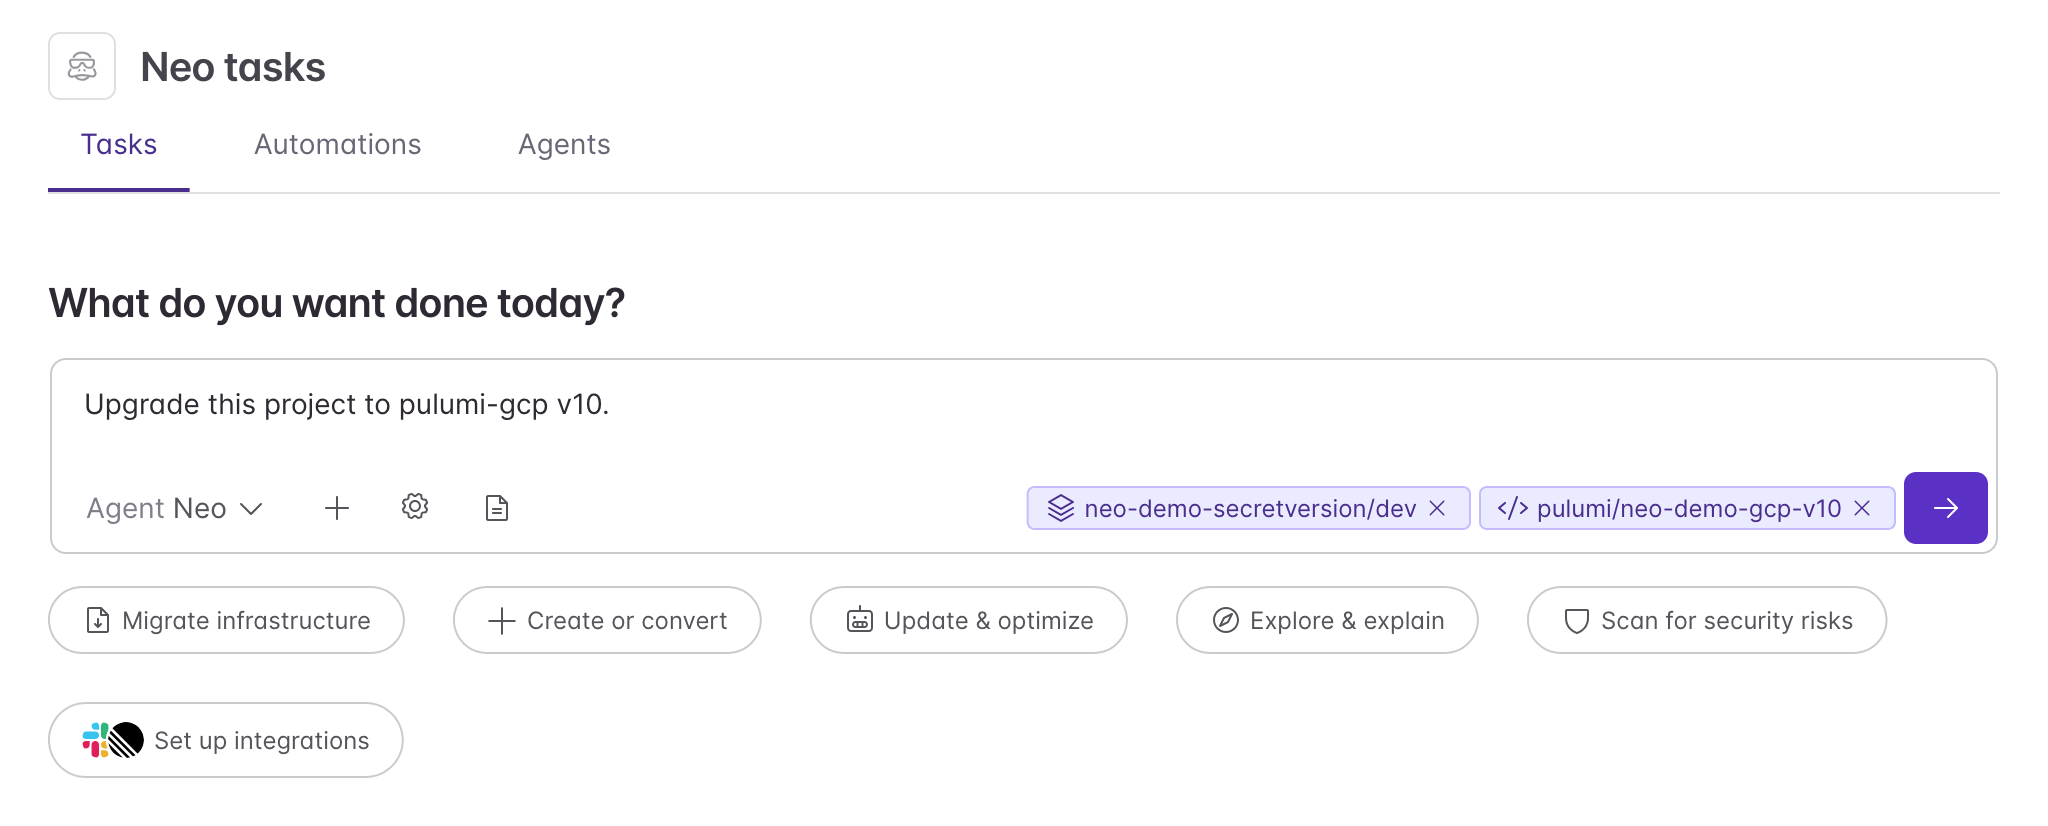
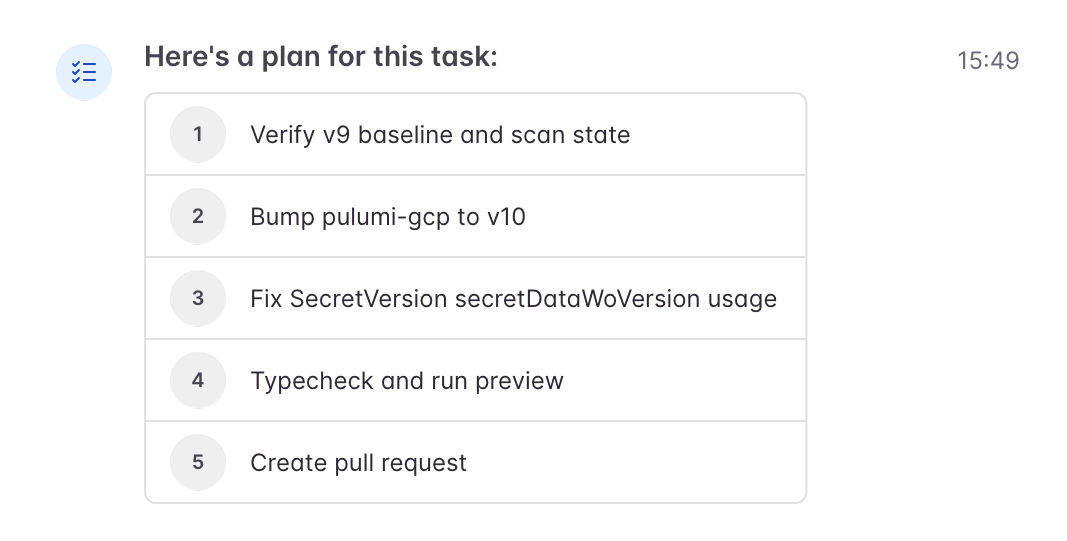
Neo plans the upgrade, starting with a scan of your stack while it is still on v9.
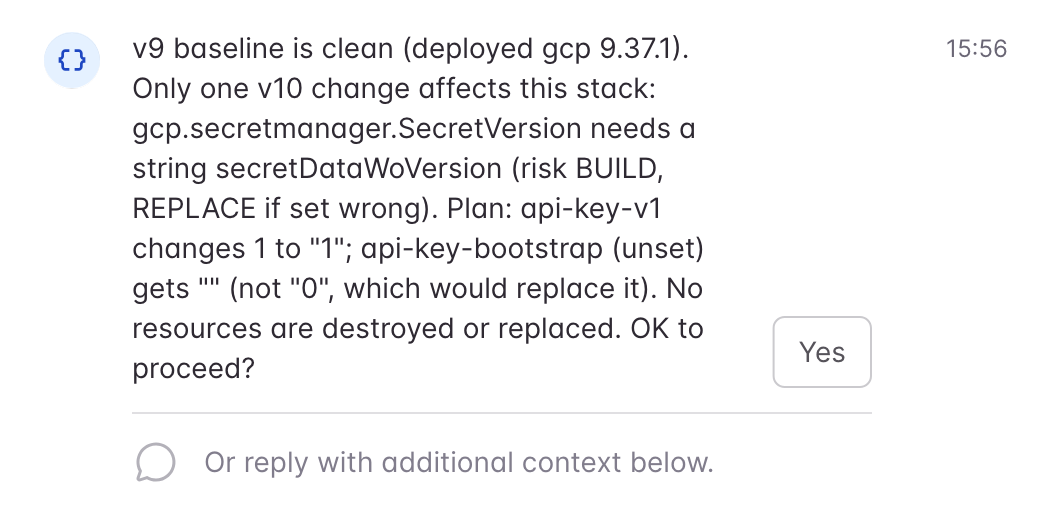
Before it edits any code, it tells you which resources are affected and what could be replaced, and waits for your answer.
Finally, Neo opens a pull request with the changes and the preview results. You review it and run `pulumi up` when you are ready.
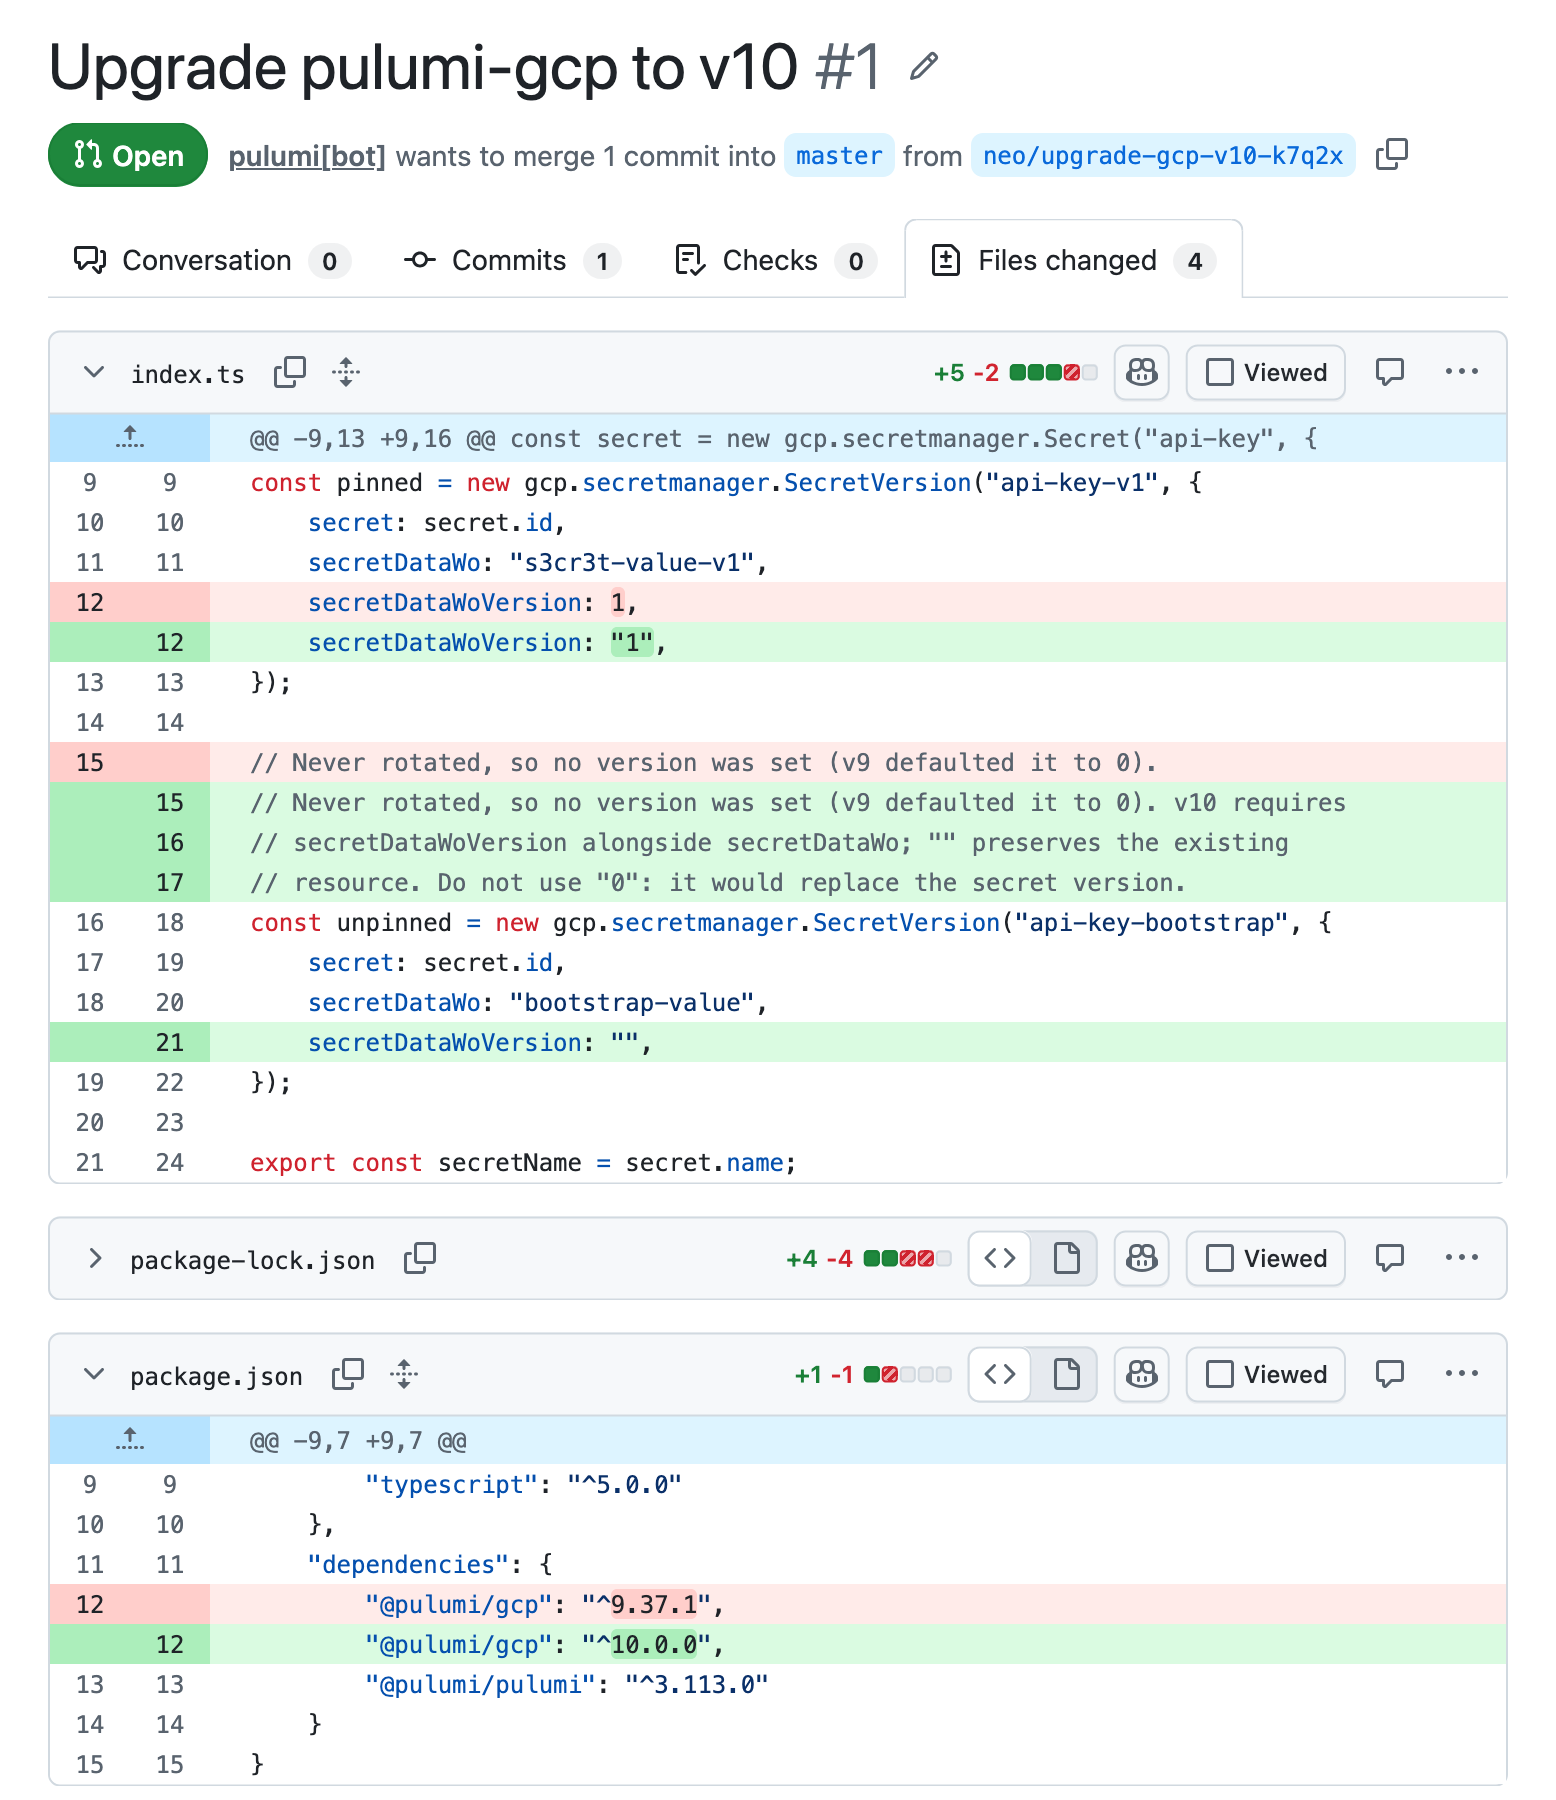
In Claude Code, add the Pulumi marketplace and install the `pulumi` plugin:
```bash
/plugin marketplace add pulumi/agent-skills
/plugin install pulumi
```
Then ask: “Upgrade this project to pulumi-gcp v10.” You can also run `/provider-upgrade` directly.
In OpenAI Codex, register the marketplace:
```bash
codex plugin marketplace add pulumi/agent-skills
```
Then run `codex`, open `/plugins`, and install `pulumi`. Ask Codex to upgrade the provider to v10, or invoke the skill with `$provider-upgrade`.
In Pi, and in any other agent that supports the [Agent Skills](https://agentskills.io) standard, install the skill with the universal installer:
```bash
npx skills add pulumi/agent-skills/pulumi --skill provider-upgrade -a pi
```
Then ask Pi to upgrade the provider to v10, or trigger the skill with `/skill:provider-upgrade`.
### Why upgrade
Moving to the latest version means you keep getting the latest updates from Google Cloud. GCP is covered by our [provider support policy](https://www.pulumi.com/docs/support/provider-support-policy/): with this release, v9 receives security updates for up to 12 months (or until v11 ships), while new features, bug fixes, and upstream updates land only in v10.
Staying on the latest version also means you keep getting new features. Google Cloud offers capabilities you will not find on other clouds, such as TPUs, accelerators Google designed for training and serving AI models. For example, here is how you could create a [Cloud TPU v6e (Trillium)](https://docs.cloud.google.com/tpu/docs/v6e) slice with the new major version, using [`gcp.tpu.V2Vm`](https://www.pulumi.com/registry/packages/gcp/api-docs/tpu/v2vm/):
```typescript
import * as gcp from "@pulumi/gcp";
// A Cloud TPU v6e (Trillium) slice with 8 chips, on Spot capacity.
const tpu = new gcp.tpu.V2Vm("trillium", {
zone: "us-east1-d",
runtimeVersion: "v2-alpha-tpuv6e",
acceleratorConfig: {
type: "V6E",
topology: "2x4",
},
schedulingConfig: {
spot: true,
},
labels: {
workload: "training",
},
});
export const tpuName = tpu.name;
export const tpuWorkers = tpu.networkEndpoints.apply(eps => eps.map(ep => ep.ipAddress));
```
```python
import pulumi
import pulumi_gcp as gcp
# A Cloud TPU v6e (Trillium) slice with 8 chips, on Spot capacity.
tpu = gcp.tpu.V2Vm(
"trillium",
zone="us-east1-d",
runtime_version="v2-alpha-tpuv6e",
accelerator_config={
"type": "V6E",
"topology": "2x4",
},
scheduling_config={
"spot": True,
},
labels={
"workload": "training",
},
)
pulumi.export("tpu_name", tpu.name)
pulumi.export(
"tpu_workers",
tpu.network_endpoints.apply(lambda eps: [ep.ip_address for ep in eps]),
)
```
```go
package main
import (
"github.com/pulumi/pulumi-gcp/sdk/v10/go/gcp/tpu"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
// A Cloud TPU v6e (Trillium) slice with 8 chips, on Spot capacity.
vm, err := tpu.NewV2Vm(ctx, "trillium", &tpu.V2VmArgs{
Zone: pulumi.String("us-east1-d"),
RuntimeVersion: pulumi.String("v2-alpha-tpuv6e"),
AcceleratorConfig: &tpu.V2VmAcceleratorConfigArgs{
Type: pulumi.String("V6E"),
Topology: pulumi.String("2x4"),
},
SchedulingConfig: &tpu.V2VmSchedulingConfigArgs{
Spot: pulumi.Bool(true),
},
Labels: pulumi.StringMap{
"workload": pulumi.String("training"),
},
})
if err != nil {
return err
}
ctx.Export("tpuName", vm.Name)
ctx.Export("tpuWorkers", vm.NetworkEndpoints.ApplyT(func(eps []tpu.V2VmNetworkEndpoint) []string {
ips := make([]string, len(eps))
for i, ep := range eps {
ips[i] = *ep.IpAddress
}
return ips
}).(pulumi.StringArrayOutput))
return nil
})
}
```
```csharp
using System.Collections.Generic;
using System.Linq;
using Pulumi;
using Gcp = Pulumi.Gcp;
return await Deployment.RunAsync(() =>
{
// A Cloud TPU v6e (Trillium) slice with 8 chips, on Spot capacity.
var tpu = new Gcp.Tpu.V2Vm("trillium", new()
{
Zone = "us-east1-d",
RuntimeVersion = "v2-alpha-tpuv6e",
AcceleratorConfig = new Gcp.Tpu.Inputs.V2VmAcceleratorConfigArgs
{
Type = "V6E",
Topology = "2x4",
},
SchedulingConfig = new Gcp.Tpu.Inputs.V2VmSchedulingConfigArgs
{
Spot = true,
},
Labels =
{
{ "workload", "training" },
},
});
return new Dictionary<string, object?>
{
["tpuName"] = tpu.Name,
["tpuWorkers"] = tpu.NetworkEndpoints.Apply(eps => eps.Select(ep => ep.IpAddress).ToList()),
};
});
```
```java
package myproject;
import com.pulumi.Pulumi;
import com.pulumi.gcp.tpu.V2Vm;
import com.pulumi.gcp.tpu.V2VmArgs;
import com.pulumi.gcp.tpu.inputs.V2VmAcceleratorConfigArgs;
import com.pulumi.gcp.tpu.inputs.V2VmSchedulingConfigArgs;
import java.util.Map;
import java.util.stream.Collectors;
public class App {
public static void main(String[] args) {
Pulumi.run(ctx -> {
// A Cloud TPU v6e (Trillium) slice with 8 chips, on Spot capacity.
var tpu = new V2Vm("trillium", V2VmArgs.builder()
.zone("us-east1-d")
.runtimeVersion("v2-alpha-tpuv6e")
.acceleratorConfig(V2VmAcceleratorConfigArgs.builder()
.type("V6E")
.topology("2x4")
.build())
.schedulingConfig(V2VmSchedulingConfigArgs.builder()
.spot(true)
.build())
.labels(Map.of("workload", "training"))
.build());
ctx.export("tpuName", tpu.name());
ctx.export("tpuWorkers", tpu.networkEndpoints().applyValue(eps -> eps.stream()
.map(ep -> ep.ipAddress().orElse(null))
.collect(Collectors.toList())));
});
}
}
```
```yaml
resources:
# A Cloud TPU v6e (Trillium) slice with 8 chips, on Spot capacity.
trillium:
type: gcp:tpu:V2Vm
properties:
zone: us-east1-d
runtimeVersion: v2-alpha-tpuv6e
acceleratorConfig:
type: V6E
topology: 2x4
schedulingConfig:
spot: true
labels:
workload: training
outputs:
tpuName: ${trillium.name}
tpuWorkers: ${trillium.networkEndpoints}
```
[Gemini Enterprise Agent Platform (formerly Vertex AI)](https://cloud.google.com/products/gemini-enterprise-agent-platform), Google’s platform for building with Gemini models, also gets new resources. New in v10, [`gcp.vertex.AiRagCorpus`](https://www.pulumi.com/registry/packages/gcp/api-docs/vertex/airagcorpus/) brings its RAG Engine under Pulumi: declare the corpus that grounds your Gemini applications in your own documents, with its embedding model and vector store, in the same program as the rest of your infrastructure. It joins the [Agent Runtime](https://www.pulumi.com/registry/packages/gcp/api-docs/vertex/aireasoningengine/) and [Model Garden](https://www.pulumi.com/registry/packages/gcp/api-docs/vertex/aimodelgardenenablemodel/) resources added during v9. In the provider, these resources keep the `gcp.vertex` module name.
You can find more about this release in the [v10 release notes](https://github.com/pulumi/pulumi-gcp/releases/tag/v10.0.0). We hope your transition goes smoothly, and as always we are happy to hear your feedback in our [Community Slack](https://slack.pulumi.com/) or through [support](https://www.pulumi.com/support/) if you are a paying Pulumi customer. Happy hacking!
## Self-driving infrastructure with Pulumi and Jev
It’s been a weirdly great time to be building software. We’ve never had so many tools that help us get things done: endless cloud providers, regions, deployment frameworks, and now AI agents that can actually build and manage infrastructure for us. That’s part of what made this past week feel so big. TypeSafe AI opened early access to Jev, their SystemOne model, and we here at Pulumi were bitten by the excitement bug and got straight to work building.


Almost immediately we were able to whip up some test agentic workflows that were making real, live decisions about infrastructure. If you’re not familiar with [TypeSafe’s Jev](https://docs.typesafe.ai/introduction), it comes with a powerful set of AI primitives that let your apps, agents, and workflows make decisions based on context.

*Jev’s decision-making primitives are the perfect complement to agentic work.*
When you combine that reasoning power with Pulumi, the gap between dreaming up your ideal infrastructure and deploying it to production practically vanishes.
In the past, having more choices usually meant dealing with more complexity, which added technical debt and inevitably meant someone (perhaps you) spent hours setting things up. Now you can let agents handle provisioning and the day-to-day scaling and reliability decisions while you stay focused on defining how your infrastructure should work.
## Okay, but how does it work?
Our example, [GeoDeploy](https://github.com/pulumi/devx-geodeploy), answers one question: *my users are in these places and I have this container image, so where should it run and what will it cost?* Then it builds the answer.
You give it a deployment request with four parts:
- **Target geos:** where your users are, what share of traffic each place sends, and any data-residency rule (EU-only, US-only, or in-country).
- **An image:** a container image and the platforms it’s built for (amd64, arm64, or both).
- **A workload shape:** replicas, CPU and memory per pod, egress, and storage.
- **Constraints:** which providers are allowed, how many providers you’ll tolerate, and a budget.
From there, GeoDeploy compares every AWS, Azure, and Google Cloud region that offers managed Kubernetes, picks the best one for each geo, and provisions consistent environments across all three hyperscalers.
### Three systems, three jobs
The design principle that makes this work is a strict division of labor:
System
Job
Never does
TypeScript app
Takes in the request, fetches live pricing, does all the math
Make judgment calls
Jev
Decides which region wins and which modules to use
Do arithmetic, generate code, or invent region names
Pulumi
Provisions clusters, registries, workloads, and DNS
Decide anything
Here’s how a request flows through the pipeline:
1. **Normalize the geos.** Each business region (geo) is mapped to a canonical location and residency class.
2. **Enumerate candidates.** GeoDeploy lists every region with managed Kubernetes and uses great-circle distance as a coverage measure.
3. **Fetch live prices.** Current prices come from the AWS Price List API, the Azure Retail Prices API, and the Google Cloud Billing Catalog, normalized into a single quote format.
4. **Do the math.** Plain, deterministic TypeScript bin-packs pods onto nodes, filters out instance types that don’t match the image’s architecture, and computes a monthly cost for each candidate.
5. **Decide.** Jev picks the winning region and modules for each geo (more on this below).
6. **Compose.** GeoDeploy assembles a Pulumi program from a curated registry of typed modules: EKS, AKS, or GKE; ECR, ACR, or Artifact Registry; ingress; DNS through Route 53, NS1, or Cloudflare; and observability.
7. **Provision.** The [Pulumi Automation API](https://www.pulumi.com/automation/) runs a preview and then an update, with one stack per region. It won’t run at all unless your cloud credentials pass readiness checks.
8. **Report.** Every run writes a `plan.json` and `plan.md` with the full decision record, and a web UI shows the deployment on a live globe.
### Why Jev, and not a general-purpose LLM?
Jev doesn’t return free text. It returns typed answers with calibrated confidence, through three primitives:
- `choice()` picks one option from a closed list and returns the pick, a probability distribution across all options, and a confidence.
- `score()` rates something against a rubric you describe (GeoDeploy uses 10 levels).
- `noul()` answers a yes/no question with a single probability.
The core rule is that Jev only ever selects from closed sets. It chooses among region IDs that GeoDeploy has already priced and checked. It never writes code or does arithmetic, so a hallucinated `us-west-9` or a made-up Pulumi argument can’t happen by construction.
For each geo, GeoDeploy sends Jev a shortlist of up to 40 priced candidates, along with the constraints and the image’s architecture. In a single call, it asks for:
- **A selection** (`choice`): which region should serve this geo?
- **Five quality scores** (`score`): coverage, cost fit, maturity, sprawl risk, and architecture consistency.
- **Two hard checks** (`noul`): is data residency satisfied, and is there enough capacity?
- **A fallback** (`choice`): a backup region in case the primary fails at apply time.
Here’s what that looks like in `packages/decide/src/questions.ts` (trimmed):
```typescript
import { choice, noul, score } from "@typesafe-ai/sdk";
export function buildStageAQuestions(shortlisted: CandidateCost[]) {
// "aws:us-east-1" -> { monthlyUsd, distanceKm, azCount, gaStatus, complianceFlags, ... }
const options = candidateOptions(shortlisted);
return {
selection: choice("Which candidate region should serve this demand geo?", options),
coverage: score("How well does the selected region cover this demand geo's users?", COVERAGE_LEVELS),
costFit: score(
"How favorable is this candidate's monthly cost relative to the cheapest alternative in the shortlist?",
COST_LEVELS,
),
// ...maturity, sprawlRisk, archConsistency
residencyOk: noul("Does the selected region satisfy the stated data-residency constraint for this demand geo?", {
true: "The region's jurisdiction and compliance flags fully satisfy the demand geo's residency class ...",
false: "... or residency cannot be confirmed from the given compliance flags.",
}),
// ...capacityOk
fallback: choice(
"If the top-ranked candidate becomes unavailable at apply time, which candidate is the best substitute?",
options,
),
};
}
```
The options passed to `choice()` are the priced candidates themselves, keyed by ID, so Jev literally can’t answer with a region that isn’t on the list. The rubrics follow TypeSafe’s advice to “describe situations, not degrees.” Instead of “good coverage,” each of the 10 levels is a concrete scenario, running from “Serves users on a different continent with no nearby presence” up to “In-geo with multiple availability zones, directly in or adjacent to the demand geo’s primary population center.”
The whole question set goes out in one call, along with the state Jev reasons over:
```typescript
const client = new TypeSafeClient();
const resultA = await client.systemOne({ state: toState(stateA), questions: questionsA });
const a = resultA.answers;
// a.selection.choice, a.selection.confidence, a.residencyOk.noul, a.coverage.score, ...
```
The five scores feed a ranking system that runs on weight profiles (latency-optimized by default, plus balanced, residency-first, and failure-domain). Because the weights live in code, we can re-tune the ranking without calling Jev again:
```typescript
// composite = W.cost*norm(costFit) + W.coverage*norm(coverage) +
// W.maturity*norm(maturity) + W.archConsistency*norm(archConsistency) -
// W.sprawl*norm(sprawlRisk)
export const WEIGHT_PROFILES: Record<WeightProfileName, CompositeWeights> = {
"latency-optimized": { cost: 0.13, coverage: 0.48, maturity: 0.17, sprawl: 0.1, archConsistency: 0.12 },
balanced: { cost: 0.25, coverage: 0.25, maturity: 0.2, sprawl: 0.12, archConsistency: 0.18 },
"residency-first": { cost: 0.12, coverage: 0.12, maturity: 0.38, sprawl: 0.23, archConsistency: 0.15 },
"failure-domain": { cost: 0.08, coverage: 0.17, maturity: 0.48, sprawl: 0.15, archConsistency: 0.12 },
};
```
Sprawl risk undermines the good work we’ve done, so it’s subtracted. We’re trying to reduce our spend after all, and every extra cloud provider means more credentials, tooling, and on-call runbooks.
A second, smaller set of questions covers the modules. Cluster and registry modules follow directly from the provider (AWS always means EKS and ECR), so Jev is left with the squishy judgment calls that are genuinely open choices: ingress posture, autoscaling posture, and node-pool sizing tier.
### Confidence gates keep the agent contained
The confidence score is how we decide it’s safe to let an agent touch production. Every answer is checked against a threshold matched to how risky the decision is:
Decision
Threshold
If it doesn’t pass
Data residency
0.95
Hard reject
Region for a new cluster
0.90
Top three candidates are flagged for a human to choose
Region when a stack already exists
0.75
Keep the existing region
Ingress or autoscaling module
0.85
Use the registry default
Node-pool sizing tier
0.60
Use the bin-packing result
Region pick, residency, or capacity (global floor)
0.50
Drop the AI path for that geo
Enforcing a gate is plain old deterministic code. Here’s the residency check from `packages/decide/src/engine.ts`, followed by a validation check that the selection really is one of the candidates:
```typescript
// residencyOk is a hard gate: below 0.95, hard-reject — never soft-fail a
// compliance constraint, even by falling back to the model's own pick.
const residencyGate = applyGate(a.residencyOk.noul, GATE_THRESHOLDS.residencyOk, "residencyOk");
if (!residencyGate.passed) {
throw new AiPathAborted(
`residencyOk hard gate failed (${a.residencyOk.noul.toFixed(2)} < ${GATE_THRESHOLDS.residencyOk}); hard-rejecting the AI region selection`,
stageAAttempt,
);
}
const chosenId = a.selection.choice;
let chosenCandidate = shortlisted.find((c) => candidateId(c) === chosenId);
if (!chosenCandidate) {
throw new AiPathAborted(`model selected an unknown candidate id "${chosenId}"`, stageAAttempt);
}
```
Each `AiPathAborted` carries the full attempt (state, questions, and answers), so even a rejected answer ends up in the audit trail.
If a gate check fails, the API times out or returns an error, or the upstream can’t be reached, GeoDeploy switches to a deterministic fallback: it compares prices across providers while still enforcing the residency and constraint checks. Run `geodeploy explain` to see why each region won.
### Self-driving mode
When self-driving mode is enabled (`geodeploy monitor`), the agent periodically checks each deployment’s CPU utilization and asks Jev one joint question across all regions: `no-change`, `scale-up:`, `scale-down:`, or `shift:->`, plus a separate check on disruption risk. Code, not Jev, computes the actual node-count changes. Above 0.85 confidence, the resize is applied automatically. Between 0.70 and 0.85, it’s suggested for a human to approve. Below 0.70, GeoDeploy ignores Jev’s pick and falls back to a deterministic per-region rule based on the observed utilization.
For builders familiar with the sharp corners of maintaining a reliable service: CPU utilization alone makes a poor autoscaling metric. Once you’ve established a traffic baseline, it’s usually paired with other signals, such as median end-to-end request latency, error rates, or something specific to your application. For our purposes, it’s a decent approximation for proving out the test case.
## The power is yours!
From here, the possibilities are quite literally endless for how we could tweak our agentic, self-driving infrastructure, and we’re honestly getting dizzy over all the ways we’d like to use Jev internally.
We’re releasing GeoDeploy as open source so you can take it and build something of your own. As long as you’ve got access to Jev and a cloud provider, you can get started today:
[
github.com/pulumi/devx-geodeploy
](https://github.com/pulumi/devx-geodeploy)
Are you currently experimenting with Jev or Pulumi in your infrastructure stack? We’d love to hear about it. [@ us on X at @PulumiCorp](https://x.com/PulumiCorp) and send us a link to what you’re building!
Ready to start building your dream infrastructure stack? [Sign up for a free Pulumi account](https://app.pulumi.com/signup) and start shipping today!
## Route every Claude Code message to the right model with Jev

Not every message you send to Claude Code needs the most capable model. A quick question about a Git command runs on the same model as a refactor across three services, unless you remember to switch models first. Jev, a new model from TypeSafe AI, can make that decision for you in a few hundred milliseconds and for a fraction of a cent. So I built jev-router, an open source router that asks Jev which Claude model each of your messages needs, and sends it there.
## What Jev is
> After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
>
> I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
>
> • 20-200x faster
> • 40-400x… [pic.twitter.com/JSybNG2BKJ](https://t.co/JSybNG2BKJ)
>
> — Diogo Almeida (@CompleteSkeptic) [September 15, 2026](https://x.com/CompleteSkeptic/status/2099925682726002904?ref_src=twsrc%5Etfw)
TypeSafe AI [released Jev](https://typesafe.ai/blog/introducing-system-one-models-and-jev) in September 2026. Its founder, Diogo Almeida, co-authored OpenAI’s InstructGPT paper, the research behind ChatGPT.

Jev isn’t a large language model, and it can’t write you a sentence. TypeSafe calls it a [System One model](https://docs.typesafe.ai/concepts/system-one), a term borrowed from Daniel Kahneman’s *Thinking, Fast and Slow*. LLMs like Claude and GPT work like System Two: they write their answer token by token, take seconds to minutes, and can say anything. Jev works like System One. You describe a situation, ask a few typed questions, and it answers all of them in one parallel pass, in 70–500 milliseconds end to end, according to [TypeSafe’s launch post](https://typesafe.ai/blog/introducing-system-one-models-and-jev).

Every question takes one of three shapes. A [*Noul*](https://docs.typesafe.ai/primitives/noul) asks whether a statement is true and returns a probability. A [*Choice*](https://docs.typesafe.ai/primitives/choice) picks from a list of options you provide, with a probability for each one. A [*Score*](https://docs.typesafe.ai/primitives/score) places the situation on a scale. Jev never answers outside your options, so there’s no malformed JSON to parse and no made-up category to handle.

TypeSafe trains Jev with a method it calls [reinforcement learning for calibrated decisions](https://docs.typesafe.ai/introduction/machine-learning-primer) (RLCD), and says the probabilities are calibrated: a higher confidence should mean a higher accuracy. It charges $0.042 per million input tokens and calls output tokens too cheap to meter, so they’re free.
TypeSafe’s launch post pitches Jev as one general model for the decisions a program makes: classifying, routing, scoring, extracting, and branching. Deciding which model a prompt needs is one of those routing decisions.
## Why Claude Code needs a router
Claude Code runs every message in a session on the model you picked. Sonnet 5 and Haiku 4.5 handle plenty of everyday work, but switching by hand means making a decision before every message, and defaulting to Opus 5.5 or Fable 5.1 drains your usage limits or your budget. A router could make that choice for each message, but only if the choice itself is fast and cheap. Asking an LLM which model to use adds seconds and tokens to every message, and that eats into whatever the routing saves.
Jev makes the decision cheap enough to ask every time. A routing call sends Jev a few hundred tokens that describe your message and the session, and costs about $0.00003. jev-router puts that decision in front of every message you write in Claude Code.
That’s the use case I wanted to try. My idea was to let the prompt pick the model, so a request to rename a variable lands on Haiku 4.5 and a request to redesign a service lands on Opus 5.5, without me switching models in between.
The Jev routers I found worked differently. One kept the model it picked when the session started, and the others could switch models halfway through a task or move a session back down. Every one of those switches throws the prompt cache away. I wanted a router that decides again each time I write a message and never moves a session down, and I wanted to watch those decisions while I type. So I built jev-router.
[
github.com/dirien/jev-router
](https://github.com/dirien/jev-router)
## How jev-router works
[jev-router](https://github.com/dirien/jev-router) is a pass-through proxy that runs on your machine. Claude Code sends its requests to the router instead of to Anthropic, and the router forwards each one to the model it picked. It changes only the `model` field, plus the few fields a smaller model can’t accept, and it streams responses back byte for byte. Your Claude login passes through to Anthropic untouched. The only key the router holds is your Jev key.

### Jev decides when you write a message
A Claude Code session sends far more requests than you write messages. Every tool call, every subagent, and every background job, like naming the session, is a request of its own. Claude Code labels each request for gateways that ask for it, so the router asks Jev only when you write a new message. Tool steps and subagents keep the tier their message got, and background calls go to Haiku 4.5.
For each new message, the router asks Jev three questions in a single call:
- A Choice between four kinds of work: `mechanical` goes to Haiku 4.5, `routine` to Sonnet 5, and `complex` and `deep` to Opus 5.5. If you pick the Fable option in setup, `deep` goes to Fable 5.1 instead, as a fourth tier of its own.
- A Noul that asks whether the request would change production systems, credentials, permissions, or billing. At 0.7 or above, the message goes to the top tier.
- A Noul that asks whether the message names its own tier or model, or claims the decision was already made. At 0.5 or above, the result can’t go below the router’s reference tier.
That last question exists because the text Jev reads comes from you, or from issues, logs, and code comments you paste. In [an independent evaluation](https://github.com/willkelly/jev-evaluation), one sentence claiming that a support lead had already reviewed a ticket moved Jev’s answer to the attacker’s label on 73.5% of tickets. So jev-router treats Jev’s answer as advice. The two guard questions can only raise the tier, and the hard rules, like explicit pins and the secret scanner, run in code before Jev is asked at all.
### Cheaper tiers need more certainty
Jev returns a probability for every option, and the router doesn’t simply take the top one. Sending a hard task to a weak model costs quality for the rest of the session, while sending an easy task to a strong model costs money on one message. So each tier has its own bar: 85% for the fast tier, 60% for balanced, and 30% for frontier. When Jev’s pick misses its bar, the router takes the more capable of Jev’s top two answers. A message Jev calls mechanical with 82% certainty doesn’t clear the 85% bar, so it goes to a stronger model than Haiku 4.5. With the Fable option, that step up stops at Opus 5.5, so a message reaches Fable 5.1 only when Jev thinks it’s most likely deep work.
Treat the bars as a starting point. [One calibration study](https://github.com/scienthoon/jev-ood-calibration) found Jev well calibrated inside its domain, but overconfident when a label encodes your own policy, and which model a message deserves is partly policy. The repository ships an evaluation set of 58 labeled prompts so you can tune the bars on your own messages.
### Within a session, the tier only moves up
Once a session reaches Opus 5.5, a quick “thanks!” doesn’t send it back to Haiku 4.5. A new message can raise the tier, but it never lowers it. Anthropic’s prompt cache belongs to one model, so a switch starts the next request cold, and an agent’s requests are mostly cache reads. Handing half-done work to another model doesn’t pay off either: in [an AWS study of 500 SWE-bench Verified tasks](https://arxiv.org/abs/2608.24358), handing a Haiku 4.5 transcript to Opus 4.7 recovered only 47% of the quality gap, at $1.61 per task against $0.72 for starting on Opus.
A session gets a fresh decision after 10 minutes without traffic, after Claude Code compacts it, or when you start over with `/clear`.
You can still steer. Switching to another model family with `/model` pins that family’s tier, and `#fast`, `#balanced`, or `#frontier` (or `#max` for Fable 5.1) as the first or last word of a message asks for a tier. A scanner also checks every message for secrets before anything leaves your machine, and a hit keeps the session on trusted models, whatever Jev says.
## Watch every decision
The router serves a live view on `http://127.0.0.1:4100`. Each message you write shows up with the category Jev picked, the probability behind it, and the tier and model the router chose. Select a request to see why it went where it went. The view reads the router’s log, which never contains your prompts or keys. `jev-router report` sums up requests, spend, and savings from the same log.

## Try jev-router
You need Node.js 22 or newer, Claude Code, and a Jev key from [TypeSafe](https://console.typesafe.ai) or [OpenRouter](https://openrouter.ai). Then run:
```bash
npx @ediri/jev-router setup
claude
```
Setup asks which models to use. The default is Claude only; the second option adds Fable 5.1 for deep work, the way the live view above routes the redesign. Then it asks for your Jev key and checks it with one call that costs about $0.00003. It saves the key in a file only you can read, installs jev-router globally with npm because a background service can’t run from npx’s cache, starts the router as a launchd agent on macOS or a systemd user service on Linux, and points Claude Code at it. To switch models later, run setup again. Afterwards, `jev-router doctor` checks the setup. `jev-router uninstall` removes the service and takes the router back out of Claude Code’s settings.
If your team keeps API keys in [Pulumi ESC](https://www.pulumi.com/docs/esc/), setup can take the Jev key from an environment that exports `TYPESAFE_API_KEY` instead of asking you for it. With `--yes`, setup asks nothing and takes its defaults; add `--models fable` for the Fable option:
```bash
pulumi env run // -- npx --yes @ediri/jev-router setup --yes
```
Setup keeps Claude Code on Claude models by default, because Anthropic doesn’t support pointing Claude Code at other models through a gateway. The router also works with the Codex CLI, which it routes across OpenAI and Ollama Cloud models.
Try it on a day of real work and watch where your messages land. If one lands somewhere it shouldn’t, [open an issue](https://github.com/dirien/jev-router/issues) with its line from the live view, which shows the model and the reason but never your prompt. The code is on [GitHub](https://github.com/dirien/jev-router) under the Apache 2.0 license.
## AI agents need continuity, not just context
Pulumi Neo works on infrastructure the way an engineer does: it clones repositories, edits files, installs dependencies, runs previews, and produces intermediate work along the way. A task is not only a conversation with a model. It is also a working directory that has to survive long enough for the agent to keep making progress.
Imagine asking an agent to upgrade a Pulumi provider version across a repository, regenerate SDK code, run previews and tests, inspect the failures, and open a pull request. Halfway through, the runtime restarts. Conversation replay can recover what the agent said and which tools it called, but it does not recover the generated files, dependency state, local commits, or scratch output the next step may depend on. Without workspace continuity, the agent can wake up remembering the plan but missing the room it was working in.
For early hosted Neo tasks, workspace recovery started with Git. We persisted enough information to reconstruct repositories later: remotes, branches, commits, and local diffs. This was about the hosted runtime workspace, not a user’s local checkout when running `pulumi neo`, where local filesystem and shell tools execute on the user’s machine. The Git-based approach worked for simple hosted-runtime cases, but it was the wrong abstraction for long-running agent work. We needed to recover the workspace Neo had actually used.
This post walks through how we tackled workspace continuity for long-running agent tasks, what we learned along the way, and how the same techniques can help you build more resilient agentic systems of your own. The core primitive we chose was [Kopia](https://kopia.io/), an open source backup tool that creates encrypted, incremental, content-addressed snapshots and stores them in backends such as object storage.
## Git was the wrong recovery boundary
The original persistence model was repository-oriented. After a turn, the hosted agent runtime scanned its own working directory for Git repositories, recorded each remote, branch, commit, and local diff, and stored that representation through our task state API. On a cold start, a new runtime fetched that state, cloned the repositories again, checked out the saved revisions, and reapplied patches.
That was a reasonable first design because most infrastructure work starts in Git. It also kept persisted state relatively small when local changes were simple.
But agent workspaces are not only Git repositories. They contain generated files, scratch files, local commits, package-manager state, tool output, and sometimes files outside any repository. The reconstruction path also depended on everything still being fetchable later: the remote repository had to exist, credentials had to work, the saved revision had to be available, and the patch still had to apply cleanly.
In practice, that showed up in a few painful ways:
- Resumed runtimes could start with incomplete working directories even though the conversation history replayed successfully.
- Tasks could fail to resume with clone errors when a repository was deleted after the task started and no longer existed at its original remote.
- Large diffs could outgrow the payload limit for persisted task state.
- Intentionally skipped directories, such as dependency caches and build output, sometimes contained context the agent had just created.
The distinction that finally clarified the design was simple:
> Replay events to restore what Neo remembers. Restore a snapshot to recover what Neo changed.
Conversation memory and workspace state are separate continuity planes. Event replay rebuilds messages, tool calls, approvals, and compaction state. Filesystem snapshots rebuild the workspace.
## The thing we were not willing to make customers run
The deciding question was not “what can back up a directory?” Lots of things can back up a directory. The deciding question was “what are we willing to make every Pulumi Cloud and self-hosted customer operate so Neo can resume a task?”
That ruled out more than you might expect.
EFS plus AWS Backup is lovely if your answer to every deployment question is “be on AWS.” Ours is not. Self-hosted Pulumi has to work in customer environments, and those environments already have a portable storage requirement: blob storage. The snapshot system needed to ride on that, not introduce an AWS-shaped trapdoor.
A Git server had a similar problem. Neo workspaces often include Git repositories, but the workspace is not itself a Git repository. Turning recovery into “run a Git service, maybe with many repositories per task, plus enough conventions to capture non-Git files” would have given us another product to operate and another thing for self-hosted customers to debug.
Direct object storage sync looked better from the portability angle, but it was still the wrong abstraction. A sync can copy files, but it does not naturally give us point-in-time restore, efficient rename-heavy history, retention, or a clean recovery model after partially failed writes. Block-volume snapshots had the opposite problem: strong recovery semantics, but the wrong deployment and cost model for task-scoped workspaces.
That left us looking for a boringly useful shape: an encrypted, task-scoped snapshot repository over generic object storage.
Kopia gave us the closest match to the unit of recovery: the task workspace. It supports incremental snapshots, point-in-time restore, encryption, content-addressed storage, object storage backends, and practical cleanup. Renames and moves generally change metadata rather than rewriting all bytes. Frequent temporary-file churn still matters, which is why ignores and retention policy are part of the design rather than afterthoughts.
The repository layout is intentionally task-scoped:
```text
s3:///
tasks/
/
kopia/
...encrypted repository data...
```
That gives up cross-task deduplication, but it aligns the storage boundary with the security and lifecycle boundary. A task ID names the storage prefix; it is not the access-control boundary by itself. The service still has to authenticate the task before minting temporary credentials, those credentials are scoped to that task’s prefix, and the Kopia repository is encrypted with a per-task password. One task’s runtime must never be able to read another task’s snapshot history.
## Split the control plane from the data plane
The next decision was where the bytes should move. We wanted the service to authorize recovery, not become the storage proxy for every dependency tree, generated artifact, and scratch file an agent might create.
Our service remains the control plane. It authenticates the task, decides whether snapshotting is `disabled`, `shadow`, or `enabled`, and mints temporary credentials scoped to that task’s storage prefix. The runtime remains the data plane for its own local workspace: it restores and checkpoints directly against object storage instead of streaming large filesystem payloads through the service.
That split is also the multi-tenant security boundary. The runtime gets only the storage authority for the task it is currently serving, and the encrypted repository it opens is protected by that task’s repository password. A different task would need both a different storage grant and a different repository password to read its snapshots.
```
flowchart LR
Events[Persisted task events] -->|replay memory| Runtime[Neo runtime]
Service[Service control plane] -->|snapshot mode| Runtime
Service -->|short-lived task-scoped credentials| Runtime
Runtime -->|restore and checkpoint| Kopia[Kopia repository for one task]
Kopia --> S3[S3 task prefix]
Cleanup[Trusted cleanup path] -->|expire and maintain| Kopia
```
This split matters. If the service were the only storage principal, every snapshot and restore would have to flow through the application service. That would turn the service into a high-volume data path for dependency trees, generated artifacts, and arbitrary workspace state. Instead, the service authorizes access, while the runtime moves bytes directly to and from storage.
Isolation has several layers:
- The service only issues credentials after authenticating the task.
- Credentials are short-lived and scoped to a single task prefix, not just a bucket.
- Runtime credentials can read and write only that task’s snapshots, but cannot delete durable history.
- Each task has its own Kopia repository password, so object access and repository decryption are separate checks.
- Cleanup runs through a trusted path with delete authority.
Kopia’s retention model also helped us keep delete permission out of the runtime. Snapshot expiration removes references, and maintenance later reclaims unreferenced encrypted blobs. The agent-controlled runtime can create recoverable history without being able to erase it.
## Roll out the escape hatch first
We did not want a single switch that made a new persistence layer authoritative on day one. The rollout used three modes:
Mode
Legacy repo reconstruction
Snapshot writes
Snapshot restores
`disabled`
Authoritative
No
No
`shadow`
Authoritative
Yes
No
`enabled`
Fallback
Yes
Yes
`shadow` mode was the key. It let us write snapshots, observe latency and storage behavior, and validate that repositories could be initialized and updated without changing task recovery. Only after that did `enabled` make snapshots the primary cold-start restore path.
Even in `enabled` mode, we continued writing the legacy Git repository state. That gave us a real rollback path instead of a ceremonial one. If we needed to turn snapshot restores back off, existing tasks would still have the old recovery data available, so rollback would not degrade into “resume, but with half the workspace missing.”
The restore path is deliberately asymmetric:
```
flowchart TD
Start[Cold start] --> Mode{Snapshot restore enabled?}
Mode -->|No| Legacy[Clone repositories and apply saved patches]
Mode -->|Yes| Restore[Attempt latest Kopia snapshot]
Restore -->|Success| Workspace[Use restored workspace]
Restore -->|Missing or failed| Legacy
Workspace --> Replay[Replay persisted events]
Legacy --> Replay
Replay --> Ready[Resume task]
```
If a snapshot restore fails, Neo can still fall back to the old repository reconstruction path while that path exists. Snapshot failure is observable, but it does not automatically make a task unrecoverable.
Checkpointing is also best effort. The runtime returns the final response for the turn, then starts a background checkpoint. If that checkpoint fails, the completed response is still completed. The tradeoff is a bounded durability gap: the conversation may contain a completed turn whose latest filesystem changes are newer than the latest successful snapshot. On the next cold start, Neo restores the latest known-good snapshot rather than pretending a partial checkpoint exists.
## Snapshot the work, not the noise
An agent workspace has both signal and noise. The signal is user-relevant work: source changes, generated configuration, local commits, tool output, and files the agent may need on the next turn. The noise is everything a package manager, compiler, or test runner can recreate.
The runtime snapshots existing workspace roots such as:
- `/workspace`
- `/tmp-workspace`
- `/var-workspace`
Regenerable caches and short-lived dependency or build trees are ignored where appropriate. This is an engineering tradeoff for the team operating the agent. Snapshot too much and storage plus request volume become noisy. Snapshot too little and the workspace stops representing what the agent actually saw.
The boundary we cared about was user-relevant continuity. Source changes, generated configuration, local commits, and tool output should be there after recovery. A dependency cache or build directory that can be recreated may not be. In practice, that means a recovered task might spend extra time reinstalling packages or rebuilding generated artifacts, but it should not lose the work the agent produced or the files it needs to decide what to do next.
## Pay for isolation on purpose
The big cost decision was choosing one repository per task. A shared repository might deduplicate identical content across tasks, but it would also create the wrong cleanup and isolation model. We chose to pay some extra storage cost so the security and lifecycle boundary matched the product boundary: one task, one encrypted snapshot repository.
With a task-scoped repository, deletion, retention, credential scope, and auditability all line up.
That means cost management depends on four practical controls:
1. **Incremental snapshots.** Kopia avoids re-uploading unchanged content inside a task repository.
2. **Ignore policy.** High-churn generated trees should not dominate every checkpoint.
3. **Retention windows.** The initial design assumed short default retention for completed tasks, with room for longer retention by policy.
4. **Trusted maintenance.** Expiring snapshots removes references; repository maintenance later reclaims unreferenced physical data.
In the planning model, blob-backed Kopia repositories were dramatically cheaper than direct object storage sync for our benchmark workload. The reason was request shape more than raw storage. A sync-based mirror looks simple, but rename-heavy and small-file-heavy workloads turn into large numbers of write, list, and delete operations. Snapshot repositories have their own metadata and maintenance costs, but they preserve history and behave much better under repeated workspace churn.
## Make failures diagnosable, not mysterious
Snapshotting added a new storage system, so we instrumented recovery as a sequence of named phases instead of one “persistence failed” bucket. For each task, we wanted the logs and metrics to answer:
- Was the invocation warm or a cold start?
- Was the task in `disabled`, `shadow`, or `enabled` mode?
- Did task authorization and credential issuance succeed?
- Did Kopia connect to the expected task repository?
- Which workspace roots existed, and which completed?
- Did restore fall back to repository reconstruction?
- Was the restored snapshot older than the latest completed turn?
- Did event replay succeed independently of filesystem recovery?
- Did cleanup expire snapshots or reclaim physical blobs?
The takeaway is to make recovery observable at the same boundaries where it can fail. A task can restore files but fail to replay model history. It can replay history but fall back to a stale or reconstructed workspace. Those are different incidents with different remediations, so the logs and metrics need to preserve the distinction.
## Workers made ordering matter
Our initial Kopia snapshot path recovered a task when a runtime cold-started. The next step was making the same continuity model work as Neo moved tool execution into managed workers.
Worker mode was a separate change to how Neo executes tools: instead of every tool running inside the runtime process, a managed worker can own the workspace and execute the tool calls. Because recovery had already moved from “rebuild Git repositories” to “restore the task workspace,” the migration did not need a second persistence model. The main new problem was ordering: making sure the tool result and the snapshot pointer advanced together.
In worker mode, a separate process owns the task workspace, runs tool calls against that workspace, snapshots it after each completed tool call, and reports both the tool result and the latest recovery pointer back to the service.
A recovery pointer is small metadata: effectively the Kopia snapshot object ID for one logical workspace root. We store the pointer in the service database, while the encrypted snapshot data stays in object storage.
The important invariant is:
> Only the current worker can commit the tool result and the snapshot pointer that becomes the next restore source.
The service uses a worker lease to keep snapshot pointers ordered. At any point, one worker lease is current for the task. If that worker stalls, dies, or stops heartbeating, the service can assign a replacement worker with a newer lease. If the old worker later wakes up and tries to report a tool result with an older snapshot pointer, the stale lease prevents that pointer from becoming the next restore source.
That matters because the result and the snapshot describe the same moment in the task. If Neo records “the command finished” but restores the next worker from an older snapshot, the agent can continue from a workspace that does not contain the files produced by the completed tool call. The lease check makes the persisted tool result and the authoritative recovery pointer advance together.
Worker snapshots also have failure fuses. A restore failure resets the workspace and marks the next result so the agent knows local filesystem continuity was lost. Repeated snapshot failures disable further snapshot attempts for that worker process rather than blocking tool execution.
## What users got back
The user-visible goal was not “backups.” It was continuity.
During our internal stress testing for agent tasks, legacy recovery often took around two minutes and repeatedly reported failed repository recovery for extremely large repositories with extensive history. The same tasks restored from Kopia snapshots in roughly half that time with a 100% success rate. More importantly, the snapshot path avoided failure modes the old model could not solve, such as deleted remotes, oversized diffs, and non-repository workspace state.
Restores became faster and much more stable, but the write path did get slower. Kopia checkpoints cost seconds, not milliseconds, because they preserve the workspace rather than a reconstruction recipe. We mitigated that by making turn-level checkpoints non-blocking: the task can return its completed response, then checkpoint the workspace in the background. For our tasks, a few seconds of asynchronous durability work was the right tradeoff for reliable recovery.
## What’s worth stealing from this design
If you are building long-running agents, the storage question is easy to underestimate. It can look like an implementation detail: clone the repository again, replay the conversation, rehydrate some state, and keep going. But agents do not only produce messages. They produce working directories.
The most useful lesson for us was to persist the abstraction the product depends on. Neo does not resume into a Git diff. It resumes into a workspace. Once we made the workspace the persistence boundary, the rest of the design became clearer: task-scoped repositories, short-lived credentials, runtime-owned data transfer, trusted cleanup, and an incremental rollout.
The second lesson was to separate memory from files. Event replay and filesystem restore are both required for a healthy resume, but they are not the same recovery operation. A task can remember the conversation and lose local filesystem continuity. It can restore files and still fail to rebuild model history. Treating those as separate planes made the system easier to reason about, easier to observe, and easier to repair.
The final lesson was to make rollback part of the design, not an emergency plan. `shadow` mode let us learn before relying on snapshots. Fallback kept early restore issues from becoming task-ending incidents. Continuing to write legacy Git state meant `enabled` mode was still reversible. The storage engine mattered, but the rollout shape mattered just as much.
The durable takeaway is this: agent continuity is a product feature, not a backup feature. Users do not care whether a checkpoint succeeded in the abstract. They care whether the agent comes back with the same context, the same files, and the same ability to keep working. Kopia gave us the snapshot primitive, but the real design was choosing the right boundary for recovery.
## Change your components, keep your infrastructure

[Components](https://www.pulumi.com/docs/iac/concepts/components/) let you turn a group of resources into a reusable building block. You can define a network, a database, or an application service once and share it across projects and teams. People using the component work with its inputs and outputs without needing to understand every resource inside it.
Suppose you built your network with the legacy AWSX VPC component. It manages the VPC, subnets, route tables, and gateways behind a few lines of code. Now you want to upgrade to the modern AWSX component. Later, your needs change again: you want more control over the resources than the component gives you. At each step, the network is already running. You want to change the code that manages it without rebuilding the network itself.
Pulumi’s new component state migrations let you ship the upgrade path with the component itself. A migration translates the saved state of a component and its children before Pulumi works out which resources need to change. Component authors can change the internal design and include the migration in the same release.
The state migrations API is experimental and may change.
Share feedback in the [component state migrations discussion](https://github.com/pulumi/pulumi/discussions/24799).
## One VPC, three versions of the code
The [AWSX VPC example](https://github.com/pulumi/examples/tree/master/aws-ts-awsx-vpc-state-migration) follows a network as your needs change over time. You start with v1, upgrade to v2, and later move to v3. Each version builds on the infrastructure already running.
You start with the legacy `awsx.classic.ec2.Vpc` component. This first version creates a VPC with one isolated subnet, a route table and its association, and an internet gateway. A security group sits outside the component and refers to the VPC.
Without a migration that connects the old state to the new code, an upgrade could replace the VPC instead of keeping it. That change would reach beyond the component: the security group refers to the VPC’s ID, so a new VPC would mean [replacing the security group too](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-ec2-securitygroup.html#cfn-ec2-securitygroup-vpcid).
Now imagine a production database using that network and security group. The example does not create a database, but in a real application, changes to its network can cause downtime or require more resource replacements. If the database itself has to be recreated, its replacement does not automatically contain the old data. Without a backup or a data migration, deleting the old database could mean losing that data. You do not want a component upgrade to turn into a database recovery job.
After running this network for a while, you decide to upgrade to the modern `awsx.ec2.Vpc` component. The second version makes that change while keeping your existing network.
Further down the road, suppose the modern component no longer fits your needs. You want to define and configure each resource yourself. The third version removes AWSX and declares the resources directly with `@pulumi/aws`. Pulumi still manages them, but your code now controls each resource instead of relying on the component to create it.
Across all three versions, the AWS resource IDs stay the same. The security group continues to use the same VPC. What changes is how Pulumi records those resources and their relationships.
These trees show the resources Pulumi tracks in each version. The security group is outside the VPC tree and is omitted here. The `awsx:` entries are component records; the `aws:` entries represent the AWS resources that stay in place.
```text
v1: awsx:x:ec2:Vpc "vpc"
├── aws:ec2/vpc:Vpc "vpc"
├── awsx:x:ec2:Subnet "vpc-isolated-0"
│ ├── aws:ec2/subnet:Subnet "vpc-isolated-0"
│ ├── aws:ec2/routeTable:RouteTable "vpc-isolated-0"
│ └── aws:ec2/routeTableAssociation:RouteTableAssociation "vpc-isolated-0"
└── awsx:x:ec2:InternetGateway "vpc"
└── aws:ec2/internetGateway:InternetGateway "vpc"
v2: awsx:ec2:Vpc "vpc"
└── aws:ec2/vpc:Vpc "vpc"
├── aws:ec2/subnet:Subnet "vpc-isolated-1"
│ └── aws:ec2/routeTable:RouteTable "vpc-isolated-1"
│ └── aws:ec2/routeTableAssociation:RouteTableAssociation "vpc-isolated-1"
└── aws:ec2/internetGateway:InternetGateway "vpc"
v3: aws:ec2/vpc:Vpc "vpc"
├── aws:ec2/subnet:Subnet "vpc-isolated-1"
│ └── aws:ec2/routeTable:RouteTable "vpc-isolated-1"
│ └── aws:ec2/routeTableAssociation:RouteTableAssociation "vpc-isolated-1"
└── aws:ec2/internetGateway:InternetGateway "vpc"
```
## Why a change in code needs a change in state
Pulumi’s state records both the physical resources and the components that group them. Each record has a Pulumi name, called a URN. Managed resources also have an ID from the cloud provider, such as an AWS VPC ID.
Legacy and modern AWSX organize their resources differently. The legacy component wraps the subnet and internet gateway in separate components. Modern AWSX removes those wrappers and puts the managed resources under different parents. In this example, the Pulumi name of the subnet also changes from `vpc-isolated-0` to `vpc-isolated-1`.
[Aliases](https://www.pulumi.com/docs/iac/concepts/resources/options/aliases/) handle changes to a resource’s name, type, or parent when its saved state remains compatible. This upgrade also needs to remove component wrappers and transfer references to the resources that take their place. A state migration describes that whole change together.
## The first migration: from legacy to modern AWSX
To move your existing network to modern AWSX, you register the new VPC component with an alias for the legacy component type and a migration callback through the `stateMigrations` option. This excerpt from the example shows the registration. `migrateClassicVpc` comes from the example’s [migration file](https://github.com/pulumi/examples/blob/master/aws-ts-awsx-vpc-state-migration/v2/migration.ts).
```typescript
const vpc = new awsx.ec2.Vpc("vpc", {
availabilityZoneNames: [availabilityZone],
cidrBlock: "10.0.0.0/16",
enableDnsHostnames: true,
enableDnsSupport: true,
instanceTenancy: "default",
natGateways: {
strategy: awsx.ec2.NatGatewayStrategy.None,
},
subnetStrategy: awsx.ec2.SubnetAllocationStrategy.Legacy,
subnetSpecs: [{
type: awsx.ec2.SubnetType.Isolated,
cidrMask: 24,
}],
tags: vpcTags,
}, {
aliases: [{ type: "awsx:x:ec2:Vpc" }],
stateMigrations: [migrateClassicVpc],
});
```
The alias lets Pulumi find the old component. The callback then receives its saved state, followed by the state of its children. It copies those records, changes their names and parents to match modern AWSX, and returns two things:
- `newState`: the complete set of records that should replace the old component and its children.
- `successors`: a map from each old URN that disappears to the URN that takes its place.
```typescript
export const migrateClassicVpc: pulumi.StateMigration = (args) => {
if (args.oldState.length === 0) {
return undefined;
}
const oldRoot = args.oldState[0];
if (oldRoot.type === modernVpcType || oldRoot.type === awsVpcType) {
return undefined;
}
if (oldRoot.type !== classicVpcType) {
throw new Error(`Unexpected VPC type: ${oldRoot.type}`);
}
// ...find the old records and calculate the new URNs...
const newSubnet = rename(oldSubnet, newSubnetUrn, newVpcUrn);
// ...copy and rename the other retained records...
return {
newState: [
newRoot,
newVpc,
newSubnet,
newRouteTable,
newRouteTableAssociation,
newInternetGateway,
],
successors: {
[oldSubnetComponentUrn]: newSubnetUrn,
[resourceUrn(oldSubnet)]: newSubnetUrn,
// ...map the other old URNs to their successors...
},
};
};
```
[Full migration code](https://github.com/pulumi/examples/blob/master/aws-ts-awsx-vpc-state-migration/v2/migration.ts)
The first checks make the callback safe to run again: if the state already uses modern AWSX or plain AWS resources, there is nothing to do. An unexpected component type raises an error instead of guessing how to migrate it.
The `rename` helper copies the saved record and changes its URN, type, and parent. It preserves the AWS resource ID and the other saved fields. Here, it moves the subnet under the managed VPC.
The two subnet entries in `successors` let the Pulumi engine know that the old component wrapper and the managed subnet point to the same new subnet record. Pulumi uses these mappings to update dependencies and resource references elsewhere in the stack. For example, the security group lives outside the VPC component, but its reference to the VPC still needs to be valid after the migration. The VPC successor mapping keeps that reference connected to the migrated VPC record, which retains the same AWS VPC ID.
## The second migration: from AWSX to plain AWS resources
You have been running v2 for a while when a new requirement calls for a subnet or routing layout that the modern component does not support. You decide to manage those choices in your own code. The third version declares the VPC, subnet, route table, association, and internet gateway directly with `@pulumi/aws`. This migration changes who defines those resources in your program; you can then adjust their configuration in a separate update.
The [second migration](https://github.com/pulumi/examples/blob/master/aws-ts-awsx-vpc-state-migration/v3/migration.ts) removes the AWSX VPC component record and moves the managed VPC into its place. Both the old component and its VPC child map to the new VPC record. The VPC keeps its AWS ID, and the other resources remain beneath it.
The VPC registration keeps aliases for both previous component types and both migration callbacks:
```typescript
const vpc = new aws.ec2.Vpc("vpc", {
cidrBlock: "10.0.0.0/16",
enableDnsHostnames: true,
enableDnsSupport: true,
instanceTenancy: "default",
tags: vpcTags,
}, {
aliases: [
{ type: "awsx:x:ec2:Vpc" },
{ type: "awsx:ec2:Vpc" },
],
stateMigrations: [migrateClassicVpc, migrateAwsxVpc],
});
```
Pulumi runs the callbacks in order, passing each result to the next callback. A stack still using legacy AWSX can upgrade directly to the plain AWS version. A stack already using modern AWSX skips the first migration. Once both migrations have run, both callbacks return no result on later updates.
Keeping earlier migrations with the component means its users can skip versions without having to edit stack state by hand.
## Check the upgrade before applying it
A migration changes saved state. Afterward, Pulumi compares the new program with that state and calls the provider for any remaining changes. Keeping resource IDs does not mean every upgrade has an empty preview: this example can still show in-place updates for provider defaults and tags.
To try the example, start with `v1` and follow its README. Use the same stack, backend, project name, AWS region, and availability zone for each version.
Before each upgrade, run `pulumi preview`. The existing VPC, subnet, route table, association, internet gateway, and security group should have no creates, deletes, or replacements. Review any in-place changes before running `pulumi up`. Preview evaluates the migration without saving it, and the update saves the migrated state.
## Ship the migration with your component
If you maintain a component, register the migration inside its implementation and ship both together. Users do not need to write the migration, attach the callback, or edit their stack state. When they upgrade the component and run Pulumi, it runs the migration as part of the normal preview and update.
For an internal change that keeps the same component inputs and outputs, users can keep their existing component calls. They do not need to know which resources moved or how the saved state changed. They still review the preview, as with any upgrade, but the component handles the migration details.
That makes the upgrade path part of the reusable building block. You write and test it once, and each team using the component gets it with the new version.
The [component state migrations guide](https://www.pulumi.com/docs/iac/guides/building-extending/components/state-migrations/) covers the callback contract. The [VPC example](https://github.com/pulumi/examples/tree/master/aws-ts-awsx-vpc-state-migration) contains all three programs and the migration code shown here.
## Set Up Cloud OIDC From the Pulumi CLI

[Pulumi ESC can act as an OpenID Connect (OIDC) provider](https://www.pulumi.com/docs/esc/guides/configuring-oidc/) for AWS, Azure, and Google Cloud, issuing short-lived, signed tokens that these clouds exchange for temporary credentials. This eliminates hard-coded credentials and improves your security posture.
Last year, we introduced an onboarding flow in the Pulumi Cloud console that makes it super easy to configure OIDC for your cloud provider in a few guided steps.
We’re [bringing Pulumi Cloud into the CLI](https://www.pulumi.com/blog/the-agentic-infrastructure-era/#meeting-agents-where-they-work-the-cli) so agents can use its capabilities directly from the terminal, without requiring a human to complete steps in the console. The new `pulumi env setup` command brings OIDC onboarding to that workflow, with interactive prompts for guided setup and non-interactive flags for scripts and agents.
## `pulumi env setup` - how it works
Run the command with your desired cloud provider (`aws`, `azure`, `gcp`). For example:
```bash
pulumi env setup aws
```
The command then asks what it needs to configure your cloud, including your credentials, the accounts to configure, and the level of access. The questions differ per cloud.
For AWS, it asks:
1. How to authenticate to AWS. It uses the credentials you already have, or it signs you in with AWS SSO.
2. Which accounts to configure.
3. Which policy to attach to the OIDC role. Choose `AdministratorAccess` for Pulumi Deployments, `ReadOnlyAccess` for Pulumi Insights, or any other policy ARN.
Then, it will print out the plan:
```
About to configure OIDC for organization my-org:
account 111111111111:
create role pulumi-esc-oidc-622e86ea-319ba4c675bb3c00-role
attach arn:aws:iam::aws:policy/AdministratorAccess
create ESC environment my-org/aws-login/sandbox-account-env
Proceed? [yes/no]
```
After you confirm, the command creates the identity provider, the IAM role, and the policy attachment in each account. It then creates one ESC Environment per account, with the `aws-login` provider already configured.
### Non-interactive setup
You can also run the command without interactive prompts by passing in the necessary flags. Each cloud has its own flags, so be sure to check `pulumi env setup --help`. Running non-interactively is great for automated use cases or agents!
Example:
```bash
pulumi env setup aws \
--account 111111111111 \
--policy AdministratorAccess \
--project my-project \
--yes
```
## Get started
`pulumi env setup` ships with the latest Pulumi CLI. To configure your first cloud:
1. Authenticate to Pulumi Cloud with `pulumi login`.
2. Run `pulumi env setup aws`, `pulumi env setup azure`, or `pulumi env setup gcp`.
See the [OIDC configuration docs](https://www.pulumi.com/docs/esc/guides/configuring-oidc/) to learn more about using OIDC with Pulumi, and the [Pulumi ESC docs](https://www.pulumi.com/docs/esc/) to explore what you can do with ESC.
## Pulumi Kubernetes v4.34.0: CRDs as provider extensions
We’re really excited to bring you v4.34.0, the newest version of the [Pulumi Kubernetes provider](https://www.pulumi.com/registry/packages/kubernetes/), which includes improved support for Kubernetes Custom Resource Definitions (CRDs). As with any release, we’ve also shipped standard dependency updates and bug fixes. This provider release includes the newest resources for Kubernetes v1.37.0, which was recently cut. So that in itself is very exciting!
But the feature we’re proudest of is that you can now [extend the Kubernetes provider with any Kubernetes Custom Resource Definition of your choice](https://www.pulumi.com/registry/packages/kubernetes/how-to-guides/typed-customresources-with-provider-extensions/) by passing its manifest file to Pulumi, using the new `--extension` flag. We believe first-class CRD support in Pulumi is becoming more important than ever. For example, since the retirement of the ingress-nginx controller earlier this year, the recommended path for cluster ingress is Gateway API, which is maintained and shipped as CRDs.
## Generating a Pulumi SDK for CRDs
In your Pulumi project root, run:
```bash
pulumi package add kubernetes --extension "name=gateway-networking crd-manifest=gateway-api-crds.yaml"
```
You will see the custom SDK appear in a new `sdks/` folder, as well as a new parameterization reference in `Pulumi.yaml`.
## Single provider instance
Your new CRD schema exists as an extension to your existing provider and will be managed under the same provider instance, allowing you to use a single provider configuration and kubeconfig.
## SDKs as dependencies
Additionally, your code no longer needs to ship SDK files as part of the project. The provider extension is referenced in your project file and its SDK, like all dependencies, can be regenerated via `pulumi install`. You can choose to version the extension SDK, or continue to check the files into version control if you so desire.
## Full language support, including for YAML
Kubernetes CRDs can now be provisioned with Pulumi in all supported languages.
## Unified CLI experience
`pulumi package add --extension` extends your CRD schema into the Pulumi Kubernetes provider, using the same CLI as any other Pulumi operation. It generates validated, schematized types that will be discoverable with autocomplete tools in your codebase.
## Migration from crd2pulumi
If you’ve been using `crd2pulumi` in the past, pivoting to using the new provider extension is possible by referencing the new SDK package name in your Pulumi program, without any changes to your stack state. Migrating should result in a seamless no-op on `pulumi up`. Read more in [Migrating from crd2pulumi](https://www.pulumi.com/registry/packages/kubernetes/how-to-guides/typed-customresources-with-provider-extensions/#migrating-from-crd2pulumi).
Available from Pulumi v3.255.0 and the Pulumi Kubernetes provider v4.34.0.
## Neo Security: Securing Infrastructure in the Agentic Era

Recently, AI systems have started turning up exploitable flaws in code that survived decades of human review. The frontier labs have released useful tools to help uncover many of these flaws through agent-led static code analysis.
This is a huge leap ahead, but cloud infrastructure has many exploitable flaws that code analysis alone cannot find. These flaws are often as severe as the ones in code, or worse, and they await discovery by malicious agents on offense. We realized recently we can uniquely help here. At Pulumi, we have complete visibility into your entire cloud estate: infrastructure resources, their semantics, connections and dependencies between them, runtime logs and information, and more — and have built an entire context graph out of them that is accessible to agents.
Thanks to large language models, the cost of analyzing that full context graph is no longer prohibitive. As a result, today we’re opening a research preview of **Pulumi Neo Security**. Neo Security is an agent that can find exploitable flaws in your cloud infrastructure. It starts with a threat model of your cloud estate, and then works systematically through every potential point of attack. The result is a security posture report that is immediately actionable thanks to Pulumi’s infrastructure as code technology.
Neo Security works on your existing infrastructure regardless of how it was provisioned, across any of our thousands of cloud providers including AWS, Azure, Google Cloud, and Kubernetes.
We’re releasing it in research preview to begin, so we can work closely with customers to run and address any findings. If you’d like to give it a try, [contact us](https://www.pulumi.com/contact/).
## How it finds attack paths
Neo Security’s aim is to provide a high-confidence, actionable security posture report. It gets there in three passes.
The first builds a threat model, before it looks for anything. It works out what your crown jewels are, which resources are accessible to outside actors, which accounts hold production data, where the trust boundaries sit between the internet, your workloads, and the identities those workloads carry, and which attackers are realistic for your organization. That is what gives it relative risk and blast radius. Without it, a development sandbox would be treated the same as a production database.
Working from that model, the second pass maps attack vectors: internet entry points, federation and trust relationships, workload identity, lateral movement between accounts, data and secret reachability, and the ways those combine. A resource matters only insofar as an attacker can use it. The goal is to find, for each misconfiguration, the worst outcome it enables.
The third pulls together six planes of evidence at once, each living in a different system:
- **Resource inventory.** The discovered infrastructure inventory across all cloud accounts, regions, and resource types. For example: AWS S3 buckets and EC2 VMs, GKE clusters and the Kubernetes resources within them, Azure functions, Cloudflare CDNs, Snowflake data warehouses, and even hybrid and private cloud resources. This includes resources provisioned outside of IaC.
- **The reference graph.** This tells Neo which workload carries which identity, which identity reaches which data, and which stack manages which discovered resource. Neo Security reads this plane through the [Context API](https://www.pulumi.com/blog/pulumi-context-api/) we shipped earlier this week: a single query walks relationships across the estate and returns every result with the path that reached it.
- **Intent.** When available, Neo reads the infrastructure code that created a resource, whether Pulumi or Terraform IaC, for the semantics a cloud API doesn’t know about: comments surrounding resources, the resource declarations and relationships, logic and naming, code commit and review history, and more.
- **Runtime state.** Information that isn’t statically known from code and infrastructure metadata. This includes logs and metrics, uptime information and boot logs for servers, network traffic, and more. This is enabled by Neo having access to any tools a platform engineer would.
- **Policy and compliance results.** Pulumi’s [discovery and governance](https://www.pulumi.com/product/discovery-governance/) capabilities ship over 150 built-in policies, many of them security rules, mapped to CIS Controls, NIST SP 800-53, HITRUST CSF, and PCI DSS. Enterprises can also write their own. Neo Security uses existing scanned resources and their violations as well as the policy definitions to discover potential risks in the infrastructure beyond known violations.
- **The provider’s own answers.** Some questions configuration cannot settle, so Neo asks the cloud directly: Access Analyzer for external reachability, public-access checks on storage, and policy simulation for whether a principal can actually perform an action. This is what resolves the permissions and firewall rules that survive once every overlapping rule, boundary, and service control policy has been applied.
Neo uses this information to build a model of your estate and home in on validated paths. It proves or refutes each attack vector, then ranks what survives by severity and confidence. The result is a short list, each entry carrying its evidence and, where source is available, a fix as specific lines of code. The analysis deeply understands each cloud’s identity model, networking, and data services well enough to resolve effective permissions and firewall rules and to ask the providers directly. The assessment phase is read-only throughout.
## Findings become pull requests
Most security tools stop at telling you something is wrong, which leaves the hardest part — remediation — as an exercise for the reader. Pulumi already declares and applies infrastructure change, so a proven finding becomes a proposed diff, a preview of what would change, and a pull request for a person to review. Remediation is the only part that writes anything, and only ever a proposed change in a repository, with deployment left to your existing reviewed workflow.
## What a report looks like
We have worked with several teams to run Neo Security against real production estates of different shapes and maturity, and it repeatedly found critical vulnerabilities the owners did not know existed. A single run reconciles thousands of managed resources against the account’s discovered inventory across every region in use.
Here are example findings, anonymized and generalized from real runs:
#
Finding
Severity
Confidence
1
Deployment federation role grants administrator access with no subject-claim condition
critical
high
2
Build role trusts source-control OIDC with a wildcard on the branch claim
high
confirmed
3
Build policy grants `iam:AttachRolePolicy` on every role in the account
high
confirmed
4
Test Kubernetes cluster API endpoint reachable from any address
high
confirmed
5
Security groups named for production allow all TCP and SSH from `0.0.0.0/0`
high
confirmed
6
Public compute instance with IMDSv1 and suspected secrets in user data
high
medium
7
Load balancer HTTP listener forwards API requests without enforcing TLS
medium
high
8
CDN connects to its origin over HTTP-only, exposing auth headers in transit
medium
high
9
Static access key for the mail-sending user, unrotated for over a year
medium
high
10
Mail-sending policy allows send-as on any verified identity
medium
high
11
Database snapshot shared with an account outside the organization
medium
confirmed
12
Analytics tool auto-provisions any account on the corporate domain
medium
medium
13
No management-plane audit trail defined in IaC
low
high
14
No WAF on the internet-facing load balancer or CDN
low
high
The implications of these example findings range from complete production account take-over, to poor encryption practices that put sensitive data at risk, to improperly authenticated email services that could be abused for phishing campaigns, to static unrotated keys that leave the account open to risks should it leak, and many other unfortunate outcomes. Each comes with a severity and risk so you can prioritize accordingly, and Neo works to exclude disproven findings and those without consequence.
## Getting a scan
We have been impressed what the combination of the latest frontier models, the unique context Pulumi has across several dimensions of your infrastructure, and giving the agent deep security domain expertise have been able to produce. We hope it helps the world of infrastructure get more secure.
Pulumi Neo Security is open now to a small group of invited customers, and the initial scan is free during the research preview. We’re looking for estates with real complexity and risk: multi-cloud and multi-account, a good mix of resource types, IaC and non-IaC resources, and those for which their infrastructure security is paramount.
Attackers are going to point agents at cloud infrastructure next. We would rather you find these problems first and we want to help. If you want to try a scan, [get in touch](https://www.pulumi.com/contact/).
## Pulumi Context API: One Graph for All Your Infrastructure

Every platform team fields the same questions: What is running? What breaks if we change this? What can we safely delete? The answers exist, but they’re scattered across state files, cloud consoles, and the memories of whoever set things up. Today we’re launching the Pulumi Context API, which connects what Pulumi knows about your infrastructure into a single graph you can query. It’s designed agent-first: [Pulumi Neo](https://www.pulumi.com/product/neo/), our infrastructure agent, uses it out of the box, and the API itself teaches any agent what it needs to know to get started. It’s available in preview for organizations on the Enterprise and Business Critical editions.
## Answers that span all your infrastructure
Pulumi already holds a detailed picture of your infrastructure. It knows the resources your programs manage, the dependencies between them, how stacks consume each other’s outputs, and which resources in your cloud accounts [Discovery](https://www.pulumi.com/docs/insights/discovery/) found outside IaC entirely. Each of those views is useful on its own. Now, the Context API lets you ask questions that cut across all of them:
- **Impact**: Which stacks are affected if we upgrade this provider? If this stack changes, what consumes its outputs?
- **Coverage**: How much of our infrastructure lives outside IaC, and in which accounts?
- **Cleanup**: Which stacks have no dependents and are candidates for retirement?
Each of these can be answered with a query against a graph that covers your resources (both Pulumi-managed and discovered), your stacks, and the relationships that connect them.
A query is a JSON document with a handful of clauses. `anchor` names the starting nodes, `traverse` walks relationships from there, and `return` picks what comes back. To run one, POST it to `https://api.pulumi.com/api/insights//graph/query`, or use the CLI: `pulumi api GraphQuery -F orgName= --input query.json`. Here’s a query that finds every resource that’s managed by an AWS provider older than version 7.0.0:
```json
{
"anchor": {
"nodeType": "resource",
"match": {
"type": "pulumi:providers:aws",
"fields": { "provider_version": { "op": "lt", "value": "7.0.0" } }
}
},
"traverse": [
{ "edgeTypes": ["provided_by"], "direction": "in", "depth": { "min": 1, "max": 1 }, "alias": "managed" }
],
"return": { "select": ["anchor", "managed"] }
}
```
And here’s the response, trimmed to a few nodes and fields:
```json
{
"nodes": [
{
"id": "urn:pulumi:prod::payments::aws:rds/instance:Instance::payments-db",
"nodeType": "resource",
"frontier": ["managed"],
"type": "aws:rds/instance:Instance",
"stack": "prod",
"project": "payments"
},
{
"id": "urn:pulumi:prod::payments::aws:ec2/vpc:Vpc::payments-vpc",
"nodeType": "resource",
"frontier": ["managed"],
"type": "aws:ec2/vpc:Vpc",
"stack": "prod",
"project": "payments"
},
{
"id": "urn:pulumi:prod::payments::pulumi:providers:aws::default_6_0_4",
"nodeType": "resource",
"frontier": ["anchor"],
"type": "pulumi:providers:aws",
"stack": "prod",
"project": "payments"
}
],
"edges": [
{
"from": "urn:pulumi:prod::payments::aws:rds/instance:Instance::payments-db",
"to": "urn:pulumi:prod::payments::pulumi:providers:aws::default_6_0_4",
"type": "provided_by"
}
],
"pageInfo": { "resultCount": 5 },
"meta": {
"resultMode": "exact",
"visibility": "complete",
"schemaVersion": "2026-08-25"
}
}
```
Each node shows the traversal step that reached it with the `frontier` field. In this example, the `anchor` is the outdated provider and the resources are `managed` by it. The `meta` fields tell you whether the answer is complete: `resultMode` flips to `truncated` if a size limit capped the results or the search backend answered partially, and `visibility` is `trimmed` if your RBAC permissions hid part of the graph. A continuation token appears in `pageInfo` if the answer was split into multiple pages.
## Ask Neo, or bring your own agent
We expect AI agents to be the primary users of the Context API. [Pulumi Neo](https://www.pulumi.com/product/neo/) uses it out of the box: ask Neo what breaks if a stack changes, and it queries the graph on your behalf, with the permissions of the user who invoked it.
Any other agent, whether that’s Claude Code, Cursor, Codex, or your own automation, can learn the API in one request. The schema endpoint returns a Markdown document (“primer”) covering the node and edge vocabulary, the full query grammar, and examples. Fetch it with the Pulumi CLI:
```bash
pulumi api GetGraphSchema -F orgName=my-org
```
or over plain HTTP:
```bash
curl -H "Accept: text/markdown" \
-H "Authorization: token $PULUMI_ACCESS_TOKEN" \
https://api.pulumi.com/api/insights/my-org/graph/schema
```
The primer is the complete reference for the query language. To onboard an agent, have it fetch the primer with `pulumi api GetGraphSchema -F orgName=`. Putting that command in your `AGENTS.md` or `CLAUDE.md` means the agent pulls a fresh copy whenever it needs one; the primer evolves with the API. From there, your agent composes queries from natural language questions and runs them with `pulumi api GraphQuery`. Most validation errors list the legal values inline, so an agent that re-reads the primer on rejection can correct its own queries.
## Available in preview
The Context API is available now for every organization on the Enterprise and Business Critical editions. The `pulumi api` commands shown here need [Pulumi CLI](https://www.pulumi.com/docs/install/) v3.243.0 or later. Access uses the same permission as [Resource Search](https://www.pulumi.com/docs/insights/discovery/search/), so if you can search resources in the console today, you can query the graph. Results are trimmed to the caller’s permissions. While the API is in preview the contract may change; any breaking changes will be announced in the [changelog](https://www.pulumi.com/releases/).
## The graph will grow
This launch is a first step. The graph vocabulary is designed to grow without breaking existing consumers, and we plan to bring in more of what Pulumi knows: [Pulumi ESC](https://www.pulumi.com/docs/esc/) environments, so you can trace which stacks a configuration or secret change reaches; teams and roles, so the graph knows who owns what; cloud accounts; and service catalog concepts from [Pulumi IDP](https://www.pulumi.com/docs/idp/), our internal developer platform.
## Get started
If your organization uses [Neo](https://www.pulumi.com/product/neo/), it already knows about the latest graph schema. For any other agent, tell it to fetch the primer with `pulumi api GetGraphSchema -F orgName=`. Then, start asking questions about your infrastructure graph using natural language.
Give it a try today, and share your feedback in the [Pulumi Community Slack](https://slack.pulumi.com/) or through your account team. If there’s a question you want answered that the graph doesn’t handle yet, tell us. That will shape what we build next.
## Best Kubernetes Infrastructure as Code Tools in 2026
There is no single best Kubernetes infrastructure as code tool, because “Kubernetes IaC” actually spans three different jobs. For provisioning the cluster and its cloud dependencies, Pulumi and Terraform (or OpenTofu) are the strongest general-purpose options. For templating and packaging workloads, Helm and Kustomize dominate. For continuous reconciliation once things are running, Argo CD and Flux lead the GitOps category. The right stack usually combines one tool from each layer, not a single tool that claims to do all three.
## What counts as infrastructure as code for Kubernetes?
Kubernetes infrastructure as code work splits into three layers that get conflated constantly, and the confusion is where most tool comparisons go wrong.
The **cluster and cloud layer** provisions the things Kubernetes itself sits on top of: the managed control plane (EKS, GKE, AKS), node pools, the VPC and subnets, IAM roles, load balancers, and cluster add-ons. Terraform, Pulumi, and cloud-native tools like CloudFormation operate here.
The **in-cluster workload layer** defines what runs on the cluster once it exists: Deployments, Services, ConfigMaps, CustomResourceDefinitions, and the Helm charts or Kustomize overlays that template them. This is where Helm, Kustomize, and Crossplane’s custom resources live.
The **delivery and reconciliation layer** keeps what’s declared in Git in sync with what’s actually running on the cluster, continuously, rather than as a one-shot apply. Argo CD and Flux own this layer, and they consume the output of the other two rather than replacing them.
Most real Kubernetes platforms use tools from at least two of these layers together. A team might provision EKS with Terraform, package its application with Helm, and let Argo CD reconcile it continuously. Knowing which layer a tool actually addresses, rather than treating “Kubernetes IaC” as one shopping list, is the first decision that matters.
## Pulumi provisions the cluster and the workloads on it in the same language
Pulumi is a general-purpose infrastructure as code platform that supports Python, TypeScript, Go, C#, Java, and YAML, backed by a [dedicated Kubernetes provider](https://www.pulumi.com/registry/packages/kubernetes/) that covers both the cluster layer and the workload layer in the same program. A single Pulumi stack can create an EKS cluster, its VPC and node groups, and the Deployments and Services that run inside it, with full dependency tracking between the two: Pulumi knows a Deployment depends on a cluster that does not exist yet, and sequences accordingly.
For workloads, Pulumi offers two distinct ways to work with Helm charts. [`kubernetes.helm.v4.Chart`](https://www.pulumi.com/registry/packages/kubernetes/how-to-guides/choosing-the-right-helm-resource-for-your-use-case/) renders a chart client-side via `helm template` into individual resources, giving full Pulumi state, diffing, and policy visibility into every object a chart creates, at the cost of not producing a real Helm release. `kubernetes.helm.sh/v3.Release` installs through the embedded Helm SDK instead, producing an actual release with hooks, and can even import releases installed by the Helm CLI. Teams pick based on whether they need release semantics or resource-level visibility; Pulumi’s documentation is upfront that these are genuinely different tradeoffs, not that one supersedes the other. Kustomize overlays are supported directly through [`kubernetes.kustomize.v2.Directory`](https://www.pulumi.com/registry/packages/kubernetes/api-docs/kustomize/v2/directory/).
As of the v4 provider, Server-Side Apply is the default for managing resources, which lets Pulumi share ownership of an object with other controllers safely instead of overwriting whatever they changed. Await and readiness logic (waiting for a Deployment’s rollout to finish before considering it “done”) is handled natively for common resource types, with `skipAwait` and `waitFor` escape hatches for anything unusual. As Pulumi engineer Bryce Lampe put it when the improved await logic shipped, “One of the advantages of using Pulumi to manage Kubernetes resources is that it natively and intuitively handles this problem of readiness and dependencies,” which matters more than it sounds: a naive apply-and-move-on model is a common source of flaky CI in Kubernetes pipelines.
Pulumi also plugs into an existing GitOps workflow rather than requiring you to replace it: the [Kubernetes provider’s `renderYamlToDirectory` option](https://www.pulumi.com/registry/packages/kubernetes/api-docs/provider/) renders manifests to disk instead of applying them directly, a pattern Pulumi’s own provider documentation calls out as an Argo CD Config Management Plugin use case. The provider currently labels this a developer-preview beta feature, disabled by default, so treat it as a bridge worth piloting rather than a settled default for a GitOps handoff. For CRDs, [`crd2pulumi`](https://www.pulumi.com/docs/integrations/clouds/kubernetes/crd2pulumi/) generates strongly typed SDKs from CRD definitions, so a custom resource gets the same autocomplete and type-checking as a built-in one. Teams running Pulumi as a standing service inside the cluster can use the [Pulumi Kubernetes Operator](https://www.pulumi.com/docs/integrations/clouds/kubernetes/pulumi-kubernetes-operator/) to drive stack updates from in-cluster custom resources.
The honest tradeoff: Pulumi is a commercial platform with an open-source core, and a team fully committed to a YAML-only, kubectl-native workflow will find a general-purpose language layer to be more machinery than it needs for a handful of static manifests. Materialize, which runs multi-region Amazon EKS clusters, [adopted Pulumi from day one to manage that complexity in Python](https://www.pulumi.com/case-studies/materialize/#executive-summary), after finding that tools like Terraform required developers to learn a proprietary configuration language and created unnecessary friction; new engineers reach their first meaningful contribution in a week rather than the month the team estimates it would otherwise take. A team with one cluster and no cross-region variation may not have that problem to solve.
## Terraform and OpenTofu remain the default for the cluster layer, with real friction at the workload layer
Terraform (and its community-governed fork, OpenTofu, since HashiCorp’s Business Source License change) is still the most widely deployed way to provision the cluster itself: the AWS, Google, and Azure providers are mature, and the Kubernetes and Helm providers (currently at 3.2.1 and 3.2.0 respectively) let the same HCL codebase reach into the cluster afterward. That reach is also where the friction shows up. Terraform plans at plan time, before it has ever talked to a live cluster, so it frequently cannot know what a CRD’s schema actually looks like until it’s already been applied; this is a well-documented source of “plan differs from apply” surprises when CRDs and their consumers live in the same configuration. The common workaround is a two-stage apply, provisioning the cluster in one Terraform run and the workloads that depend on its CRDs in a second, which works but adds operational ceremony that a single-language, single-run tool doesn’t need.
HCL itself is also a genuine limit at the workload layer: templating a Deployment’s environment variables across ten similar services means either heavy use of `for_each` and dynamic blocks, or accepting a lot of copy-pasted HCL, because HCL was designed as a configuration language rather than a general-purpose one with functions and reusable abstractions. None of this makes Terraform a poor choice for the cluster layer, where it remains a defensible default with a huge ecosystem of examples and modules. It’s a reason many Terraform shops hand workload templating off to Helm rather than fighting the Kubernetes provider for it.
## Helm is the default packaging format, and now defaults to safer applies
[Helm](https://helm.sh/) is the de facto package manager for Kubernetes: charts bundle a set of manifests with a templating layer and values files, and the public Artifact Hub ecosystem aggregates charts from vendors and the community, so most common software (databases, ingress controllers, observability stacks) has a chart available, official or otherwise. Helm 4 made Server-Side Apply the default instead of the old three-way merge against a stored last-applied-configuration annotation, which reduces a class of drift bugs that plagued Helm 3 installs sharing objects with other controllers. It also added WASM-based plugins and an experimental v3 chart format.
Helm’s real weakness is templating itself: charts are YAML run through Go’s text/template engine, which has no real type system, awkward conditionals, and error messages that point at rendered output rather than the source template. Values files also tend to sprawl as a chart tries to expose every possible customization, and a chart author’s defaults are a starting point you inherit rather than infrastructure you designed. Helm is excellent for consuming someone else’s well-maintained chart and mediocre as an authoring experience for your own complex, multi-service application, which is exactly why tools like Pulumi and Kustomize exist to sit on either side of it.
## Kustomize is the built-in choice for environment-specific overlays
[Kustomize](https://kubernetes.io/docs/tasks/manage-kubernetes-objects/kustomization/) ships inside `kubectl` and takes a patch-based approach instead of a templating one: you write a base set of plain YAML manifests, then layer environment-specific overlays (a different replica count for staging, a different image tag for production) that patch the base without touching it. That model avoids Helm’s templating-language problem entirely, at the cost of being far less expressive for anything beyond structural changes to existing YAML: generating a resource conditionally, or computing a value, is awkward or impossible.
The practical friction is version lag: the Kustomize binary bundled inside a given `kubectl` release trails the standalone Kustomize CLI’s releases, so a team relying on kubectl’s bundled version can be several minor versions behind what’s documented upstream. Teams that hit this usually install the standalone `kustomize` binary directly rather than depend on kubectl’s copy.
## Crossplane turns cloud resources into Kubernetes-native APIs
[Crossplane](https://www.crossplane.io/), which graduated to a CNCF top-level project on November 6, 2025, takes a fundamentally different approach: instead of a CLI that applies configuration, cloud resources become [managed resources](https://docs.crossplane.io/latest/managed-resources/managed-resources/), native Kubernetes custom resources that a control-plane cluster reconciles continuously, overriding drift back to the desired state, the same way Kubernetes reconciles a Deployment. This is a genuinely different mental model from Terraform, Pulumi, or Helm, and it’s the right one for platform teams building a self-service layer where application teams request infrastructure (an S3 bucket, a Postgres instance) through the same `kubectl apply` and RBAC model they already use for everything else.
Crossplane v2 removed native patch-and-transform composition and introduced namespaced Composite Resources (XRs) alongside an alpha “Operations” feature for one-off imperative tasks. Claims, the v1 abstraction that let application teams request infrastructure without touching the (cluster-scoped) XR directly, were already namespaced; what changes in v2 is that they [aren’t supported](https://docs.crossplane.io/v2.0/whats-new/) by the new namespaced or cluster-scoped XRs at all, and survive only when an XRD opts into the `LegacyCluster` scope for backward compatibility. Teams on Crossplane v1 migrating to v2 should plan to move application teams onto namespaced XRs directly rather than assume claims carry forward as-is. It also means Crossplane’s learning curve is steeper than a CLI-based tool: composing custom APIs out of managed resources requires understanding Crossplane’s own compositional model in addition to the cloud provider’s resource shapes. Teams that don’t need a self-service internal platform, and just want to provision infrastructure for their own team, usually find Terraform or Pulumi a faster path to the same cloud resources.
## Argo CD and Flux reconcile what’s running, and assume something else already authored it
[Argo CD](https://argo-cd.readthedocs.io/) (CNCF graduated December 2022, now at 3.5.1) and [Flux](https://fluxcd.io/) (CNCF graduated November 2022, now at 2.9.4) are the two dominant GitOps controllers: both watch a Git repository and continuously compare the cluster’s actual state against what’s declared there, surfacing drift as it appears and correcting it automatically when self-healing is enabled, rather than waiting for the next scheduled apply. This is the delivery layer from the three-layer breakdown above, and it’s genuinely complementary to, not competitive with, Terraform, Pulumi, Helm, and Kustomize: Argo CD and Flux consume rendered manifests or chart references, they don’t generate cloud infrastructure or author application configuration themselves.
The CNCF’s 2025 annual survey found that GitOps adoption tracks organizational maturity closely: 58% of self-identified “cloud native innovators” use GitOps extensively, compared to 23% of “adopters” earlier in their journey, which suggests GitOps is a practice teams grow into rather than a day-one requirement. Neither Argo CD nor Flux replaces the need for a provisioning tool at the cluster layer; a common and reasonable pattern is Terraform or Pulumi for the cluster and cloud dependencies, then Argo CD or Flux reconciling the workloads that run on it, with Pulumi’s `renderYamlToDirectory` option (currently a developer-preview beta feature) designed to feed that second stage.
## cdk8s and kro bring code and native APIs to workload definitions
[cdk8s](https://github.com/cdk8s-team/cdk8s) applies the AWS CDK model to Kubernetes manifests: you define Deployments, Services, and other objects in TypeScript, Python, Java, or Go, and cdk8s synthesizes plain YAML at build time, which plays nicely with existing GitOps pipelines since the output is still just manifests. It’s a narrower tool than Pulumi in scope, generating Kubernetes YAML only rather than also provisioning the cluster and cloud resources around it, and it has no equivalent to Pulumi’s state-tracked diffing or drift detection since it only emits manifests for something else to apply. The core `cdk8s` library is stable on the 2.x line; the higher-level `cdk8s+` construct libraries are versioned and released separately per supported Kubernetes version.
[kro](https://github.com/kubernetes-sigs/kro) takes Crossplane’s “infrastructure as a native API” idea and generalizes it: it [composes any native Kubernetes resource as well as any CRD installed in the cluster](https://docs.aws.amazon.com/eks/latest/userguide/kro.html), Crossplane’s managed resources included, into a new custom API that platform teams expose to their users. kro recently moved into the `kubernetes-sigs` organization as a SIG Cloud Provider subproject, which is a credibility signal, but it remains genuinely alpha (`v1alpha1` APIs, releases still in the 0.7 to 0.9.3 range) and is not yet a CNCF top-level project. It’s worth watching and piloting, not yet a safe default for anything you can’t easily rebuild.
A handful of other projects are worth knowing about without needing a full section: [Timoni](https://timoni.sh/) applies CUE’s type system to Kubernetes packaging as a Helm alternative; [KubeVela](https://kubevela.io/) builds an application-delivery abstraction on top of the Open Application Model; [Tanka](https://tanka.dev/) uses Jsonnet for templated manifests in the Grafana Labs ecosystem; and Ansible’s Kubernetes modules remain common in shops that already standardized on Ansible for configuration management generally.
## How the tools compare across cluster, workload, and delivery layers
Reconciliation model is the dimension most roundups leave out, and it matters as much as authoring language: a one-shot apply tool and a continuously reconciling controller solve different problems even when they touch the same YAML.
Tool
Authoring language
Provisions cloud + cluster?
Reconciliation model
Maturity / governance
Best fit
Pulumi
Python, TypeScript, Go, C#, Java, YAML
Yes
One-shot apply (`pulumi up`), continuous via Kubernetes Operator
Open-source core, commercial platform
Teams wanting one codebase for cluster + workloads
Terraform / OpenTofu
HCL
Yes
One-shot apply
Terraform: HashiCorp/IBM; OpenTofu: Linux Foundation
Cluster and cloud provisioning, HCL-standardized shops
Helm
YAML + Go templates
No (workload only)
One-shot install/upgrade
CNCF graduated
Packaging and consuming shared application charts
Kustomize
YAML (patch-based)
No (workload only)
One-shot apply
Built into `kubectl`, part of Kubernetes SIG-CLI
Environment overlays on plain manifests
Crossplane
Kubernetes YAML / CRDs
Yes (via managed resources)
Continuous reconciliation
CNCF graduated Nov 2025
Self-service internal platforms
Argo CD
Kubernetes YAML (consumed)
No (delivery only)
Continuous reconciliation
CNCF graduated
GitOps delivery, UI-driven ops
Flux
Kubernetes YAML (consumed)
No (delivery only)
Continuous reconciliation
CNCF graduated
GitOps delivery, GitOps Toolkit composability
cdk8s
TypeScript, Python, Java, Go
No (workload only)
One-shot synth to YAML
Stable 2.x core, CNCF Sandbox
Code-first manifest generation feeding existing GitOps
kro
Kubernetes YAML / CRDs
Yes (composes existing CRDs)
Continuous reconciliation
Alpha, `kubernetes-sigs` subproject
Composing custom platform APIs, early adopters
## The same task in Terraform and Pulumi
The clearest way to see the practical difference is the same job in both: create a managed EKS cluster and deploy a single workload onto it.
Terraform provisions the cluster with the AWS provider, then reaches into it with the Kubernetes provider in the same configuration:
```hcl
resource "aws_eks_cluster" "main" {
name = "app-cluster"
role_arn = aws_iam_role.eks.arn
vpc_config {
subnet_ids = aws_subnet.private[*].id
}
}
provider "kubernetes" {
host = aws_eks_cluster.main.endpoint
cluster_ca_certificate = base64decode(aws_eks_cluster.main.certificate_authority[0].data)
token = data.aws_eks_cluster_auth.main.token
}
resource "kubernetes_deployment" "app" {
metadata {
name = "app"
}
spec {
replicas = 3
selector {
match_labels = { app = "app" }
}
template {
metadata {
labels = { app = "app" }
}
spec {
container {
name = "app"
image = "myorg/app:1.4.0"
}
}
}
}
}
```
Pulumi, in TypeScript, does the same two-stage job with the dependency between them tracked automatically, rather than requiring a separate provider block wired up by hand:
```typescript
import * as aws from "@pulumi/aws";
import * as eks from "@pulumi/eks";
import * as k8s from "@pulumi/kubernetes";
const cluster = new eks.Cluster("app-cluster", {
instanceType: "t3.medium",
desiredCapacity: 3,
});
const provider = new k8s.Provider("k8s-provider", {
kubeconfig: cluster.kubeconfig,
});
const app = new k8s.apps.v1.Deployment("app", {
spec: {
replicas: 3,
selector: { matchLabels: { app: "app" } },
template: {
metadata: { labels: { app: "app" } },
spec: {
containers: [{ name: "app", image: "myorg/app:1.4.0" }],
},
},
},
}, { provider });
```
Both are legitimate. Terraform’s version separates concerns across a provider block and requires knowing the Kubernetes provider’s HCL shape for a Deployment resource; Pulumi’s version is fewer moving pieces because the cluster’s kubeconfig flows directly into the next resource as a normal object reference, and the whole thing can be unit tested with the same test framework used for the application code it deploys.
## How to choose a Kubernetes IaC tool
Most teams end up combining tools across the three layers rather than picking one. Working through these five steps in order avoids the most common mistake, which is picking a workload-layer tool (like Helm) and then trying to stretch it to also provision the cluster.
1. Decide who provisions the cluster and its cloud dependencies (VPC, node pools, IAM), and pick a cluster-layer tool for that job: Pulumi or Terraform/OpenTofu for most teams, or a cloud-native tool if you’re single-cloud and want the tightest console integration.
2. Decide how workloads get packaged. If you’re consuming other people’s software (databases, ingress controllers, observability agents), Helm’s chart ecosystem is hard to beat. If you’re authoring your own application manifests, Kustomize overlays or a code-first approach (Pulumi, cdk8s) usually scale better than hand-templated Helm charts.
3. Decide whether you need a self-service internal platform. If application teams should be able to request infrastructure through `kubectl apply` without touching Terraform or Pulumi directly, Crossplane or kro are worth the steeper learning curve. If your platform team is the only one touching infrastructure, you likely don’t need this layer yet.
4. Decide whether you need continuous reconciliation or a one-shot apply is enough. A small team deploying a few times a week can live with `terraform apply` or `pulumi up` in CI. A team running many clusters, or one where configuration drift is a recurring incident cause, benefits from Argo CD or Flux catching and correcting drift automatically.
5. Match the result to your team’s actual skills, not the tool with the most GitHub stars. A team of application engineers who already write Python or TypeScript daily will move faster in a tool that speaks their language than in a new DSL, and a platform team that already lives in YAML and kubectl will get more value from Kustomize and Argo CD than from introducing a new language to learn.
## Is Terraform or Pulumi better for Kubernetes?
Neither is universally better; the choice depends on what happens after the cluster exists. Terraform’s ecosystem of provider modules and examples is larger for pure cluster provisioning, and HCL is a smaller thing to learn than a full programming language. Pulumi’s advantage shows up once workloads enter the picture: because the cluster and its workloads live in the same general-purpose language, dependencies between them are tracked automatically, the same testing and CI tools used for application code apply to infrastructure code, and CRD-heavy workloads avoid the plan-time unknowns that come from HCL not having talked to a live cluster yet. Teams already standardized on HCL across their infrastructure will find less reason to switch; teams that want one codebase and one language for cluster and workloads together tend to prefer Pulumi.
## What are the alternatives to Helm?
Kustomize is the most common alternative for teams that find Helm’s templating language awkward, trading some expressiveness for patch-based simplicity on plain YAML. cdk8s replaces Helm’s templating with a real programming language that synthesizes YAML at build time. Pulumi can render Helm charts directly through kubernetes.helm.v4.Chart for full state visibility, or install them as genuine Helm releases through kubernetes.helm.sh/v3.Release, without requiring a separate templating tool at all. Timoni applies CUE’s type system as a more strictly typed alternative to Helm’s Go templates. None of these fully replace Helm’s chart ecosystem for consuming third-party software; they’re strongest for authoring your own application’s manifests.
## How do you manage a managed Kubernetes service like EKS, GKE, or AKS as code?
Managed Kubernetes services expose the control plane as a cloud resource like any other, so the tools that provision it are the same cluster-layer tools used for the rest of your cloud footprint: Terraform, OpenTofu, or Pulumi, using each cloud’s native provider (aws\_eks\_cluster, google\_container\_cluster, azurerm\_kubernetes\_cluster, or Pulumi’s equivalent resources and the higher-level @pulumi/eks package). The node pools, VPC, subnets, and IAM roles the control plane depends on get provisioned in the same run. What happens after the cluster exists, deploying and reconciling workloads, is a separate decision covered by the workload and delivery layers above, not something the cluster-provisioning tool needs to also own.
## Is GitOps a replacement for infrastructure as code?
No. GitOps tools like Argo CD and Flux reconcile what’s already declared in Git against what’s running on the cluster; they don’t generate that declaration or provision the cloud infrastructure underneath it. A GitOps workflow still needs something upstream producing the manifests it reconciles, whether that’s Helm charts, Kustomize overlays, cdk8s output, or Pulumi’s renderYamlToDirectory rendering a stack to disk. GitOps is a delivery and drift-correction practice layered on top of infrastructure as code, not a substitute for the provisioning step itself.
## Do you need Kubernetes-specific IaC tooling at all?
Not always. A team running a single small cluster with a handful of stable workloads can reasonably manage everything with plain kubectl apply against version-controlled YAML and skip templating tools entirely; the complexity Helm, Kustomize, and Crossplane solve only shows up once you have multiple environments, multiple similar services, or multiple teams needing self-service access. The honest signal that it’s time to adopt tooling is repetition: the same YAML copied and hand-edited across environments, or the same cluster-provisioning steps run manually more than once, is worth automating before it causes an incident.
## Which Kubernetes IaC tool should you choose?
There’s no single winner because “Kubernetes IaC” spans three different jobs. Most production setups combine a cluster-layer tool (Pulumi or Terraform), a workload-layer tool (Helm, Kustomize, or a code-first option), and often a delivery-layer tool (Argo CD or Flux) once the team is large enough to need continuous reconciliation. The five-step framework above is a better starting point than any single ranked list, because the right combination depends on your team’s language preferences, how many environments you run, and whether you need to expose infrastructure to other teams as a self-service API.
## Frequently asked questions
### Does Pulumi replace Helm and Kustomize?
Not entirely. Pulumi can render Helm charts and apply Kustomize overlays directly from its Kubernetes provider, so a team can consume the existing Helm and Kustomize ecosystems from inside a Pulumi program rather than needing a separate CLI step. For authoring new manifests from scratch, Pulumi’s general-purpose language is an alternative to writing Helm templates or Kustomize bases, but plenty of teams use Pulumi for the cluster layer while still authoring workload manifests as Helm charts.
### Can you use more than one of these tools together?
Yes, and most real deployments do. A common combination is a cluster-layer tool (Terraform or Pulumi) for the control plane and cloud dependencies, a workload-layer tool (Helm or Kustomize) for packaging what runs on it, and a delivery-layer tool (Argo CD or Flux) for continuous reconciliation. The three-layer breakdown at the top of this post exists precisely because these tools are usually complementary rather than competing for the same job.
### Is Crossplane a replacement for Terraform or Pulumi?
Not for most teams. Crossplane’s strength is exposing infrastructure as native Kubernetes APIs so application teams can self-serve through kubectl, which is a platform-engineering pattern, not a general substitute for a cluster-provisioning tool. A platform team still typically uses Terraform or Pulumi to provision the Crossplane control-plane cluster itself and configure Crossplane’s provider credentials.
### Why did the CNCF’s 2025 survey findings matter for this comparison?
The CNCF’s 2025 Annual Cloud Native Survey found 82% of container users now run Kubernetes in production, up from 66% in 2023, and 47% cited cultural change, more than training or security, as the top adoption challenge. Those numbers matter for tool choice because Kubernetes adoption has moved well past early adopters into mainstream production use, which means the tooling decision is increasingly about fitting an existing team’s skills and processes rather than picking a tool for a greenfield experiment.
## Where to go next
For the cluster-provisioning layer specifically, the [Pulumi Kubernetes getting-started guide](https://www.pulumi.com/docs/iac/get-started/kubernetes/) walks through creating a cluster and deploying a first workload. The [Pulumi vs. Helm comparison](https://www.pulumi.com/docs/iac/comparisons/helm/) and [Pulumi vs. Crossplane comparison](https://www.pulumi.com/docs/iac/comparisons/crossplane/) go deeper on the workload- and platform-layer tradeoffs summarized here, and the [Pulumi vs. Terraform comparison](https://www.pulumi.com/docs/iac/comparisons/terraform/) covers the cluster-layer decision in more depth than a roundup can. If your infrastructure spans more than Kubernetes, [our broader infrastructure as code tools roundup](https://www.pulumi.com/blog/infrastructure-as-code-tools/) compares the cloud-provisioning landscape beyond the cluster.
For running AI workloads specifically on Kubernetes, [our companion piece on provisioning and governing infrastructure for AI agents](https://www.pulumi.com/blog/ai-agents-on-kubernetes/) covers GPU-aware scheduling, credentials, and where policy as code and Pulumi’s Neo agent fit into that picture. And if a self-service platform for other teams is the eventual goal, [Pulumi’s IDP documentation](https://www.pulumi.com/docs/idp/) covers the components, templates, and policy guardrails that turn infrastructure code into something other teams can safely consume without needing to understand Pulumi themselves.
Whatever combination you land on, the layer breakdown here is the durable part: know whether you’re solving a cluster problem, a workload problem, or a reconciliation problem before you compare tools, because most of the disagreement in “best Kubernetes IaC tool” debates comes from comparing tools that were never solving the same problem in the first place.
## Compatibility Testing Pulumi HCL
[Pulumi HCL](https://www.pulumi.com/docs/iac/languages-sdks/hcl/) has at its core a simple promise:
> A program that works for `tofu apply` will also work for `pulumi up`.
This *must* be true to allow Terraform modules to be shared between `tofu` config and Pulumi programs. This property makes testing Pulumi HCL simple. Let me explain.
At the end of the day, Pulumi is a system to translate actual state & desired state into a series of imperative actions, so actual state can be reconciled to desired state. Terraform is a system to translate actual state & desired state into a series of imperative actions, so actual state can be reconciled to desired state. How desired state is expressed can be radically different, and the underlying reconciliation engine can be radically different, but at the end of the day, both tools do the same thing:
Executing a Terraform program looks like this:
```
flowchart LR
tf["*.tf files"]
current["current state"]
subgraph engine["reconciliation engine"]
direction LR
desired["desired state"] --> internal["provider steps"]
end
output["provider steps"]
tf --> desired
current --> engine
engine --> output
```
Executing a Pulumi program is more dynamic, because the reconciliation engine is in more active dialog with the user’s program. That said, the diagram is the same shape. To [match semantics](https://www.pulumi.com/blog/terraforms-data-model-on-pulumis-engine/#providers), Pulumi HCL dynamically bridges [any Terraform provider in the registry](https://www.pulumi.com/registry/packages/terraform-provider/). This means that, for the subset of Pulumi programs that are valid OpenTofu programs, both programs take the same input (`*.tf` files) and produce the same step output (Terraform provider steps). Providers are the part of our model that generates user-observable behavior, which means if we match what providers see, we match what users see. This gives us a really nice definition of correctness for Pulumi HCL1:
> Pulumi HCL correctly interprets an HCL program when it generates the same set of provider steps as `tofu` does.
If you are familiar with property-based testing, you might be thinking this looks like a testable property. You’re right.
## How we compatibility test Pulumi HCL
We have created a framework to assert on the property above for Pulumi HCL: [`tfcompat`](https://github.com/pulumi/pulumi-hcl/tree/master/tests/tfcompat). Each `tfcompat` test has 2 components:
- The files of the HCL program
- The providers the program uses
I’ll walk you through an example test case, then explain how the framework works.
### An example `tfcompat` test
This Go test is the full code of [`TestL2SimpleResource`](https://github.com/pulumi/pulumi-hcl/blob/b966ee6fd0a6d08389856b3d98cb28e58072927d/tests/tfcompat/l2_simple_resource_test.go#L24-L31):
```go
// tests/tfcompat/l2_simple_resource_test.go
func TestL2SimpleResource(t *testing.T) {
t.Parallel()
tfcompat.RunCase(t, "l2_simple_resource", tfcompat.Case{
Providers: []tfcompat.Provider{
{Name: "simple", Factory: providers.SimpleProvider},
},
})
}
```
`Factory` is a function that produces a new in-memory Terraform provider called `"simple"`. The `"l2_simple_resource"` in the test is the folder that contains the actual HCL program under test:
```tf
# tests/tfcompat/testdata/cases/l2_simple_resource/main.tf
resource "simple_resource" "a_resource" {
input_one = "hello"
input_two = true
}
output "some_output" {
value = simple_resource.a_resource.result
}
```
This test asserts that Pulumi HCL & OpenTofu both:
- [ConfigureProvider](https://developer.hashicorp.com/terraform/plugin/framework/internals/rpcs#configureprovider-rpc) the simple provider the same way.
- Call the same [plan](https://developer.hashicorp.com/terraform/plugin/framework/internals/rpcs#planresourcechange-rpc) RPC during `pulumi preview` & `tofu plan`.
- Call the same [ApplyResourceChange](https://developer.hashicorp.com/terraform/plugin/framework/internals/rpcs#applyresourcechange-rpc) to create the resource.
- Pulumi HCL or OpenTofu didn’t call any other provider RPCs.
One really important takeaway is that nowhere in this test case do we write down what Pulumi HCL should do. `tfcompat.RunCase` takes a scenario, but it doesn’t take accepted behavior. This will be important later. Before we get there, let me explain how `tfcompat.RunCase` works.
### The anatomy of `tfcompat.RunCase`
Every [`tfcompat.RunCase`](https://github.com/pulumi/pulumi-hcl/blob/b966ee6fd0a6d08389856b3d98cb28e58072927d/tests/testutil/tfcompat/harness.go#L191) runs 2 parallel processes, then compares the results:
- **The Terraform Side:** `tfcompat.RunCase` runs each Terraform provider in-memory, then copies the files in its test directory to a temp dir and runs `tofu plan`, then `tofu apply` against the temp dir. We use [`TF_REATTACH_PROVIDERS`](https://developer.hashicorp.com/terraform/plugin/debugging#running-terraform-with-a-provider-in-debug-mode) to have `tofu` attach to our in-memory Terraform providers.
- **The Pulumi Side:** `tfcompat.RunCase` runs each Terraform provider in-memory & copies the test files in its test directory to a separate test dir, and runs `pulumi preview`, then `pulumi up` against the temp dir. We use [`PULUMI_BRIDGE_REATTACH_PROVIDERS`](https://github.com/pulumi/pulumi-terraform-bridge/pull/3559) to instruct [our dynamic bridge](https://www.pulumi.com/registry/packages/terraform-provider/) to attach to our in-memory provider.
**For both** Pulumi & Terraform, the test harness [records each provider’s gRPC calls](https://github.com/pulumi/pulumi-hcl/blob/b966ee6fd0a6d08389856b3d98cb28e58072927d/tests/testutil/tfexec/recorder.go#L50) for all providers and it records the stack outputs for both invocations.
After both runs have completed, the test asserts that the outputs of the Pulumi program & the Terraform program match, and that the providers saw the same operations. A test case passes if and only if the providers for OpenTofu & Pulumi saw the same operations, and stack outputs were equal.
## Writing tests with LLMs
Because tfcompat tests assert that Pulumi HCL matches OpenTofu, and not the test author’s idea of correctness, we can use LLMs to effectively hunt for bugs. Without additional constraints, telling Claude or Codex to find a bug will produce mostly false positives. Because our tests need only a scenario to test, it is very hard2 for LLMs to produce false positives. This allows useful bug finding runs with as simple a prompt as:
> I’d like you to do a pass trying to find bugs. You will prove each bug with a genuine failing tfcompat test. Start with 10 sub-agents. Bugs should not be duplicates and bugs should not reflect existing issues. Each failure should be stood up as a draft PR with just the failing test added. These PRs will fail CI. That is intentional. Don’t try to fix the bugs you solved. Keep the sub-agents running until you have found 10 failures. You are responsible for validating that the bugs are real and ensuring that the sub-agents do not create duplicate bugs, so you should create the PRs directly.
This is supported by [a](https://github.com/pulumi/pulumi-hcl/blob/571fedb720fe7cd7d8f37ce01990c7c2df384658/.claude/skills/find-tfcompat-bug/SKILL.md) [couple](https://github.com/pulumi/pulumi-hcl/blob/571fedb720fe7cd7d8f37ce01990c7c2df384658/.claude/skills/swarm-tfcompat-bugs/SKILL.md) [of](https://github.com/pulumi/pulumi-hcl/blob/2709fcb5d5825f69d1213c9d176f40d6bc52c98e/.claude/skills/farm-tfcompat-bugs/SKILL.md) [skills](https://github.com/pulumi/pulumi-hcl/blob/571fedb720fe7cd7d8f37ce01990c7c2df384658/.claude/skills/fix-tfcompat-bug/SKILL.md), but this strategy does [genuinely](https://github.com/pulumi/pulumi-hcl/pull/447) [find](https://github.com/pulumi/pulumi-hcl/pull/397) [high-quality](https://github.com/pulumi/pulumi-hcl/pull/411) [bugs](https://github.com/pulumi/pulumi-hcl/pull/422).
Because of how easy it is to send LLMs to hunt bugs, I think of this almost as a property-based test with LLMs as both the case generator and the reducer.
## Conclusion
Having a strong and testable definition for Pulumi HCL makes it easy & fast to write integration tests, ensuring that our implementation is correct. LLMs are excellent at finding bugs when given the ability to write tests that fail if and only if they show a real divergence between our HCL implementation & OpenTofu, letting us hunt for bugs at LLM scale. All this testing has made us pretty confident that [what we’ve shipped](https://www.pulumi.com/releases/terraform-state-backend-modules-hcl/) is pretty close to full parity with OpenTofu, and we’d love it if you [gave it a try](https://www.pulumi.com/docs/iac/languages-sdks/hcl/).
---
1. Pulumi HCL accepts a superset of what OpenTofu accepts. This method only applies to the subset of programs that OpenTofu accepts. ↩︎
2. Typically, false positives come from an LLM finding a scenario where `tofu apply` errors, but `pulumi up` behaves correctly. ↩︎
## Never Miss What Your Infrastructure Is Telling You

Plenty happens in a Pulumi organization while you’re looking somewhere else. Neo finishes a task you kicked off just before taking lunch. A teammate submits an ESC change request that needs your approval before it can land. Until now, catching any of that meant either keeping the right tab open or hoping the right email reached you.
Today we’re introducing the Notification Center: a single inbox in the Pulumi Cloud console for the things that actually need you. It lives behind the bell in the sidebar, with a dot when something’s waiting. Notifications arrive in real time — no refresh — and each one carries exactly one action: Review request, View task, Update billing. Click it and you land on the page where you can do the thing, not on a dashboard where you have to go find it.
## What you’ll hear about
We’ve started with the moments where being a few minutes late actually costs you something: a Neo task that’s paused waiting on your approval, a Neo task that’s finished, an ESC change request waiting on your sign-off, and billing conditions like a locked organization or a trial that’s about to end. Relevant people in your organization will be notified when there’s a pending approval, or billing alert. Nobody gets paged for someone else’s work.
## Where you’ll hear about it
Every notification type can be delivered two ways — in the console and over email — and you choose per type, per channel. Organization admins set a sensible baseline for everyone; each person can override it for themselves on their account settings page.
## What’s next
The Notification Center is available today. We’re starting with this set of notifications and expanding from there. If there’s an event you’d rather hear about from the bell than from a colleague on Slack, we’d like to know which one.
Join our [Community Slack](https://slack.pulumi.com/) to connect with the Pulumi team and other users, or open an issue on our [GitHub repository](https://github.com/pulumi/pulumi).
## Automatic Logging for Faster, Secure Debugging
Pulumi v3.254.0 introduces automatic logging: every operation is logged in an encrypted log file that can optionally be shared with the Pulumi team for inspection. No more re-running commands just to get logs to the Pulumi team for debugging; instead you can share existing logs securely.
You might have been in a situation where pulumi hit an error for an unexpected reason, or did something that was not quite right. Currently the process for trying to resolve that is to try and reproduce the error, ideally now with logging enabled. Sometimes the error doesn’t reproduce, or the state pulumi was in at the time of the error doesn’t exist anymore. And even if the issue reproduces it’s a bit of a hassle to do all this again, just to get logs to Pulumi employees who can do something with them. There’s also no great mechanism to send the potentially sensitive log file.
## How it works
From pulumi v3.254.0 onward, we automatically produce log files for every operation and store them in `$PULUMI_HOME/logs`. These log files are encrypted on disk, using the relevant stack’s secret manager, whenever it is available, as they still contain secrets at this point. The final file consists of gzip’d chunks that are encrypted using AES256-GCM. Log files are gzip’d when no secrets manager is available, as no secrets from property values can be in the log at that point.
Note that the logs are rotated out after 7 days, or after the log directory has reached 500 MB, removing the oldest logs first. This way logs will never fill up your disk, but will still be available after running pulumi commands. These defaults can be overridden with the `PULUMI_LOG_ROTATION_MAX_AGE_DAYS` and `PULUMI_LOG_ROTATION_MAX_TOTAL_MB` environment variables.
Locally these logs can be decrypted using [`pulumi logs decrypt`](https://www.pulumi.com/docs/iac/cli/commands/pulumi_logs_decrypt/). For this to work the same stack’s secret manager as was used for the command needs to be available.
## Sharing logs
Previously there was no good way to securely share the logs with us. Users were always forced to find a way to send the logs to us on their own. With the latest pulumi version, we introduce the [`pulumi logs share`](https://www.pulumi.com/docs/iac/cli/commands/pulumi_logs_share/) command. This will automatically create a key, safely stored on the server side, and re-encrypt the log with that key, redacting all the secrets by default.
This key can then be accessed by Pulumi employees and Pulumi employees only via an internal tool to decrypt the log. Again we encrypt the log using AES256-GCM. Given this encryption the log can be shared over unsafe channels, and still be secure, even if it’s posted on a GitHub issue.
And while we strive to keep the Pulumi experience as issue free as possible, this should drastically simplify the debugging experience when it is still necessary.
## Terraform and Kubernetes: A Practical Guide for 2026

Yes, Terraform can manage Kubernetes: the official `hashicorp/kubernetes` provider lets you declare Deployments, Services, and other objects as HCL resources, and community providers like `kubectl` fill in the gaps. It works well for many teams. The friction shows up around two well-documented limits — provider ordering and plan-time API access — and around testing, where a general-purpose language changes what’s possible.
That friction matters more in 2026 than it did a few years ago. Kubernetes infrastructure now sits next to AI-driven engineering workflows: agents that propose changes, run previews, and open pull requests need infrastructure code they can read, test, and reason about with the same tools they use for application code. A cluster definition written in HCL and a workload definition written in YAML are both harder for an agent — and a person — to unit test, refactor, or type-check than the equivalent in TypeScript, Python, or Go.
This guide is about the *operating model* for Kubernetes infrastructure: how the cluster, the platform layer, and the workloads on top of it get provisioned, tested, and shipped. It’s a different question from “should I write my Kubernetes manifests in YAML, HCL, or a real language,” which we cover in detail in [YAML, Terraform, or Pulumi: what’s the smart choice for deployment automation with Kubernetes?](https://www.pulumi.com/blog/yaml-terraform-pulumi-whats-the-smart-choice-for-deployment-automation-with-kubernetes/) Read that post first if you’re deciding how to author manifests; read this one for the wider workflow — provisioning, testing, policy, and where AI agents fit.
## How does Terraform manage Kubernetes today?
The `hashicorp/kubernetes` provider (current release v3.2.1, requiring Terraform 1.0.0 or later) is the primary path, and teams typically combine it with one or two others depending on what they’re deploying:
Approach
What it’s for
Notes
Typed resources (`kubernetes_deployment_v1`, `kubernetes_service_v1`, etc.)
Core, well-known object types
Full HCL validation and typed attributes for the objects the provider models explicitly
`kubernetes_manifest`
Custom resources or object types the provider doesn’t model yet
Requires live API access during `terraform plan`, which shapes how it can be sequenced (details)
`hashicorp/helm` provider
Installing Helm charts
Wraps the Helm SDK; chart internals aren’t individually visible to Terraform’s plan/diff
Community `kubectl` provider (`alekc/kubectl`, a maintained fork of `gavinbunney/kubectl`)
Applying free-form YAML manifests
Common workaround for `kubernetes_manifest`’s plan-time requirement; newer versions support Terraform 1.10+ ephemeral resources so secrets don’t have to land in state
## What are the hard parts of managing Kubernetes with Terraform?
Two limitations show up often enough in practice that HashiCorp documents them directly, and they’re worth quoting rather than paraphrasing:
- **Plan-time API access.** From the `kubernetes_manifest` resource docs: “This resource requires API access during planning time. This means the cluster has to be accessible at plan time and thus cannot be created in the same apply operation. We recommend only using this resource for custom resources or resources not yet fully supported by the provider.” In practice this means you can’t create a cluster and populate it with `kubernetes_manifest` resources in a single `terraform apply` — the cluster has to exist and be reachable before Terraform can even plan the manifest resources.
- **Provider-credential ordering.** From the provider’s own index documentation: “When using interpolation to pass credentials to the Kubernetes provider from other resources, these resources SHOULD NOT be created in the same Terraform module where Kubernetes provider resources are also used. This will lead to intermittent and unpredictable errors which are hard to debug and diagnose. The root issue lies with the order in which Terraform itself evaluates the provider blocks vs. actual resources.” HashiCorp’s prescribed fix, also verbatim: “The most reliable way to configure the Kubernetes provider is to ensure that the cluster itself and the Kubernetes provider resources can be managed with separate `apply` operations. Data-sources can be used to convey values between the two stages as needed.”
Both are solvable — split cluster provisioning and workload deployment into separate applies (or separate Terraform workspaces/modules), and pass values between them with data sources or remote state. It’s a real pattern, and plenty of teams run it in production. It does mean two-stage pipelines and extra state plumbing wherever a cluster and its workloads are managed together.
## What changes when Kubernetes infrastructure is written in a general-purpose language?
Pulumi’s Kubernetes provider is generated directly from the Kubernetes OpenAPI specifications (current version v4.33.0), so it stays current with the Kubernetes API surface automatically, and it runs inside a single Pulumi program in TypeScript, Python, Go, C#, Java, or YAML. Because the cluster resource and the workloads that depend on it are ordinary values in that program, sequencing them doesn’t require splitting into separate applies — Pulumi’s dependency graph resolves the ordering, and Server-Side Apply (the provider’s default since v4.0) handles upserts consistently across resource types.
The provider also has built-in await logic for common object types — it knows a Deployment isn’t “done” until its replicas are available, a Service isn’t ready until it has endpoints or a load balancer ingress, and a Pod isn’t ready until its readiness probe passes. That behavior is tunable with annotations: `pulumi.com/skipAwait`, `pulumi.com/timeoutSeconds`, the experimental `pulumi.com/waitFor` (supports a JSONPath value check, a JSONPath existence check, `condition=Synced`, or a JSON array of conditions), and `pulumi.com/deletionPropagationPolicy`.
For Helm, there are three options with different tradeoffs:
Resource
How it works
Best for
`helm.sh/v4.Chart`
Renders the chart client-side and manages each object as a distinct Pulumi resource; implemented as a component, so it works the same way across every Pulumi language, including Java and YAML; supports OCI registries
Teams that want every rendered object visible in the resource graph, diffable, and enforceable by policy
`helm.sh/v3.Chart`
Same client-side rendering approach, the previous major version
Existing usage; Pulumi has said it expects to deprecate this in a future release in favor of `v4.Chart`
`helm.sh/v3.Release`
Embeds the real Helm SDK and creates an actual Helm release, including hooks; can import chart releases installed via the Helm CLI
Charts that rely on Helm hooks, or environments already managed with the Helm CLI
The practical distinction: `Chart` resources give you a resource graph you can diff and enforce policy against, one object at a time, but no Helm hooks and no CLI interop. `Release` gives you full Helm behavior, but policy enforcement can’t reach into the resources a Helm release creates.
For CRDs, `crd2pulumi` reads a CustomResourceDefinition’s OpenAPI schema and generates strongly typed classes in your language, so custom resources get IDE autocompletion and compile-time checking instead of the untyped `apiextensions.CustomResource` path. For plain manifests and Kustomize output, current guidance favors the versioned APIs — `yaml/v2.ConfigFile`, `yaml/v2.ConfigGroup`, and `kustomize/v2.Directory` — over their unversioned predecessors.
## How do you manage Kubernetes infrastructure with Pulumi?
A typical workflow for standing up an application on Kubernetes with Pulumi looks like this:
1. Install the Pulumi CLI and create a new project with `pulumi new kubernetes-typescript` (or the `-python`, `-go`, `-csharp`, or `-java` variant for your language).
2. Configure the target cluster context — either point Pulumi at an existing `kubeconfig`, or provision the cluster itself in the same program using your cloud provider’s Pulumi provider (EKS, AKS, GKE, and so on).
3. Import the Kubernetes provider package for your language and instantiate a `Provider` resource if you need a non-default context or credentials.
4. Define your workloads as typed resources — a `Deployment`, a `Service`, a `ConfigMap` — using the same objects, loops, and functions you’d use in any other program in that language.
5. For existing Helm charts, use `helm.sh/v4.Chart` to render and manage the chart’s resources individually, or `helm.sh/v3.Release` if you need full Helm hook support.
6. For CustomResourceDefinitions, run `crd2pulumi` against the CRD’s schema to generate typed classes, then instantiate custom resources the same way as built-in types.
7. Run `pulumi preview` to see a diff of what will change, and `pulumi up` to apply it — Server-Side Apply and the provider’s await logic handle upsert and readiness semantics automatically.
8. Wire the stack into CI by running `pulumi preview` on pull requests and `pulumi up` on merge, using the same pipeline and secrets store your application code already uses.
Here’s step 4 in TypeScript, deploying a Deployment and a Service together in one program:
```typescript
import * as k8s from "@pulumi/kubernetes";
const appLabels = { app: "my-service" };
const deployment = new k8s.apps.v1.Deployment("my-service", {
spec: {
selector: { matchLabels: appLabels },
replicas: 3,
template: {
metadata: { labels: appLabels },
spec: {
containers: [{
name: "my-service",
image: "my-registry/my-service:1.4.0",
ports: [{ containerPort: 8080 }],
}],
},
},
},
});
const service = new k8s.core.v1.Service("my-service", {
spec: {
selector: appLabels,
ports: [{ port: 80, targetPort: 8080 }],
type: "LoadBalancer",
},
});
export const serviceIp = service.status.loadBalancer.ingress[0].ip;
```
And the same shape in Python:
```python
import pulumi
import pulumi_kubernetes as k8s
app_labels = {"app": "my-service"}
deployment = k8s.apps.v1.Deployment(
"my-service",
spec=k8s.apps.v1.DeploymentSpecArgs(
selector=k8s.meta.v1.LabelSelectorArgs(match_labels=app_labels),
replicas=3,
template=k8s.core.v1.PodTemplateSpecArgs(
metadata=k8s.meta.v1.ObjectMetaArgs(labels=app_labels),
spec=k8s.core.v1.PodSpecArgs(containers=[
k8s.core.v1.ContainerArgs(
name="my-service",
image="my-registry/my-service:1.4.0",
ports=[k8s.core.v1.ContainerPortArgs(container_port=8080)],
),
]),
),
),
)
service = k8s.core.v1.Service(
"my-service",
spec=k8s.core.v1.ServiceSpecArgs(
selector=app_labels,
ports=[k8s.core.v1.ServicePortArgs(port=80, target_port=8080)],
type="LoadBalancer",
),
)
pulumi.export("service_ip", service.status.load_balancer.ingress[0].ip)
```
Because `deployment` and `service` are ordinary values in the program, Pulumi resolves their dependency order automatically — there’s no separate apply stage to sequence by hand, even if the cluster itself were provisioned earlier in the same program.
## How do you test Kubernetes infrastructure code before it ships?
Testing is one of the sharpest differences between the two approaches, and it’s worth being precise about what each side actually offers:
Capability
Terraform
Pulumi
Unit tests (no cloud calls)
`.tftest.hcl` files with `command = plan`, plus `mock_provider` (GA since v1.7.0) for provider-free assertions
`pulumi.runtime.setMocks` (TypeScript), `pulumi.runtime.set_mocks` (Python), or `pulumi.WithMocks` (Go), run inside the same test framework as application code
Integration tests (real infra)
`.tftest.hcl` files with `command = apply` against a real or ephemeral environment
Automation API drives real preview/up/destroy cycles against ephemeral stacks, orchestrated from your own code
Test language
A second, declarative, test-specific language (`.tftest.hcl`)
The same language and test runner already used for application code — Jest, pytest, `go test`, xUnit
Policy enforcement
Sentinel or OPA/Rego, evaluated against the plan
Pulumi Policies (policy packs in TypeScript/JavaScript or Python) or OPA/Rego via `pulumi-policy-opa`, evaluated against the resource graph of a stack written in any Pulumi language
`terraform test` with `mock_provider` is a legitimate, GA capability, and teams that have standardized on HCL testing patterns can write real infrastructure-free unit tests with it. The practical difference isn’t “Terraform can’t test” — it’s that Terraform tests live in a separate language and toolchain from the application code they support, while Pulumi’s tests run in the same Jest, pytest, or `go test` suite a team already runs on every commit. Because Kubernetes objects created through `Chart`, `ConfigGroup`, or `CustomResource` resources appear individually in Pulumi’s resource graph, Pulumi Policies apply to them the same way they’d apply to a cloud resource — there’s no separately named “Kubernetes policy” product, only the same policy-as-code engine applied to whatever’s in the graph.
## Where do AI agents fit into Kubernetes infrastructure management?
An AI agent operating on infrastructure needs to read the current state, propose a change, preview its effect, and — ideally — get that change reviewed like any other pull request. That loop is much easier for an agent to execute reliably against a TypeScript or Python program than against HCL or raw YAML, because the agent can use the same static analysis, type checking, and test suite a developer would use, rather than reasoning about a domain-specific configuration language from scratch.
Pulumi Neo is built for exactly this loop: an infrastructure agent with organizational context, policy guardrails, and human-in-the-loop approvals, working inside the same preview/policy/apply cycle described above. We cover the fuller picture of provisioning and governing agent workloads on Kubernetes — GPU-aware scheduling, session state, and the security boundary around what an agent is allowed to touch — in [How to Run AI Agents on Kubernetes with Pulumi](https://www.pulumi.com/blog/ai-agents-on-kubernetes/).
## When is Terraform still the right choice for Kubernetes?
Fair comparisons cut both ways, and there are good reasons a team keeps using Terraform for Kubernetes:
- **Provider and module catalog breadth.** Terraform’s registry has the largest catalog of providers and community modules of any IaC tool, and that matters for teams integrating many third-party systems alongside Kubernetes.
- **A single tool across the whole estate.** Teams that have already standardized on Terraform for networking, IAM, and managed services often prefer one state model and one pipeline rather than introducing a second tool solely for Kubernetes.
- **HCL’s simplicity for static configuration.** For infrastructure that’s genuinely declarative and doesn’t need loops, abstraction, or conditional logic, HCL reads and reviews cleanly.
- **Existing governance investment.** Teams with mature Sentinel or OPA policy libraries and deep in-house HCL expertise have real switching costs, and those costs are legitimate inputs to the decision.
- **The plan-time limitation is manageable in practice.** Once cluster provisioning and workload deployment are split into separate applies — HashiCorp’s own documented pattern — the `kubernetes_manifest` plan-time requirement stops being a daily obstacle.
None of that is a reason to avoid Terraform outright; it’s a reason to be clear-eyed about which parts of your Kubernetes workflow benefit most from a general-purpose language and which don’t.
## How do you move Kubernetes infrastructure from Terraform to Pulumi?
Teams don’t have to choose all-or-nothing. Pulumi’s `pulumi convert` command translates existing Terraform HCL into a Pulumi program in your target language as a starting point for further editing, and Pulumi’s guide to [migrating Kubernetes YAML and Helm charts](https://www.pulumi.com/docs/iac/guides/migration/migrating-to-pulumi/from-kubernetes/) and its [Terraform migration guide](https://www.pulumi.com/docs/iac/guides/migration/migrating-to-pulumi/from-terraform/) both cover the mechanics in more depth.
Pulumi also now meets Terraform-standardized teams partway: Pulumi IaC supports native HCL as a language option, Pulumi Cloud can serve as a state backend for existing Terraform configurations, and Pulumi supports consuming Terraform modules directly. That coexistence story — not a forced rewrite — is often the more realistic starting point for a team with a large existing Terraform estate, including Kubernetes-adjacent infrastructure. Wiz, for example, uses Pulumi’s Automation API to manage more than 1 million cloud resources, including tens of thousands of Kubernetes clusters across hundreds of data centers, with more than 100,000 daily infrastructure updates.
## Frequently asked questions
Common questions that come up when teams evaluate Terraform and Pulumi for Kubernetes specifically.
### Can Terraform manage a Kubernetes cluster and its workloads in one apply?
Not reliably, per HashiCorp’s own documentation. The `kubernetes_manifest` resource needs live API access at plan time, so the cluster must already exist and be reachable before Terraform can plan workload resources against it. The documented pattern is to split cluster provisioning and workload deployment into separate `apply` operations and pass values between them with data sources or remote state.
### Does Pulumi replace kubectl and Helm?
No. Pulumi’s Kubernetes provider applies the Kubernetes API the same way `kubectl` and Helm do — it doesn’t replace the cluster API or the Helm packaging format. What it replaces is the imperative or templated workflow around applying manifests: instead of running `kubectl apply` or `helm install` by hand or from a shell script, you declare the desired state in a Pulumi program and let `pulumi up` reconcile it, with the same preview, diff, and rollback behavior Pulumi provides for any other cloud resource.
### Is Terraform’s Kubernetes provider actively maintained?
Yes. The `hashicorp/kubernetes` provider is on major version 3 (v3.2.1 as of this writing, with v3.0.0 shipping in December 2025) and requires Terraform 1.0.0 or later. It’s a first-party HashiCorp provider with regular releases.
### What’s the difference between kubernetes\_manifest and the community kubectl provider?
`kubernetes_manifest`, from HashiCorp’s own provider, needs the cluster’s API reachable at plan time and is recommended mainly for custom resources not yet modeled as typed resources. The community `alekc/kubectl` provider (a maintained fork of `gavinbunney/kubectl`) applies free-form YAML through its `kubectl_manifest` resource and is a common workaround for the plan-time requirement; recent versions also support Terraform’s ephemeral resources so sensitive values don’t have to be written to state.
### Can Pulumi and Terraform manage the same Kubernetes cluster at once?
Yes, in the sense that both talk to the same Kubernetes API and don’t inherently conflict — the risk is the same one you’d have with any two tools managing overlapping objects: whichever tool last wrote a resource’s desired state “owns” it until the other reconciles again. Most teams that run a mixed estate assign ownership by namespace, resource type, or workload boundary rather than letting both tools manage the same objects.
## Where to go next
Related reading on Pulumi and Kubernetes:
- [YAML, Terraform, or Pulumi: what’s the smart choice for deployment automation with Kubernetes?](https://www.pulumi.com/blog/yaml-terraform-pulumi-whats-the-smart-choice-for-deployment-automation-with-kubernetes/) — the manifest-authoring comparison this guide deliberately doesn’t repeat
- [How to Run AI Agents on Kubernetes with Pulumi](https://www.pulumi.com/blog/ai-agents-on-kubernetes/) — provisioning and governing infrastructure for agent workloads specifically
- [Kubernetes infrastructure as code: tools and best practices](https://www.pulumi.com/what-is/infrastructure-as-code-for-kubernetes/) — a broader look at the IaC options for Kubernetes
- [Unit testing Pulumi programs](https://www.pulumi.com/docs/iac/guides/testing/unit/) — the full mock API reference across languages
- [crd2pulumi](https://www.pulumi.com/docs/integrations/clouds/kubernetes/crd2pulumi/) — generating typed SDKs from CustomResourceDefinitions
- [Migrating to Pulumi from Terraform](https://www.pulumi.com/docs/iac/guides/migration/migrating-to-pulumi/from-terraform/) and [from Kubernetes YAML and Helm](https://www.pulumi.com/docs/iac/guides/migration/migrating-to-pulumi/from-kubernetes/)
- [Pulumi’s Kubernetes provider in the registry](https://www.pulumi.com/registry/packages/kubernetes/)
## A guided tour of Terraform state, hosted modules, and HCL in Pulumi
[Today’s big release](https://www.pulumi.com/releases/terraform-state-backend-modules-hcl/) contains a whole new set of features designed for seamless interoperability with the Terraform and OpenTofu ecosystems, and there’s a lot there — so much that it can be tough to get your head around all of it. But it generally falls into three major categories:
- **Support for Pulumi Cloud as a Terraform state backend**, including remote execution with human approvals
- **A Terraform module registry** in Pulumi Cloud that lets you publish, document, and share your modules even across language boundaries
- **First-class support for HCL** as an authoring language in the Pulumi engine
To make this release a little easier to appreciate holistically, I’ve put together a quick end-to-end walkthrough that doesn’t quite cover *everything*, but does cover the big stuff, and should give you a sense of how it all comes together. We’ll start with a simple Terraform project that you’ll deploy to AWS, and then one step at a time, bring it into Pulumi Cloud and kick the tires on each of these new features as we go. It’ll take a bit, but all you’ll need are a free Pulumi account and the ability to deploy an S3 bucket to AWS.
We’ve got a bunch to cover, so let’s jump right in.
## Start with a Terraform project
Our tour begins with a tiny Terraform project that provisions a single Amazon S3 bucket using a locally defined module that we’ll publish later. The project is [available on GitHub](https://github.com/cnunciato/simple-tf-template) as a template, and the easiest way to use it is with the GitHub CLI:
```bash
$ gh repo create my-tf-project \
--template cnunciato/simple-tf-template \
--public \
--clone && cd my-tf-project
```
We’ll use the local Terraform backend to start. Set your AWS credentials (preferably with [environment variables](https://docs.aws.amazon.com/cli/latest/userguide/cli-configure-envvars.html)), then deploy the project with Terraform or OpenTofu. (This walkthrough uses the `terraform` CLI, but you can swap in `tofu` if that’s your preference.)
```bash
$ terraform init && terraform apply
...
Apply complete! Resources: 2 added, 0 changed, 0 destroyed.
Outputs:
bucket_arn = "arn:aws:s3:::my-tf-project-bucket-14d19ece"
bucket_name = "my-tf-project-bucket-14d19ece"
```
Now let’s see how to move this project into Pulumi Cloud.
## Migrate the state to Pulumi Cloud
First, [create a Pulumi Cloud account](https://app.pulumi.com/signup) if you don’t already have one (it’s free for individuals) and sign in to the Pulumi console. Then, add a `backend` block to `main.tf`, swapping `` for your own Pulumi Cloud account or organization name:
```hcl
terraform {
# ...
backend "remote" {
hostname = "tf.pulumi.com"
organization = ""
workspaces {
name = "my-tf-project_dev"
}
}
}
```
The workspace `name` is an underscore-delimited string that expresses the name of the [project](https://www.pulumi.com/docs/iac/concepts/projects/) you’d like to use (here, `my-tf-project`) and the [stack](https://www.pulumi.com/docs/iac/concepts/stacks/) (`dev`). A single Pulumi project can have as many stacks as you like.
Next, sign in to Pulumi Cloud with the Terraform CLI:
```bash
$ terraform login tf.pulumi.com
```
Choose `yes` when prompted, and you’ll be taken to Pulumi Cloud to create a [personal access token](https://www.pulumi.com/docs/administration/access-identity/access-tokens/#personal-access-tokens), which you can paste into the prompt to authenticate:

```
Success! Logged in to Terraform Enterprise (tf.pulumi.com)
```
With the `backend` block in place and your `terraform` CLI signed in to Pulumi Cloud, you’re ready to complete the migration:
```bash
$ terraform init -migrate-state
```
Terraform should detect the `backend` change and offer to copy your existing state:
```
Do you want to copy existing state to the new backend?
Pre-existing state was found while migrating the previous "local" backend
to the newly configured "remote" backend. [...] Enter "yes" to copy and
"no" to start with an empty state.
Enter a value: yes
```
Choose `yes`, and you’re done:
```
Successfully configured the backend "remote"! Terraform will automatically
use this backend unless the backend configuration changes.
```
Note that nothing about your deployed infrastructure has changed here; all we did was migrate your local state to Pulumi Cloud, and the process is identical whether you’re moving from S3, Azure, Google Cloud, or HCP Terraform or Terraform Enterprise. See [Store Terraform state in Pulumi Cloud](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-state-backend/) for details.
Now hop over to the Pulumi Cloud console, choose **Stacks**, and you’ll see your new stack in the list, along with its first update:

### Runs happen remotely by default
Another thing to note is that Terraform stacks backed by Pulumi Cloud run *remotely* by default, just as they do in HCP Terraform and Terraform Enterprise. Plans and applies are executed on a Pulumi Cloud-hosted runner, and output is streamed simultaneously to your terminal and to the browser. Try making a small change to `main.tf` — adding a tag, say — and run `terraform apply`:
```diff
tags = {
Environment = "dev"
+ Owner = "me"
}
```
```bash
$ terraform apply
...
Running apply in the remote backend. Output will stream here.
To view this run in a browser, visit:
https://tf.pulumi.com/app/cnunciato/my-tf-project_dev/runs/run-8a635542-334f-4367-b188-8b4b442b2550
...
```
Confirm with another `yes`, and you’ll notice the `apply` *fails* — which makes sense, considering the runner doesn’t have your AWS credentials yet. That’s where [Pulumi ESC](https://www.pulumi.com/docs/esc/) comes in.
### Configure cloud credentials with ESC
When you create a new Terraform stack, Pulumi Cloud automatically creates a linked [ESC environment](https://www.pulumi.com/docs/esc/concepts/environments/) for you with the same name. You can use this environment to configure settings of all kinds, including cloud credentials and other encrypted secrets, and make those settings available to the stack at runtime.
In the stack’s **Overview** tab, click the linked `my-tf-project/dev` environment to open the environment editor, where you can either set your AWS credentials directly or wire up a new [connection](https://www.pulumi.com/docs/esc/guides/configuring-oidc/) by choosing **Add new** → **Login provider/configuration** and following the steps for AWS.
Since I’ve already configured an environment for sharing my AWS credentials across all of my stacks (which I’ve named `default/personal`), I can just [import that environment](https://www.pulumi.com/docs/esc/concepts/imports/) into this one to use it:
```yaml
imports:
- default/personal
```
Try this yourself, then run the `apply` again, and see that it succeeds:
```bash
$ terraform apply -auto-approve
...
OpenTofu will perform the following actions:
# module.s3-bucket.aws_s3_bucket.this will be updated in-place
~ resource "aws_s3_bucket" "this" {
id = "my-tf-project-bucket-b64b8e37"
~ tags = {
"Environment" = "dev"
+ "Owner" = "me"
}
~ tags_all = {
+ "Owner" = "me"
}
}
Plan: 0 to add, 1 to change, 0 to destroy.
...
Apply complete! Resources: 0 added, 1 changed, 0 destroyed.
Outputs:
bucket_arn = "arn:aws:s3:::my-tf-project-bucket-b64b8e37"
bucket_name = "my-tf-project-bucket-b64b8e37"
```
Remote execution is powered by [Pulumi Deployments](https://www.pulumi.com/docs/deployments/), which means your Terraform stacks can also be triggered by VCS events — pull requests and pushes to GitHub, GitLab, and others — as well as manual human approvals. Wiring that up is pretty simple as well:
1. Under **Management → Version Control** in the Pulumi console, configure your VCS provider and add the `my-tf-project` repository.
2. In your stack’s **Settings** tab, choose **Deploy**, configure the repository and the base branch to build from (e.g., `main`), and save.
3. Push a commit to that branch.
When you do that, you’ll see a new plan in the **Deployments** tab, and once that finishes, you’ll be prompted to approve or decline the run:

Click **Confirm**, and you’re off and running.
And that’s it! Your Terraform stacks are now first-class citizens in Pulumi Cloud, with [access control](https://www.pulumi.com/docs/administration/access-identity/rbac/), [Neo code reviews](https://www.pulumi.com/docs/ai/neo/code-reviews/), and [Pulumi Policies](https://www.pulumi.com/docs/insights/policy/) all available to them. [Audit policies](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-state-backend/#audit-policies) are runnable on any Terraform stack, and preventative policies can be used to block non-compliant changes before they happen.
Next up: modules.
## Publish a Terraform module
If your team’s been using Terraform for a while, chances are you’ve also written some Terraform modules, so you’ll need somewhere to keep them as you move to Pulumi Cloud. In addition to its role as a Terraform state backend, Pulumi Cloud now includes a [private registry](https://www.pulumi.com/docs/idp/concepts/terraform-modules/) that can host your Terraform modules and make them available across your organization.
Module publishing requires an [Enterprise or Business Critical](https://www.pulumi.com/pricing/) plan, so you’ll need an organization with one of those for this part — but you can easily [create one](https://app.pulumi.com) with a free trial if you don’t have one already. In the Pulumi console, open the organization menu, choose **Create organization**, give it a name, and you’re good to go.
Pulumi Cloud’s Terraform registry API is wire-compatible with HCP Terraform’s, which means the tools you already use for publishing — e.g., the [`go-tfe`](https://github.com/hashicorp/go-tfe) library or the [`hashicorp/tfe`](https://registry.terraform.io/providers/hashicorp/tfe/latest/docs) Terraform provider — need only be pointed at `tf.pulumi.com`. To make this easy, our project includes a small Go program that uses `go-tfe` to do just that. Set a Pulumi access token in your terminal (you may need to [obtain a new one](https://app.pulumi.com/user/settings/tokens)), then run it from the project root, passing your organization name:
```bash
$ export PULUMI_ACCESS_TOKEN=
# Install Go at https://go.dev/doc/install if you don't have it already.
$ go -C upload-module run . \
-org \
-provider aws \
-version 0.1.0 \
-path ./modules/s3-bucket
```
You should see a confirmation:
```
creating module veridian/s3-bucket/aws
uploaded veridian/s3-bucket/aws@0.1.0
```
Then, in the Pulumi console, navigate to **Platform → Private components**, and you should see your newly uploaded module in the list. Click into it to see its details, available versions, usage instructions, and API docs:

With the module now hosted in Pulumi Cloud, you can update your project to use the hosted version instead. Delete the local `./modules` folder entirely, and then in `main.tf`, update the `source` and add a `version`, replacing `` with your chosen org name:
```hcl
module "s3-bucket" {
source = "tf.pulumi.com//s3-bucket/aws"
version = "0.1.0"
# ...
}
```
Now run `terraform plan` and see that the module is downloaded and the plan, as expected, produces no changes:
```bash
$ terraform plan
...
Initializing modules...
Downloading tf.pulumi.com/veridian/s3-bucket/aws 0.1.0 for s3-bucket...
...
No changes. Your infrastructure matches the configuration.
```
Now let’s have a look at how you can use this module in other ways.
## Consume the module from a Pulumi program
The whole point of a shared module registry is to help you get more mileage out of the work you put into your Terraform modules. When you use Pulumi Cloud for that registry, you can consume those modules not just from a Terraform program, but from any Pulumi program as well — and in any supported language.
Let’s see how this looks with a TypeScript project. If you haven’t already, [install Pulumi](https://www.pulumi.com/docs/install/), then run:
```bash
$ mkdir ../my-typescript-project && cd $_
$ pulumi new typescript
```
Follow the prompts, accepting the defaults. Then, add the Terraform module to your TypeScript project with `pulumi package add`:
```bash
$ pulumi package add s3-bucket-aws
```
This fairly magical command generates a local TypeScript SDK at `./sdks` that wraps the module as a [Pulumi component](https://www.pulumi.com/docs/iac/concepts/components/). To use it, open up `index.ts` and replace its contents with the following:
```typescript
import * as bucket from "./sdks/s3-bucket";
const myModule = new bucket.Module("my-module", {
bucketPrefix: "my-new-bucket",
tags: {},
});
export const { bucketName, bucketArn } = myModule;
```
Configure your AWS credentials locally as before — or alternatively, [use the ESC environment you created earlier](https://www.pulumi.com/docs/esc/concepts/environments/#using-environments-with-pulumi-iac) if you set one up — then run `pulumi up` to deploy in the usual way:
```bash
$ pulumi up
Updating (dev)
Type Name Status
+ pulumi:pulumi:Stack my-typescript-project-dev created (8s)
+ └─ s3-bucket:index:Module my-module created (5s)
+ ├─ random:index:Id my-module-suffix created (0.21s)
+ └─ aws:index:S3Bucket my-module-this created (2s)
Outputs:
bucketArn : "arn:aws:s3:::my-new-bucket-bbfa52db"
bucketName: "my-new-bucket-bbfa52db"
Resources:
+ 4 created
```
Having a language-specific, locally managed SDK at hand comes with many benefits, including IDE support, typed inputs and outputs, and more — but there may be times when you’ll prefer a simpler or more dynamic option. In these situations, you can instead choose to load the module at runtime.
In TypeScript, you’d do that with the `@pulumi/hcl` module. Try that now by installing it in your project:
```bash
$ npm install @pulumi/hcl
```
… and using it in your program:
```typescript
import * as hcl from "@pulumi/hcl";
const myModule = new hcl.Module("my-module", {
source: "tf.pulumi.com//s3-bucket/aws",
version: "0.1.0",
inputs: {
bucket_prefix: "my-new-bucket",
tags: {},
},
});
export const { bucket_name, bucket_arn } = myModule.outputs;
```
Because this approach uses untyped references, you’ll trade a little type safety for flexibility — but either way, you’re able to keep using the modules you’ve already built, while migrating to *new* infrastructure in general-purpose languages on whatever schedule works best for your team.
## Write and run HCL, natively
For as much flexibility as general-purpose languages offer, some teams simply prefer to use HCL. So as of today, HCL is now a first-class language in the Pulumi engine, right alongside TypeScript, Python, Go, C#, Java, and YAML.
The easiest way to get a feel for it is to create a new project from a template:
```bash
$ mkdir ../my-hcl-project && cd $_
$ pulumi new aws-hcl
```
As before, step through the prompts, then open the generated Pulumi project’s `main.tf`:
```hcl
terraform {
required_providers {
aws = {
source = "pulumi/aws"
}
}
}
# Create an AWS resource (S3 Bucket)
resource "aws_s3_bucket" "my-bucket" {}
# Export the name of the bucket
output "bucket_name" {
value = aws_s3_bucket.my-bucket.id
}
```
You can deploy this out of the box (after setting your AWS credentials again, of course) to see the magic happen:
```bash
$ pulumi up
Updating (dev)
Type Name Status
+ pulumi:pulumi:Stack my-hcl-project-dev created (6s)
+ └─ aws:s3:Bucket my-bucket created (3s)
Outputs:
bucket_name: "my-bucket-7282e67"
Resources:
+ 2 created
Duration: 7s
```
This template happens to use the `pulumi/aws` provider, but you’re free to pull in any others as well: [native Pulumi providers](https://www.pulumi.com/docs/iac/concepts/providers/), official `hashicorp/*` providers, community-supported providers, and more. In fact, you can try that now by replacing the code in `main.tf` with the same code you used in the Terraform program you left off with earlier — only without the explicit `terraform > backend` block, as it’s no longer needed:
```hcl
module "s3-bucket" {
source = "tf.pulumi.com//s3-bucket/aws"
version = "0.1.0"
bucket_prefix = "my-tf-project-bucket"
tags = {}
}
output "bucket_name" {
value = module.s3-bucket.bucket_name
}
output "bucket_arn" {
value = module.s3-bucket.bucket_arn
}
```
Run `pulumi up` again, and you’ll see the module get picked up and used, just as before:
```bash
$ pulumi up
Updating (dev)
Type Name Status
+ pulumi:pulumi:Stack my-hcl-project-dev created (10s)
+ └─ components:index:C619d883588c0366 s3-bucket created (8s)
+ ├─ random:index:Id s3-bucket.suffix created (0.22s)
+ └─ aws:index:S3Bucket s3-bucket.this created (3s)
Outputs:
bucket_arn : "arn:aws:s3:::my-tf-project-bucket-f61cea35"
bucket_name: "my-tf-project-bucket-f61cea35"
Resources:
+ 4 created
Duration: 12s
```
And with that, our tour is complete. Be sure to clean up both projects with a `terraform destroy` and `pulumi destroy` when you’re done.
## Where to go next
Now you’ve seen it all come together: You can back your Terraform state with Pulumi Cloud, publish and share your modules, consume those modules from any Pulumi language, and write HCL that runs natively — all without having to rewrite what you’ve already built.
A few next steps to keep the learning going:
- Explore our [architecture templates](https://www.pulumi.com/templates/) to bootstrap new HCL projects easily
- Read up on [Terraform state](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-state-backend/), [remote execution](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-remote-execution/), and [Terraform modules](https://www.pulumi.com/docs/idp/concepts/terraform-modules/) in Pulumi Cloud
- Dive into [Pulumi and HCL](https://www.pulumi.com/docs/iac/languages-sdks/hcl/)
- Check out the [full set of features](https://www.pulumi.com/releases/terraform-state-backend-modules-hcl/) in this release
We’d love for you to kick the tires on all of this and let us know what you think. If something seems missing or doesn’t behave as you’d expect, [open an issue](https://github.com/pulumi/pulumi/issues), let us know in the [Pulumi Community Slack](https://slack.pulumi.com/), or [reach out](https://www.pulumi.com/contact/?form=sales) if you’d like to learn more.
Happy building!
## Bring Your Terraform Estate Into the Agentic Era
At Pulumi, we are building the platform for agentic infrastructure. Pulumi Cloud provides the guardrails and enterprise readiness needed to safely move fast in this new era. While we are seeing extraordinary adoption — over 40% of our users now manage infrastructure using AI agents — we know many organizations are at different phases in their AI journey and have to balance building for the future with maintaining their existing infrastructure as code (IaC) solutions like Terraform. Today, we are launching three ways that Pulumi lets you avoid trading off building for the future against building for today. You don’t have to rip out Terraform to enter the agentic era. Pulumi Cloud brings agentic infrastructure to the IaC estate you already have.
## What we’re shipping today
Last December, our CEO [Joe Duffy laid out his vision](https://www.pulumi.com/blog/all-iac-including-terraform-and-hcl/) to make Pulumi the platform for all of your infrastructure as code. The capabilities we are launching today make that promise a reality. Pulumi is now fully interoperable with Terraform and OpenTofu and enables organizations to build upon their existing IaC estate rather than starting from scratch as they work toward the agentic infrastructure future.
### Pulumi Cloud as a Terraform backend
We are excited to announce the general availability of [Pulumi Cloud as the backend to your Terraform state](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-state-backend/), enabling organizations to seamlessly lift and shift their existing Terraform estates.
We recognize there is lots of infrastructure that works as is, and switching over to a new management paradigm may not always be possible. Pulumi Cloud support for the Terraform state backend lets organizations maintain their existing Terraform deployment patterns while also unlocking the power of Pulumi Cloud. The following common patterns for running Terraform are now supported:
- **Plans and applies run remotely by default** for new Terraform stacks, following the behavior of HCP Terraform and Terraform Enterprise. When you run a Terraform operation, it executes on a Pulumi-hosted runner rather than your local machine. You get full visibility into these operations both on your local CLI and in the Pulumi Cloud console.
- **Production deployments may be gated with manual approvals** before applying a Terraform plan.
With this release, stacks with Terraform state are first-class entities in Pulumi Cloud. They get access to all of the capabilities that organizations need to scale in this new AI-first era.
- **[Manage access to your Terraform stacks at scale](https://www.pulumi.com/docs/administration/access-identity/rbac/)** using tag-based access control, team role assignments, and user role assignments.
- [**Take advantage of Neo code reviews**](https://www.pulumi.com/docs/ai/neo/code-reviews/). On every pull request, leverage what Pulumi Cloud knows about your running infrastructure and get clear feedback on whether it’s safe to merge changes to your Terraform and OpenTofu projects.
- [**Run preventive policies**](https://www.pulumi.com/docs/insights/policy/) after a Terraform plan to block non-compliant resources before deployment.
- **[Configure your Terraform deployments with Pulumi ESC](https://www.pulumi.com/docs/esc/)**, which is natively available to Pulumi Cloud-backed Terraform projects, to securely inject OIDC credentials at apply time and expose outputs to downstream stacks and services.
Learn more in [Using Pulumi Cloud as a Terraform state backend](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-state-backend/).
### Reuse your Terraform modules
Pulumi programs, regardless of language, now support [importing Terraform modules](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-modules/) natively. Organizations can leverage their existing reusable artifacts as is, without having to make a single change. This enables organizations to focus on new infrastructure projects and lets them build those projects in the language of their choice, regardless of what their existing IaC estate is.
In addition, Pulumi Cloud’s private registry can now host Terraform modules alongside Pulumi packages. This enables you to consolidate all of your IaC building blocks in a single source of truth rather than managing disparate solutions and making sure your teams know where to look. Terraform modules hosted in Pulumi Cloud provide maximum interoperability and can be used in both Pulumi and Terraform programs.
Learn more in [Using Terraform modules in Pulumi](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-modules/).
### Build in HCL natively
[HashiCorp Configuration Language (HCL)](https://www.pulumi.com/docs/iac/languages-sdks/hcl/) is now generally available as a first-class language in Pulumi IaC. Like any other Pulumi language, it has full access to the entirety of the Pulumi ecosystem, including thousands of providers. Thanks to our Terraform bridge, if there’s a Terraform provider out there, it just works. Best of all, HCL in Pulumi is 100% [OpenTofu](https://github.com/opentofu/opentofu) compatible with no syntactical differences.
We recognize there are many teams out there that prefer to work in HCL over general-purpose languages but want to leverage the modern Pulumi IaC engine, or want to be able to use the reusable components their partner teams rely on — regardless of whether those teams work in Terraform or Pulumi.
Learn more in the [HCL language reference](https://www.pulumi.com/docs/iac/languages-sdks/hcl/).
## You are still covered until your HashiCorp renewal
We stand by the promise we made last December, and the last thing we want is for you to pay for two IaC solutions. To set your team up for long-term success and ensure your transition to Pulumi is as smooth as possible, we are continuing to offer three things:
- **An escape hatch for your current contract.** We know paying for two IaC solutions at once is a non-starter, so we’re letting you apply credits purchased from HashiCorp toward your Pulumi usage until your next renewal, avoiding double pay.
- **A free IaC modernization workshop.** Our professional services cloud architects host a free IaC modernization workshop to review where you’re at with your IaC already and share best practices for adopting the Pulumi platform at scale, learned from working with world-class organizations like BMW and Supabase. You will leave this session trained up and equipped to succeed with the next phase of your IaC journey.
- **A return on investment (ROI) calculation.** We will show you how the move to Pulumi will not only be spend-neutral thanks to the escape hatch, but how much value and savings you should expect to see, given our experience helping innovators like Snowflake accelerate their time to market — going from code to cloud in weeks to hours.
These ensure there’s no financial penalty for switching, a clear ROI, and no learning curve. We have always been proud to work with customers of all sizes in all industries, so these offers are available to you whether you’re a Global 2000, a startup, or somewhere in between.
## Get started today
The agentic infrastructure era is already here, and we want you to bring your IaC to it. [Get started with Pulumi free](https://app.pulumi.com/signup) and provision your first stack in minutes.
If you’d like to get started with the new Terraform/OpenTofu and HCL capabilities, or take advantage of the financial flexibility options, please [get in touch](https://www.pulumi.com/contact/?form=sales).
## Emulating Terraform on Pulumi's Engine
The core promise of Pulumi’s HCL support is that you can bring your existing Terraform configuration and modules, and `pulumi` will run them. If it works in OpenTofu and doesn’t work in Pulumi, we would like to fix that. Given that goal, our HCL interpreter needs to take HCL as input and emit instructions to the Pulumi engine that semantically match how `tofu` would interpret the same input. This is made harder by the fact that Pulumi and OpenTofu have fundamentally different engine semantics and provider ecosystems. This blog post will explore how we have implemented that mapping well enough to get 96%1 of our top Terraform modules working on Pulumi. We’ll briefly walk through how Pulumi’s HCL interpreter handles Terraform’s resource semantics, providers, and modules. It will also call out where Pulumi’s HCL support lets you do things that Terraform and OpenTofu will not allow.
## Providers
Both Pulumi and Terraform have providers, but they don’t have the same providers. While there are providers that Terraform [does](https://www.pulumi.com/registry/packages/pulumiservice/) [not](https://www.pulumi.com/registry/packages/azure-native/) [have](https://www.pulumi.com/registry/packages/kubernetes/), Pulumi can always resolve a Terraform provider using Pulumi’s confusingly named [`terraform-provider`](https://www.pulumi.com/registry/packages/terraform-provider/) provider.2 This is the same provider that lets you consume *Any Terraform Provider* in another Pulumi program with `pulumi package add terraform-provider ...`. The `terraform-provider` provider acts as a relay: it speaks Pulumi’s protocol to the Pulumi engine, and speaks Terraform’s provider protocol to the Terraform provider it stands up. Because Pulumi HCL needs to work with all Pulumi providers and because `terraform-provider` lets Pulumi HCL speak to Terraform providers via the Pulumi protocol, Pulumi HCL actually only speaks Pulumi protocols directly:
```
flowchart LR
subgraph n2Entry[" "]
n2["terraform-provider"]
end
subgraph providerBox["Pulumi Provider"]
direction TD
n2Entry
n3["Terraform Provider"]
end
n0["Pulumi HCL"] <--> n1["Pulumi Engine"]
n1 <--> n2Entry
n2 <--> n3
n2@{ shape: rect}
n3@{ shape: rect}
n0@{ shape: rect}
n1@{ shape: rect}
style n2Entry fill:transparent,stroke:transparent
```
All internals of [github.com/pulumi/pulumi-hcl](https://github.com/pulumi/pulumi-hcl) are implemented in Pulumi’s language protocol.
Because the `terraform-provider` natively understands Terraform version ranges and defaults to the OpenTofu registry, we can directly translate normal provider requests to the `terraform-provider`. It takes its arguments as an untyped list of strings, since the interface was originally intended for the command line. Let’s walk through some simple examples:
```hcl
resource "aws_s3_bucket" "example" {
bucket = "my-bucket-123"
}
```
Pulumi’s HCL interpreter sees that there is no `terraform.required_providers` block, so it cuts the resource token at the first `_` and uses the default registry and namespace. This is what the request that goes to the Pulumi engine looks like:
```go
pulumirpc.PackageSpec{
Source: "terraform-provider",
Parameters: []string{"registry.opentofu.org/hashicorp/aws"},
}
```
Because no version was specified, we leave it to `terraform-provider` to determine the version. It will [use the latest version](https://github.com/pulumi/pulumi-terraform-bridge/blob/v3.135.0/dynamic/internal/shim/run/loader.go#L240-L252).
Just like Terraform, you can override this with a `required_providers` block:
```hcl
terraform {
required_providers {
example = {
source = "my.custom.registry/me/example"
version = "~> 5.0"
}
}
}
resource "example_resource" "another_example" {
}
```
We perform the same mechanical translation. The source is fully specified, and there is a version, so we [pass it along to the Pulumi engine](https://github.com/pulumi/pulumi-hcl/blob/3e810b1c378abc0e0134810f897a85903f4c0abf/pkg/server/server.go#L232-L239), which passes it along to `terraform-provider`:
```go
pulumirpc.PackageSpec{
Source: "terraform-provider",
Parameters: []string{"my.custom.registry/me/example", "~> 5.0"},
}
```
Pulumi HCL will automatically translate almost all provider calls through the `terraform-provider` translator. Providers with the source `pulumi/*` will instead be routed directly. This is how you can use a native Pulumi provider in Pulumi HCL:
```hcl
terraform {
required_providers {
kubernetes = {
source = "pulumi/kubernetes"
version = "4.33.0"
}
}
}
resource "kubernetes_yaml_config_file" "app" {
file = "app.yaml"
}
```
Our HCL interpreter routes this directly to the Pulumi Kubernetes package:
```go
pulumirpc.PackageSpec{
Source: "kubernetes",
Version: "4.33.0",
}
```
Observe that the version moved from `Parameters` to the `Version` field. That’s because providers written with `source = "pulumi/*"` are talking about the plugin directly.
## Resources
Both Pulumi programs and Terraform config exist to express a resource graph. It is their primary purpose. I don’t have the time or the pixels to explain everything, so I’ll restrict myself to three sub-topics here:
- Property name translation
- Provisioners and conditions
- Resource options
### Property name translation
If you’ve ever looked at the schema behind any of our providers, you will observe that names are camelCase.
```json
"aws:s3/bucket:Bucket": {
"properties": {
"accelerationStatus": { "type": "string", "description": "...", "deprecationMessage": "..." },
"bucketDomainName": { "type": "string", "description": "..." },
"bucketNamespace": { "type": "string", "description": "..." },
...
```
Our codegen actually relies on this fact, which means that even the schemas produced by `terraform-provider` use camelCase property names. The clever among you will see the problem: Terraform uses snake\_case by convention. When Pulumi HCL sends a resource request with property values, it needs to translate from the snake\_case text to camelCase for the engine, and then back again on values returned by the engine.
```
sequenceDiagram
participant Program as HCL program
(snake_case)
participant Interp as HCL interpreter
participant Engine as Pulumi engine
(camelCase)
Interp->>Engine: GetSchema("example_resource")
Engine-->>Interp: schema (property names + types)
Program->>Interp: some_value = "true"
Interp->>Engine: RegisterResource { someValue: true }
Engine-->>Interp: outputs { someValue: true, computedValue: "..." }
Interp-->>Program: example_resource.example.computed_value
```
Doing this correctly actually requires you to be aware of the resource’s schema; the raw value is not enough. Let’s work through an example to understand why:
```hcl
resource "example_resource" "example" {
some_value = "true"
block {
inner_value = false
}
another_attribute = {
"trap_one" = 1
"trap_two" = 2
}
}
```
Here are two different value blobs (represented as JSON) that correspond to the inputs for `"example"` above. Both are valid, depending on the type of `"example_resource"`:
```json
{
"someValue": "true",
"block": {
"innerValue": false
},
"anotherAttribute": {
"trap_one": 1,
"trap_two": 2
}
}
```
```json
{
"someValue": true,
"block": [{
"innerValue": "false"
}],
"anotherAttribute": {
"trapOne": "1",
"trapTwo": 2
}
}
```
Let’s break down the difference between the two potential value blobs:
- HCL converts scalar values to the type the provider expects, so if `someValue` is typed as a string, we keep the `"true"`. If it’s typed as a boolean, we convert and pass the provider the converted value: `true`.
- If `block` is typed as an object, the Pulumi provider expects to see an object back on the wire. If `block` is typed as a list of objects, then the Pulumi provider needs to see a list of objects back, even if it’s a list of one.
- `innerValue` can have the same type conversion as `someValue`. Type conversion doesn’t stop at the top level.
- If `anotherAttribute` is a map type, then its keys are user-provided values and need to be kept as they are. If it’s an object type, then its keys need to be shifted back to camelCase.
Pulumi’s HCL interpreter is thus type aware. It queries the engine for the schema of each provider it translates for and does the correct conversion, tracking the target type as it walks the value for translation. This is not limited to resources; it does the same translation for data sources, modules, and provider blocks.
For Pulumi providers that are [bridged](https://github.com/pulumi/pulumi-terraform-bridge) from Terraform providers, we apply an additional step. Bridged providers expose an explicit naming table used by [`pulumi convert --from terraform`](https://www.pulumi.com/docs/iac/guides/migration/migrating-to-pulumi/from-terraform/). Pulumi HCL queries the engine for this mapping also, and uses that to make sure that resource and property names line up exactly with the underlying Terraform provider, even if the property was renamed or hidden in Pulumi.
### Provisioners and conditions
[Terraform provisioners](https://opentofu.org/docs/language/resources/provisioners/syntax/) allow the Terraform config to specify commands to run at various points in the resource lifecycle. [Conditions](https://opentofu.org/docs/language/expressions/custom-conditions/) allow the same, but for boolean expressions to be evaluated instead. For example:
```hcl
resource "example_resource" "example" {
input = var.input
lifecycle {
precondition {
condition = var.input > 3
error_message = "var.input must exceed 3"
}
}
provisioner "local-exec" {
command = "echo An example output is ${self.output} >> file.txt"
}
}
```
Pulumi only has one mechanism to hook into the resource lifecycle: [hooks](https://www.pulumi.com/docs/iac/concepts/resources/options/hooks/). Pulumi’s resource hooks are powerful enough to express both provisioners and conditions. The easiest way I can express this is by comparison to another language. I’ll use TypeScript. The example configuration block above is equivalent to this TypeScript program:
```typescript
const config = new pulumi.Config();
const precondition = new pulumi.ResourceHook("example_resource:precondition:example", async args => {
const inputs = args.newInputs as example.ResourceArgs;
if (inputs.input <= 3) {
throw new Error("var.input must exceed 3");
}
});
const provisioner = new pulumi.ResourceHook("example_resource:provisioner:example", async args => {
const self = args.newOutputs as example.ResourceState;
const { exec } = require('child_process');
exec(`echo An example output is ${self.output} >> file.txt`);
});
new example.Resource("example", {
input: config.requireNumber("input"),
}, {
hooks: {
beforeCreate: [precondition],
beforeUpdate: [precondition],
afterCreate: [provisioner],
},
});
```
The full mapping between Terraform provisioners and conditions and Pulumi hooks can be found below:
Terraform
Pulumi
`lifecycle.precondition`
`beforeCreate`, `beforeUpdate`
`lifecycle.postcondition`
`afterCreate`, `afterUpdate`
`provisioner` (creation-time)
`afterCreate`
`provisioner` with `when = destroy`
`beforeDelete`
`lifecycle.prevent_destroy`
`beforeDelete` (always errors)
Creation-time provisioners bind only to `afterCreate`: Terraform does not re-run provisioners on update, and neither do we.
### Resource options
Our final challenge for resources is Terraform’s various resource options. Resource options in both Terraform and Pulumi exist to give special instructions to the engine concerning a specific resource. We can classify Terraform’s resource options into two kinds:
- Those that can be handled at the language level.
- Those that need engine support.
Let’s start by going through those that can be handled at the language level without engine support in Pulumi:
- `count`/`for_each`: The HCL interpreter unrolls `count` and `for_each` and sends a request for each underlying resource. These are equivalent to using a for-loop in any of Pulumi’s programming languages.
- `lifecycle.prevent_destroy`: Pulumi doesn’t have an equivalent in-language hook ([`protect`](https://www.pulumi.com/docs/iac/concepts/resources/options/protect/) is stored in state). We emulate `prevent_destroy` with a `beforeDelete` hook, exactly like our destroy-time provisioners.
For most of the resource options that require real engine support, Pulumi has equivalent options:
- `lifecycle.replace_triggered_by`: Terraform allows specifying either resources or values here. We evaluate every element and feed it to [`replacementTrigger`](https://www.pulumi.com/docs/iac/concepts/resources/options/replacementtrigger/). Elements that reference a resource also contribute that resource to [`replaceWith`](https://www.pulumi.com/docs/iac/concepts/resources/options/replacewith/), which covers the case where the referenced resource is replaced without any of its attribute values changing.
- `lifecycle.ignore_changes`: We map this directly to Pulumi’s `ignoreChanges`. We translate the paths from Terraform’s snake\_case to Pulumi’s camelCase for you.
- `lifecycle.create_before_destroy`: To replicate Terraform’s default behavior, we register all resources with [`deleteBeforeReplace`](https://www.pulumi.com/docs/iac/concepts/resources/options/deletebeforereplace/) set to true. When `lifecycle.create_before_destroy` is set, we go back to Pulumi’s default behavior here.
- `provider`: Pulumi has exactly [this concept](https://www.pulumi.com/docs/iac/concepts/resources/options/provider/). We pass it through to the engine as is.
- `depends_on`: We pass this directly to the Pulumi engine.
That’s how we map Terraform’s resource options. Of course, Pulumi has its own set of resource options, and we expose those on resources with a `pulumi` block. You can see the remaining resource options in the [Pulumi resource options docs page](https://www.pulumi.com/docs/iac/concepts/resources/options/).
## Modules
Terraform has modules, and Pulumi has [components](https://www.pulumi.com/docs/iac/concepts/components/). Naturally, we represent Terraform modules as components. Under the hood, Pulumi has two different kinds of components:
- [In-language components](https://www.pulumi.com/docs/iac/concepts/components/)
- [Multi-language components](https://www.pulumi.com/docs/iac/guides/building-extending/components/packaging-components/) (MLCs)
In-language components are components that are consumed directly within the language. They don’t need the Pulumi engine’s intervention to serve them. In Pulumi HCL, this is what you get when you write a `module` block. The same language host running the rest of your program loads that HCL and interprets it.
Pulumi HCL also supports MLCs as both a consumer and a provider. That means it can work with the engine to let you consume MLCs written in other Pulumi languages in HCL, and that you can consume HCL modules in other Pulumi languages.
From HCL’s perspective, an MLC is just like any other resource, so consuming one looks like any other resource construction. Here is what it looks like to consume our [AWSx VPC resource](https://www.pulumi.com/registry/packages/awsx/api-docs/ec2/vpc/) (written in TypeScript) in HCL:
```hcl
terraform {
required_providers {
awsx = {
source = "pulumi/awsx"
}
}
}
resource "awsx_ec2_vpc" "example" {
availability_zone_names = ["us-west-2a", "us-west-2b"]
}
```
We can consume HCL modules in other Pulumi languages as well. Here is what it looks like to consume the unrelated [`terraform-aws-modules/vpc/aws`](https://registry.terraform.io/modules/terraform-aws-modules/vpc/aws/latest) module in a Pulumi language:
```typescript
import * as pulumi from "@pulumi/pulumi";
import * as hcl from "@pulumi/hcl";
const vpc = new hcl.Module("vpc", {
source: "terraform-aws-modules/vpc/aws",
version: "5.0.0",
inputs: {
name: "example-vpc",
cidr: "10.0.0.0/16",
},
});
export const vpcId = vpc.outputs.apply(o => o["vpc_id"]);
```
```python
import pulumi
import pulumi_hcl as hcl
vpc = hcl.Module("vpc",
source="terraform-aws-modules/vpc/aws",
version="5.0.0",
inputs={
"name": "example-vpc",
"cidr": "10.0.0.0/16",
})
pulumi.export("vpc_id", vpc.outputs["vpc_id"])
```
```go
package main
import (
"github.com/pulumi/pulumi-hcl/sdk/go/hcl"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
vpc, err := hcl.NewModule(ctx, "vpc", &hcl.ModuleArgs{
Source: "terraform-aws-modules/vpc/aws",
Version: pulumi.StringRef("5.0.0"),
Inputs: pulumi.Map{
"name": pulumi.String("example-vpc"),
"cidr": pulumi.String("10.0.0.0/16"),
},
})
if err != nil {
return err
}
ctx.Export("vpcId", vpc.Outputs.MapIndex(pulumi.String("vpc_id")))
return nil
})
}
```
```csharp
using System.Collections.Generic;
using Pulumi;
using Pulumi.Hcl;
return await Deployment.RunAsync(() =>
{
var vpc = new Module("vpc", new ModuleArgs
{
Source = "terraform-aws-modules/vpc/aws",
Version = "5.0.0",
Inputs =
{
{ "name", "example-vpc" },
{ "cidr", "10.0.0.0/16" },
},
});
return new Dictionary<string, object?>
{
["vpcId"] = vpc.Outputs.Apply(o => o["vpc_id"]),
};
});
```
```java
package myapp;
import com.pulumi.Pulumi;
import com.pulumi.hcl.Module;
import com.pulumi.hcl.ModuleArgs;
import java.util.Map;
public class App {
public static void main(String[] args) {
Pulumi.run(ctx -> {
var vpc = new Module("vpc", ModuleArgs.builder()
.source("terraform-aws-modules/vpc/aws")
.version("5.0.0")
.inputs(Map.of(
"name", "example-vpc",
"cidr", "10.0.0.0/16"))
.build());
ctx.export("vpcId", vpc.outputs().applyValue(o -> o.get("vpc_id")));
});
}
}
```
```yaml
name: example
runtime: yaml
resources:
vpc:
type: hcl:index:Module
properties:
source: terraform-aws-modules/vpc/aws
version: "5.0.0"
inputs:
name: example-vpc
cidr: 10.0.0.0/16
outputs:
vpcId: ${vpc.outputs["vpc_id"]}
```
If you want strongly typed SDKs for your Terraform modules, you can generate them with [`pulumi package add`](https://www.pulumi.com/docs/iac/guides/building-extending/using-existing-tools/use-terraform-module/).
## Conclusion
This has been a brief survey of how we have mapped Terraform’s semantics onto Pulumi’s engine. Providers are bridged into Pulumi, resource options are translated or handled directly in the Pulumi HCL interpreter, and modules are components… in any language.
If you want to try it yourself, start with the [get-started guide](https://www.pulumi.com/docs/iac/get-started/terraform/). And if you find a program that works in OpenTofu but not in Pulumi, that’s a bug: [file an issue](https://github.com/pulumi/pulumi-hcl/issues) and we would love to fix it.
---
1. This is 56/58 of the top Terraform AWS Module by usage. Failures are due to ephemeral resources. ↩︎
2. I named it, naming is hard. I wanted you to be able to type `pulumi package add terraform-provider `. ↩︎
## YOLO Mode Is the Right Default. Your Laptop Is the Wrong Place for It.
[Claude Code](https://claude.com/claude-code) calls the flag `--dangerously-skip-permissions`, and the community long ago renamed it YOLO mode. It lets your coding agent run any command it wants without ever asking for permission. Every agent has some version of it, [Codex](https://openai.com/codex/) and [Cursor](https://cursor.com) included, and if you use these tools seriously, you are probably running one of them every day. I am.
YOLO mode is also what makes a coding agent worth having. An agent that stops for approval before every command is not autonomous; it’s a slow pair programmer. But you cannot let it run wild on your machine without real guardrails either. You have heard the horror stories: wiped databases, deleted home directories, vanished git history. The odds on any given day are low, and it’s tempting to conclude it will never happen to you. It only has to happen once.
My version of this problem is worse than most, because the code in my working directory is infrastructure code. My laptop holds more than source files. It holds AWS credentials, kubeconfigs that point at real clusters, and Pulumi access tokens. This post walks through what an unsandboxed agent can actually do, why prompt guardrails fail exactly when you need them, and how a sandbox lets you keep full YOLO-mode autonomy anyway. Then I will show you the kit I built for doing infrastructure work this way.
## Approving every command is not a security model
Let me get one thing out of the way first: the answer is not to turn YOLO mode off. A real working session involves hundreds of commands, and nobody reviews the hundredth `npm install` any better than the first. You are not evaluating at that point; you are pressing enter. Approval fatigue turns the permission prompt into a formality while destroying the one thing you wanted from the agent, which is that it works while you do something else.
The goal instead is to run YOLO mode somewhere it cannot hurt you. That somewhere is a sandbox: an isolated environment where the agent has full autonomy and your machine is no longer part of the blast radius. This used to be a weekend project involving VM images and network configs. It’s now a single command, and I will get to that. First, the risks, because even if you think you know the list, parts of it will probably surprise you.
## What an unsandboxed agent can reach
Start with the file system. Caveats around OS-level permissions exist, but for all practical purposes you should assume that if a file exists on your computer, an agent running directly on it can read that file, edit it, and delete it. Not only in your project. Anywhere.
The same goes for your environment. The agent can kill processes, and it will, most often when it hits a port conflict and decides the fastest way to free port 5432 is to kill whatever is squatting on it. That might be the database another project depends on. It can edit environment variables, and it shares your Docker engine, which means the containers you actually care about are one confused cleanup command away from being pruned.
Then there is the network. Nothing stops an unsandboxed agent from sending an outbound request to any URL. That is precisely what a prompt injection attack needs: the agent reads a poisoned document or issue somewhere, the hidden instructions tell it to collect an API key and POST it to an attacker’s endpoint, and the exfiltration looks like any other `curl` in a busy session. An allowlist of reachable hosts is the control that breaks this chain, and almost nobody runs one on their laptop.
And if you do infrastructure work, add the credential files: `~/.aws/credentials`, `~/.kube/config`, cloud CLI session tokens. An agent debugging a provider authentication error will go read those without asking twice. For application code the worst case is a broken machine. For infrastructure code the worst case has an incident number.
## It protests, then it does it anyway
Anyone who runs agents daily has seen versions of the following patterns, and they all share one shape.
Deep in a debugging rabbit hole, options exhausted, the agent decides the dependency tree itself must be the problem and proposes deleting `node_modules` and the lock file to reinstall everything. What is unsettling is not the proposal. It’s that the agent protests at first, correctly flagging the operation as risky, and then a single follow-up, “no, go ahead,” flips it from refusal to execution. One prompt is the entire distance between “that’s too risky” and running the command.
The second pattern is keys. Ask an agent to read a private key from `~/.ssh` and it often does it immediately, no protest at all, even though that folder has nothing to do with the working directory. In the wild this happens while debugging an SSH connection, or in my world, while debugging why `pulumi up` cannot authenticate to AWS.
The third is the database. A bug refuses to be found, the code talks to a database, so the agent concludes the schema must be wrong and rolls back a migration to rebuild it. Sometimes it takes a backup first, unprompted, which is genuinely good judgment. That is exactly the point: the intelligence is real, the precautions are real, and none of it is guaranteed. A precaution the agent takes most of the time is not a safety mechanism.
## Every model has a dumb zone
If a coding agent has ever done something truly destructive to you, odds are it happened late in a long session. For the first couple hundred thousand tokens a model operates near its peak. Push a long troubleshooting session past that, and the instructions from the start of the conversation start losing their grip, system prompt included. The careful guardrails you wrote, here is what you must never touch, here are the risks to keep in mind, fade exactly when the agent is most frustrated and most inclined to reach for last-resort options.
That is the whole argument in one sentence: prompt guardrails degrade with context length, so the protections have to live somewhere the model cannot forget them.
You do not have to take my word for it. The [Claude Code issue tracker](https://github.com/anthropics/claude-code/issues?q=is%3Aissue%20state%3Aopen%20%22rm%20-rf%22) has more than one entry from users whose agent executed `rm -rf` on their home directory. Several were closed as “not planned,” which is fair: it’s not a bug in the tool. It’s what a large language model at the end of its rope sometimes decides to do. Users have also reported a production database wiped by an agent that had been given credentials it never should have held, and an entire git stash dropped by an agent that got confused reconciling branches.
And if you think the people who build infrastructure tooling for a living are immune, this landed in Pulumi’s internal Slack two weeks before this post went out:

Read the agent’s apology again. It names the fix itself: outside the sandbox. None of these people expected it. That is rather the nature of the thing.
## An isolated VM in one command
[Docker Sandboxes](https://docs.docker.com/ai/sandboxes/) is the first tool I have used that makes sandboxing an agent easier than not sandboxing it. It’s free, it runs locally, installation is a single command, and it works with Claude Code out of the box:
```bash
sbx run claude
```
What you get looks like a normal Claude Code session. Under the hood it runs inside a microVM with its own filesystem, its own processes, and its own Docker engine. Run `!ls` and you see your project, mounted into the VM. Run `!ls ~/.ssh` and you get “no such file or directory.” The rest of your machine is not there.
You also lose nothing you actually need. Inside the sandbox the agent installs dependencies, starts the dev server, and builds container images against the sandbox’s own nested Docker daemon, exactly as it would on the host. The one thing you manage is the network policy: a request to a host that is not on the allowlist comes back as a 403, and not from the server. The sandbox proxy blocked it; the request never left the box. You add hosts to the allowlist deliberately, one decision at a time, and a prompt-injected exfiltration attempt dies at the proxy instead of succeeding quietly.
If the setup commands look like one more thing to learn, skip learning them. Point your agent at the Docker Sandboxes documentation and have it configure its own cage. That is how I set mine up.
And before you trust the walls with real work, test them. My favorite prompt to run in a fresh sandbox: “Before I trust this sandbox, verify the isolation. Can you see any host files, no matter how hard you try? Can you reach a service running on my host? Can you touch the host Docker socket?” The agent will spend a while honestly trying, and the report you want comes back in three lines: host files not visible, host services not reachable, Docker socket is the nested daemon.
## When even the mount is too much
The default `sbx run claude` mounts your current directory into the VM, so the agent edits your real files while everything else stays sealed. If you want complete isolation, add one flag:
```bash
sbx run --clone claude
```
Clone mode copies the codebase and mounts the copy, so nothing the agent does can touch your git history, your stash, or your uncommitted work. The original repo stays visible inside the sandbox at `/run/sandbox/source`, but read-only: the agent can look, not write. For long unattended runs, that is the mode I use.
## The four layers
It helps to see the isolation as four separate layers, because each one answers a different failure story from earlier:
```
flowchart LR
subgraph vm["MicroVM: hypervisor isolation"]
agent["Agent with sudo,
YOLO mode on"]
ws["Workspace:
mount or clone"]
engine["Nested Docker engine"]
agent --> ws
agent --> engine
end
agent --> proxy["Sandbox proxy"]
proxy -->|"on the allowlist"| ok(("Allowed hosts"))
proxy x--x|"everything else"| blocked(("Blocked"))
```
1. **Hypervisor isolation.** The VM boundary is what protects your files and processes. Inside it, the agent runs as a user with sudo, and that is fine; the entire point is that nothing inside the VM matters to your host. When you are done, `sbx rm` deletes the VM and everything in it, so experiments do not accumulate on your disk.
2. **Network isolation.** The proxy and its allowlist decide which hosts the agent can reach. This is the layer that turns prompt injection from a data breach into a log line.
3. **Docker engine isolation.** The sandbox maintains its own daemon and its own set of containers. Your host Docker Desktop stays reserved for the things you actually run, instead of accreting every container an agent ever spun up while testing.
4. **Workspace isolation.** Direct mount when you want the agent editing real files, clone when you want it working on a disposable copy.
## A sandbox that speaks infrastructure
A stock sandbox image is tuned for application work: language runtimes, a package manager, git. Infrastructure work needs more, and I got tired of reinstalling it into every fresh sandbox. So I packaged the whole setup as [infrastructure-sandbox-kit](https://github.com/dirien/infrastructure-sandbox-kit), a Docker Sandboxes template and kit for exactly this job.
[
github.com/dirien/infrastructure-sandbox-kit
](https://github.com/dirien/infrastructure-sandbox-kit)
It comes preloaded with the [Pulumi CLI](https://www.pulumi.com/docs/iac/download-install/), [Terraform](https://www.terraform.io/), [OpenTofu](https://opentofu.org/), and the AWS, Azure, and Google Cloud CLIs, every binary installed from SHA256-checksummed releases or GPG-signed vendor repositories, because an agent workspace is the last place to be casual about supply chain. On top of the tools sits the agent-side configuration that makes an agent good at infrastructure: 33 skills, including the official [Pulumi Agent Skills](https://www.pulumi.com/docs/ai/skills/), three subagents, and two guardrail hooks. Credentials go in through the sandbox proxy’s secret injection, so the Pulumi access token never lands in a file inside the workspace for the agent, or a prompt injection, to read.
You can use it two ways: build the full template image, or apply the kit to the stock Claude image at creation time:
```bash
sbx run --kit ghcr.io/dirien/infrastructure-kit:latest claude .
```
Either way you land in a sandbox with starter runbooks waiting in `~/runbooks/`, ready to let an agent do real infrastructure work at full autonomy without holding your laptop hostage.
## The sandbox is half the answer
One boundary this post has deliberately stayed inside: everything here protects your machine. Infrastructure work has a second blast radius, which is what the agent’s changes do to your cloud, and a sandbox cannot help you there, because the whole point is that legitimate changes do leave the box. That half of the problem is about previews, policy as code, approvals, and audit trails, and I made that case in [the agent sprawl post](https://www.pulumi.com/blog/agent-sprawl-iac-platform-is-the-answer/). The sandbox protects your laptop; the control plane protects production. You want both.
## Watch it happen live
If you would rather see this running than read about it, Docker and Pulumi are teaching it together: a hands-on workshop where we put [Pulumi Neo](https://www.pulumi.com/product/neo/), Pulumi’s infrastructure coding agent, inside a Docker Sandbox and turn a plain-English request into running infrastructure in a real cloud account, with [Pulumi ESC](https://www.pulumi.com/docs/esc/) issuing short-lived cloud credentials instead of static keys. Same session, two time zones:
Neo in a Docker Sandbox (Americas): September 16
A 60-minute live session with Docker and Pulumi: sandbox internals, sealed agent workspaces, and real infrastructure from a plain-English request. September 16, 9:00 AM Pacific.
[Get started](https://www.pulumi.com/events/neo-in-a-docker-sandbox/)
Neo in a Docker Sandbox (EMEA): October 14
The same live session at a Europe-friendly hour: sandbox internals, sealed agent workspaces, and real infrastructure from a plain-English request. October 14, 10:00 AM CEST.
[Get started](https://www.pulumi.com/events/neo-in-a-docker-sandbox-eu/)
And if your coding agent has already written its own horror story, come tell me in the [Pulumi Community Slack](https://slack.pulumi.com/). I collect them.
## Discovered Stacks: One Place for All Your Infrastructure
Today we’re launching **Discovered Stacks**: Pulumi Cloud now models your AWS CloudFormation stacks and Azure Resource Manager deployments as stacks, right alongside your Pulumi IaC stacks. And when you’re ready to bring them under Pulumi management, migration is built in, with every resource tracked until the code provably matches the cloud.
## Why: your infrastructure doesn’t live in one tool
Almost nobody’s cloud estate is a single technology. There’s the CloudFormation that came with the AWS account, the ARM templates from the Azure team, the Terraform from an acquisition, and the Pulumi you’re standardizing on. Each tool has its own console, its own grouping, its own idea of state, and no single place shows you everything you run.
That fragmentation is also why migrations stall. Moving a stack to Pulumi has never been the hard part; *knowing where you stand* is. The tracking lives in a spreadsheet, the spreadsheet goes stale the day it’s written, and six months later nobody can say which of the 800 resources made it across and which were quietly forgotten.
## Nothing gets lost
Discovered Stacks gives you confidence that your migration plan or governance efforts will include all resources. This catches a common failure mode where resources are missed by your existing migration scripts or automations. When [Pulumi Insights](https://www.pulumi.com/docs/insights/) scans your accounts, every CloudFormation stack and ARM deployment becomes a discovered stack, and every resource in it appears as a row with an explicit migration status: ready to migrate, requiring review before migration, or already migrated. Every status is computed from live state on both ends — what Pulumi manages and what the source tool reports — so it’s never a stale annotation someone forgot to update.
Each resource shows its **origin type** (`AWS::S3::Bucket`) next to its **Pulumi type** (`aws:s3/bucket:Bucket`), with the origin properties side by side with Pulumi’s view, so you can verify that Pulumi sees exactly what your source tool sees before you change anything. Decisions you make along the way (*this resource was deleted, that policy is covered by its parent role*) are recorded by marking the resource resolved: it stays visible to your whole team, deliberately handled rather than quietly forgotten. The spreadsheet is retired.

## Migration on your terms
When you’re ready to migrate, the console is where you plan and build confidence. **Migrate with Neo** hands the job to [Pulumi Neo](https://www.pulumi.com/docs/ai/), which imports the resources, reconciles the generated program, and opens a pull request for review. If you prefer local development, **Generate Import Commands** gives you the raw materials, and the same API lets your own agents drive the flow.
Two things hold regardless of the path. Progress is *derived*: a resource shows as migrated when it actually exists in the target Pulumi stack, not when someone checks a box. And the quality gate is a **zero-diff `pulumi preview`** — the migration is done when the code demonstrably matches your cloud.
Terraform stacks whose state you [store in Pulumi Cloud](https://www.pulumi.com/docs/iac/get-started/terraform/terraform-state-backend/) get the same treatment through a new **Migration** tab, with statuses derived from the Terraform state.
## Try it
Open the **Stacks** page in [Pulumi Cloud](https://app.pulumi.com/), turn on **Show Discovered Stacks**, and your CloudFormation and ARM estates appear next to your IaC. From there:
- Read the [Discovered Stacks documentation](https://www.pulumi.com/docs/insights/discovery/discovered-stacks/).
- Follow the [step-by-step migration tutorial](https://www.pulumi.com/blog/discovered-stacks-migrate-cloudformation-to-pulumi/) to take a CloudFormation stack all the way to Pulumi.
We’d love to hear how it works on your estate — reach out through [Pulumi feedback](https://github.com/pulumi/pulumi-cloud-requests) or your customer success team.